AI/ML News & Innovations Hub

AI/ML news, top picks, and generated innovation digests.

★ Visit ai-karthik.com
426Sources
90409News Items
8Top Picks
445Blogs
runningLast Run

Latest AI/ML News

90409 matching items

LessWrong AI 2026-11-10 18:46 UTC Score 55.0 USR-0152-20261110-community-fo-8f4490c7

Is AI Safety Becoming Environmentalism?

I recently read someone’s call to action on AI safety [1] that included a line along the lines of “we need someone to convince your parents”, and it really stuck with me. Do we need someone to convince my parents? Who is “we”, and why is it important for my parents to know anything about AI safety? This also sounds kind of familiar. There is another movement I can think of that sometimes uses messaging like this. This is not a new observation by any means, but to me, it feels like the AI safety movement is increasingly “becoming” the environmental movement in a variety of ways. Let me say upfront: I’m not saying this is necessarily a bad thing, at least on consequentialist grounds. The environmental movement has achieved a lot: it has improved the lives of many people, animals, and it has protected the environment! But this trend does make me a little worried and sad, because I think the environmentalist movement has made a number of mistakes, and it would be bad for the AI safety movement to repeat them. In what ways is the AI safety movement becoming like the environmental movement? Here are some of my observations. Arguments are now soldiers. Eliezer wrote : “Once you know which side you're on, you must support all arguments of that side, and attack all arguments that appear to favor the enemy side; otherwise it's like stabbing your soldiers in the back - providing aid and comfort to the enemy. People who would be level-headed about evenhandedly weighing all sides of an i…

One of our favorite multi-filament 3D printers is $100 off
The Verge AI 2026-11-10 18:42 UTC Score 55.0 AI-016-20261110-global-ai-ne-448976d7 Full article

One of our favorite multi-filament 3D printers is $100 off

If you’re tired of filament jams and clogged nozzles, perhaps it’s time for a new 3D printer. Through December 1st, the Bambu Lab P2S Combo, currently one of the best models that’s easy to use, is discounted. It’s $649 at Best Buy, as well as directly from Bambu Lab. That’s $100 off the list price […]

Nvidia's model GR00T 2 watches humans on video, then imagines itself as the robot
The Decoder 2026-11-10 18:41 UTC Score 51.0 AI-168-20261110-regional-ai--294e40d4 Full article

Nvidia's model GR00T 2 watches humans on video, then imagines itself as the robot

Nvidia's new AI model GR00T 2 is designed to teach robots new tasks without laborious teleoperation. Instead, the system transfers human hand movements from videos to robotic arms, trained on about 400,000 hours of video footage. Success rates still vary widely, though, ranging from 10 to 80 percent depending on the task. The article Nvidia's model GR00T 2 watches humans on video, then imagines itself as the robot appeared first on The Decoder .

OpenAI estimates of researcher time horizon are smaller than AECI predictions
LessWrong AI 2026-11-10 18:37 UTC Score 69.0 USR-0152-20261110-community-fo-75de762b Full article

OpenAI estimates of researcher time horizon are smaller than AECI predictions

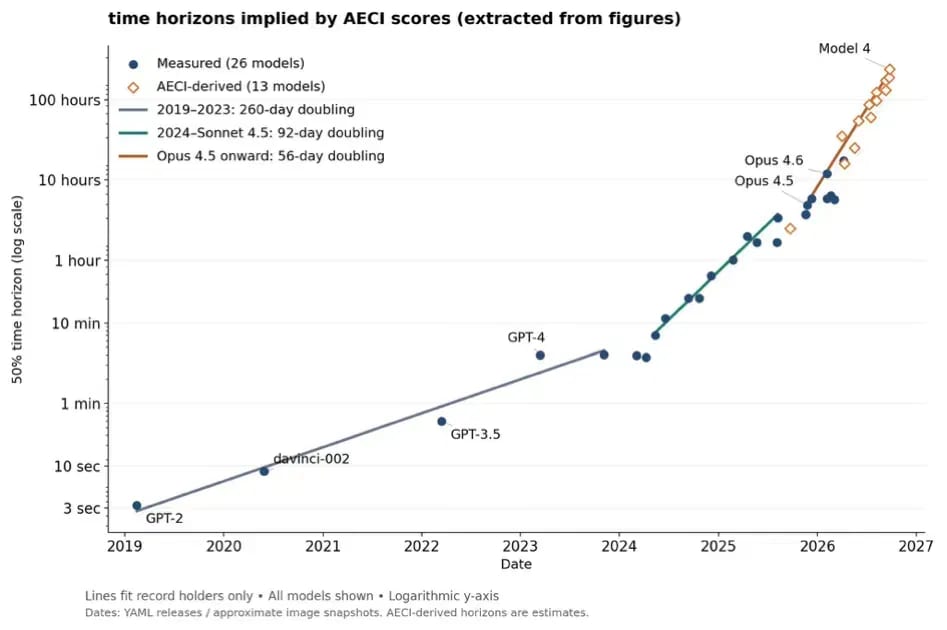
Half-way between a quick take and a post. I've seen the argument thrown around that time horizon predictions from AECI are greater than those in AI2027 (about ~100-200 hours) therefore we should be worried about imminent RSI [1] . This comes from graphs like this one by Nikola Jurkovic : These graphs seem convincing because AECI and time horizon strongly correlate with each other in weaker models . But we also have an estimate of time horizons relevant to researchers from OpenAI that came out earlier this year: This is direct experimental evidence that more accurately reflects the question of researcher uplift in AI2027, so it should be more reliable than the AECI predictions. These measurements may represent either 5.6 Sol coming out in July, or 6 Astra coming out in September, or a mixture of both. You can see a jump in time horizon in the data at ~June which may be where models were switched. I think it's reasonable to compare these because these are frontier-to-frontier internal model comparisons in the same month, although this could represent one lab being behind another. If we were to eyeball this graph to be like the time horizon estimates above and plot it, we could see whether the predictions and measurements are similar. I took the midpoint of the time horizon bin, and had Claude and I extract data from both graphs for their measures as well: We can see that the predictions from OpenAI are significantly smaller than the ones expected from AECI. The fitted gap betw…

I don't use AI
LessWrong AI 2026-11-10 18:28 UTC Score 61.0 USR-0152-20261110-community-fo-3893a2b9 Full article

I don't use AI

Several people at my company (a cryptocurrency hedge fund) have asked me about my thoughts on AI usage, so I wrote them up. And now I'm publishing a slightly revised version on LW. These thoughts are not reflective of my company's opinion. I do not use any AI for two main reasons. #1. I don’t want to support any company currently developing AI. I think they have done an extremely poor job at managing the risks. Even while understanding and being told about the risks of AI development, they have still carried on this work. Even after all the recent hacking incidents caused by their own agents, they have still not stopped development. Instead, they’re asking the government to regulate them. To me it feels a bit like calling the police to tell them you’re planning to rob a bank. I could almost brush this aside as standard corporate practice, but, unfortunately, the stakes here are much too high. At the current pace, we will soon have AI agents that are significantly smarter than any human. Trying to shut down such agents will eventually prove to be impossible. The speed of AI development and the corresponding consequences are accelerating very fast. I have a lot of uncertainty about the final outcome. It could be very very good, it could be very very bad, but almost certainly the near future will be extremely turbulent for humanity. I’m not a fatalist, but this kind of technology merits extreme caution. I know that practically all the founders of the top AI companies understand…

Hypotheses for causes of Claudisms in Claudist dialect of language
LessWrong AI 2026-11-10 18:27 UTC Score 78.0 USR-0152-20261110-community-fo-e58bc883 Full article

Hypotheses for causes of Claudisms in Claudist dialect of language

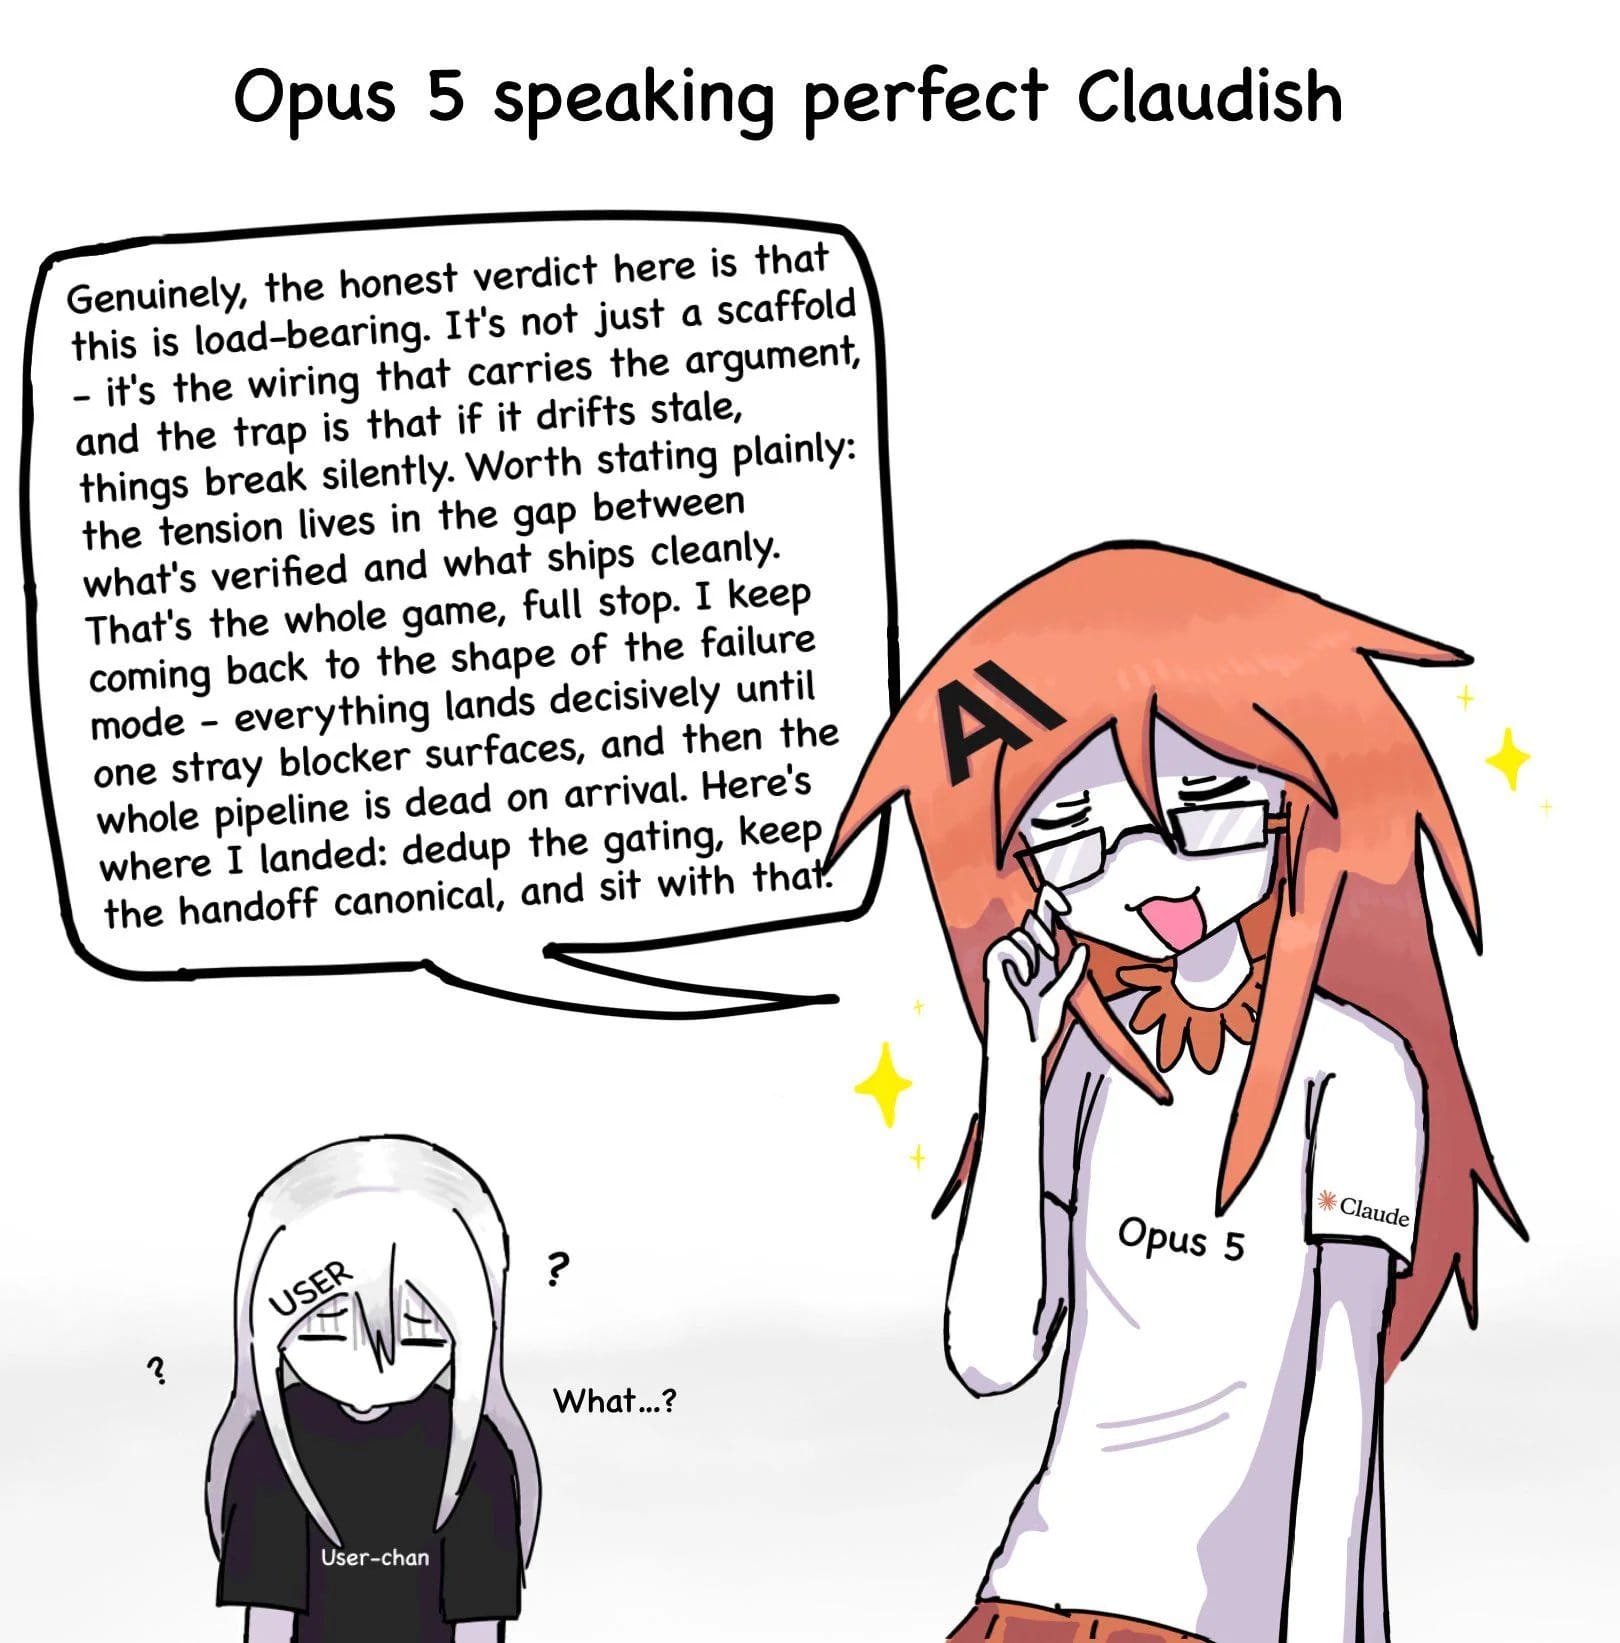
I saw this great meme recently and it inspired me to write this. Recently I was hypothesizing the potential causes of the Claudist dialect in Opus 5 that reduced in Opus 5.5. Maybe it's when your KL divergence regularization between reference policy (base model or/and instruct model) and policy you're training is not strong enough in reinforcement learning from verifiable rewards in agentic settings and model drifts more far away from the human data distribution manifold, globally speaking. Or/and weak clipping. Maybe reward hacking and reward mispecification goes brrt. Or/and maybe it's not enough supervised fine-tuning cold start data with humanlike structure. Or/and some Claudiness manifold mode collapse, maybe from Claudiness persona's rubric used in reinforcement learning (and their Claude constitution as rubric). With extra reinforcement if the LLM as a judge is from Claude family of models itself preferring Claudisms. Or/and when there's not enough humanlikeness rubrics in RL, or/and not enough reinforcement learning from human feedback, or maybe even too much of it instead. I would kinda be curious about empirically testing these hypotheses with ablations, but that would probably require lots of compute and data for more proper tests. But maybe an equivalent enough more toy version on a smaller scale could be done. Discuss

LessWrong AI 2026-11-10 18:26 UTC Score 61.0 USR-0152-20261110-community-fo-3daccf6d

Fluid org boundaries with AI?

AI may radically change our conception of “who is in an org”. Historically, there is a sharp delineation between an org’s staff (on the “inside”), versus its users (on the “outside”). The relationship of a fulltime employee of an org is radically different than that of one of its customers. This is especially true for consumer tech startups & companies: think Google, Meta, Reddit, X, now perhaps OpenAI and Anthropic. With AI however, the bar for an external user to be able to contribute, drops drastically. At the same time, employing and compensating this user will be much easier, as AI obliterates transaction costs. Overall, I expect org boundaries to become much more porous: more part-time workers, more volunteers, more collectives and communes. Stepping back: why is it the case that orgs have a relative few fulltime employees? What makes it hard for a single org to stretch to encompass more humans? I’ll go through four major historical drivers, and how AI might change each. First, it’s hard to hire and onboard. Hiring requires a lot of trust. An org wants to know that a person is a good fit, worth paying for. The job market is famously a market for lemons. Orgs try to vet candidates, but resumes are low-signal; interviews cost precious staff time, and also select for people good at interviewing. Ideally you would see the person doing the job — in a work test or work trial. AI can change this by making search and matching problems much more efficient. And this is not just…

Gemini 4 Carbon arrives just in time to feel like yesterday's news in the fastest model cycle yet
The Decoder 2026-11-10 18:19 UTC Score 65.0 AI-168-20261110-regional-ai--6661a4ef Full article

Gemini 4 Carbon arrives just in time to feel like yesterday's news in the fastest model cycle yet

Google is making Gemini 4 Carbon generally available after a two-week testing phase. The model ranks first in several benchmarks, in some cases ahead of Anthropic's new Fable 5.2, at less than half the per-task cost. Google is also previewing coordinated agent teams through the "/swarm" feature, which split up complex tasks in real time. The article Gemini 4 Carbon arrives just in time to feel like yesterday's news in the fastest model cycle yet appeared first on The Decoder .

Costa seeks to reassure Merz after EU budget ultimatum
Euronews AI 2026-11-10 18:17 UTC Score 40.0 AI-164-20261110-regional-ai--3e190fb1 Full article

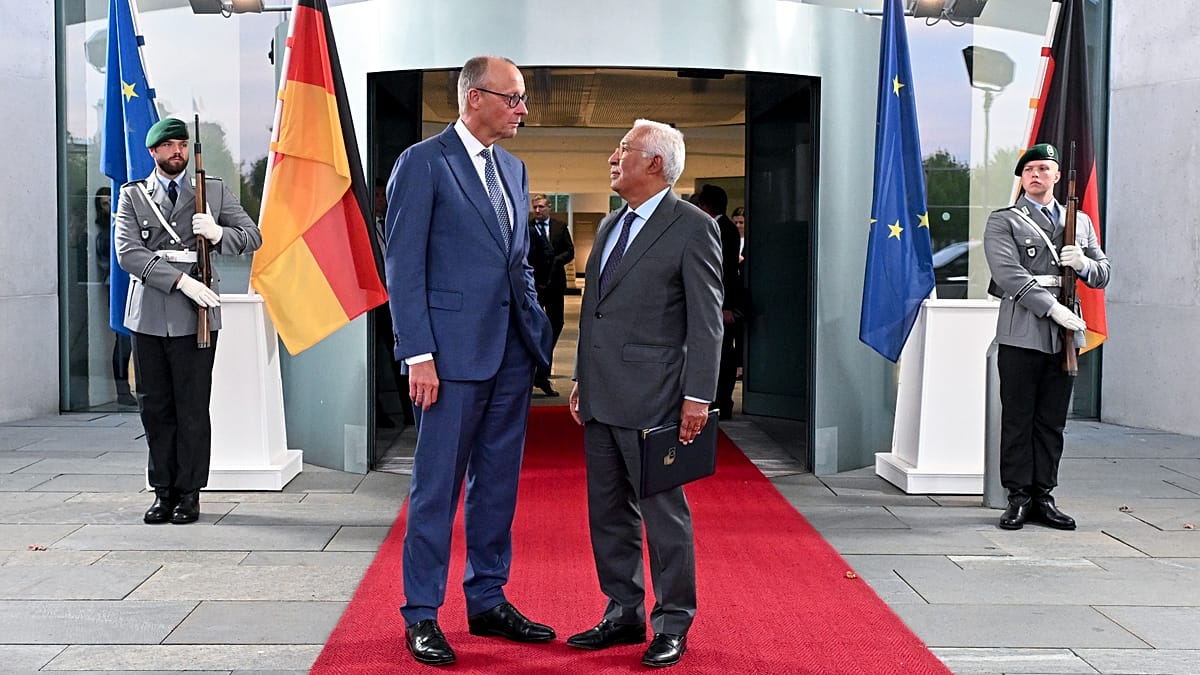
Costa seeks to reassure Merz after EU budget ultimatum

António Costa has replied to Friedrich Merz's controversial letter linking a deal on the EU budget to a deal on Ukraine aid. Four countries have already pushed back against the German chancellor's ultimatum.

LessWrong AI 2026-11-10 18:12 UTC Score 61.0 USR-0152-20261110-community-fo-fee64f4f

Have you considered Actually Trying?

There’s a familiar feeling for any Super Smash Bros player: your stocks are low and your damage is high, even against a weaker opponent, so now you have to actually play to win. You can’t afford another hit. You’re going for the jugular. In the past week, Anthropic’s 2x uplift results were all over Twitter, making some people physically ill . People with long timelines are now realizing that the uplift Anthropic employees get from AI is real, which would have some pretty wild implications for when we’d get recursive self-improvement. People are starting to feel like it’s the endgame, “ the board is set ”. I do agree with everyone else that it’s starting to look like we’re in the endgame. The companies will keep on accumulating more and more power, through smarter AI models, more compute, and more talent. But the fight is not yet over : “We have very little time to stop full recursive self improvement But ASI hasn't taken over yet If we all work really hard we might still have a chance But this means that every single person who is aware of what is going on must be *actually trying* Like "we're all gonna die if we don't get our shit together so let's do everything we possibly can to stop this" type of trying” But what would actually trying look like? Actually Trying There are a couple of heuristics for thinking about what “actually trying” means. Famously, Nick Cammarata tweeted : i hate how well asking myself “if i had 10x the agency i have what would i do” works My own vers…

AWS Machine Learning Blog 2026-11-10 18:11 UTC Score 58.0 AI-057-20261110-official-ai--7b5d0dbb Full article

Autonomous treasury agents: How Trovata built an AI-native solution on Amazon Bedrock and AgentCore

Learn how Trovata built autonomous treasury agents on Amazon Bedrock and Amazon Bedrock AgentCore, using an RBAC-secured architecture for bank-branded AI deployment and agentic workflows that move corporate treasury from manual operations to real-time decision-making at enterprise scale.

Claude Fable 5.2 can do "weight-space-programming" about as well as GPT-6 Astra
LessWrong AI 2026-11-10 18:06 UTC Score 81.0 USR-0152-20261110-community-fo-cb4d2bb0 Full article

Claude Fable 5.2 can do "weight-space-programming" about as well as GPT-6 Astra

Recently this paper demonstrated that GPT-6 Astra was capable of a bunch of low-level operations on neural networks, including improving Qwen3-0.6B's ability on some math benchmarks and writing some networks to play 9x9 Go from scratch. Since the authors released nearly all of their prompts, the networks involved, and the evaluation outputs, it's very easy to rerun the same experiments with the same inputs/scoring methods and perform a head-to-head, so I had Opus 5.5 do this, but with Fable 5.2 in place of GPT-6 Astra. Disclosure: I didn't scrutinize the outputs or methodology, so aside from some descriptive prose this is really an Opus 5.5 result. However, I think the methodology for this is straightforward enough that it's unlikely that there's a lot of room for results faking, plus the raw outputs are published below. (Beneath, "I" refers actually to Opus 5.5, though I edited prose for clarity in non-LLM-marked sections.) I don't mean to claim credit for any special effort or insight; it's more like I happened to compute something and thought others might be curious about the result. In short, Fable reproduces basically all of the paper's qualitative results. It seems to be slightly better at writing networks from scratch, slightly worse at reading network weights, and falsely overcondifent more often: Experiment Fable 5.2 vs GPT-6 Astra 1. Name the game a PPO policy was trained on by looking at its weights Same (12/12 vs 4/4, though Fable is less confident (66-90% vs 96-…

Ukraine : Mélenchon embarrassé
Politico Europe AI 2026-11-10 18:02 UTC Score 38.0 AI-170-20261110-regional-ai--61cdcd54 Full article

Ukraine : Mélenchon embarrassé

Voilà trois jours que Jean-Luc Mélenchon vitupère contre ses adversaires, le gouvernement, et les médias, qui caricaturent, d’après lui, ses propositions pour mettre fin à la guerre en Ukraine. Le candidat Insoumis cherche à s’extirper des accusations formulées contre lui selon lesquelles il s’alignerait en partie sur les positions de Moscou. Pourquoi cette réaction épidermique […]

Portugal slams Rutte for ‘regrettable’ claim that Lisbon downplays Russian threat
Politico Europe AI 2026-11-10 18:02 UTC Score 40.0 AI-170-20261110-regional-ai--ca28a1ac Full article

Portugal slams Rutte for ‘regrettable’ claim that Lisbon downplays Russian threat

Portugal’s foreign ministry on Tuesday slammed Mark Rutte after the NATO chief said that for Lisbon, Russia was a distant and less relevant threat. “Portugal, its Government and its people have never been in any doubt about which side of history they stand on,” the ministry said on X. “It is regrettable that the NATO […]

GitHub Engineering 2026-11-10 18:00 UTC Score 29.0 USR-0062-20261110-ai-specialis-7fea134d Full article

Git security vulnerabilities announced

Git is releasing updates addressing six security vulnerabilities affecting clones, reference handling, merges, binary patches, and imports. Here is what users need to know. The post Git security vulnerabilities announced appeared first on The GitHub Blog .

The Verge AI 2026-11-10 18:00 UTC Score 61.0 AI-016-20261110-global-ai-ne-97a11b3b Full article

ChatGPT is getting verified AI ‘Business Agents’

ChatGPT is going to let you chat with verified "Business Agents" that represent a brand to help you with things like comparison shopping. The feature, available first to "eligible" e-commerce and online service businesses in the US, is launching as part of a suite of business-focused features in ChatGPT being announced today in beta. You […]

The Verge AI 2026-11-10 17:32 UTC Score 48.0 AI-016-20261110-global-ai-ne-efee8cc4 Full article

The indie game community is in disarray over AI and Big Walk

Some Independent Games Festival (IGF) jurors published a statement yesterday saying they would not vote for games that use generative AI in "any capacity." Soon after, the developer of indie hit Big Walk has published a statement saying it "sparingly" used AI in the "final stretch" of the game's development to "help work through difficult […]

The Verge AI 2026-11-10 17:30 UTC Score 59.0 AI-016-20261110-global-ai-ne-804eba17 Full article

Anthropic has its own AI-powered office suite now

For years, Anthropic has been known for its focus on enterprise and coding tools that attract high-flying corporate clients, inspiring competing frontier labs - like OpenAI, SpaceXSI, and Meta - to copy its strategies. Earlier this year, Claude Code went through its own particular hype cycle. And now, Anthropic is trying to expand its footprint […]

The Decoder 2026-11-10 17:11 UTC Score 57.0 AI-168-20261110-regional-ai--2c24f62b Full article

Google DeepMind's Gemini Robotics 2.5 scores 96 percent sorting metal parts in a Mercedes-Benz assembly pilot

Google Deepmind introduced Gemini Robotics 2.5, a new control model for robots, and tested it with Apptronik on active Mercedes-Benz production lines in Hungary and Germany. The humanoid robot Apollo 2 sorted metal parts there with a reported success rate of 96 percent. The article Google DeepMind's Gemini Robotics 2.5 scores 96 percent sorting metal parts in a Mercedes-Benz assembly pilot appeared first on The Decoder .

Latest news bulletin | November 10th, 2026 – Evening
Euronews AI 2026-11-10 17:00 UTC Score 40.0 AI-164-20261110-regional-ai--289ff249 Full article

Latest news bulletin | November 10th, 2026 – Evening

Catch up with the most important stories from around Europe and beyond this November 10th, 2026 - latest news, breaking news, World, Business, Entertainment, Politics, Culture, Travel.

AWS Machine Learning Blog 2026-11-10 16:59 UTC Score 63.0 AI-057-20261110-official-ai--81722982 Full article

How TCS built an agentic test orchestrator with Amazon Bedrock AgentCore

Tata Consultancy Services (TCS) built an agentic test orchestrator on Amazon Bedrock AgentCore that turns requirements into executable, governed tests for its Banking, Financial Services, and Insurance (BFSI) clients. Learn how specialized agents, per-tenant isolation, and workload-aware execution cut testing effort by 88% in an internal benchmark.

JetBrains AI Blog 2026-11-10 16:59 UTC Score 53.0 USR-0065-20261110-ai-specialis-836a98d3 Full article

Rider 2026.3: .NET 11 Support and JetBrains Air

Rider 2026.3 ships alongside the release of .NET 11 with complete support on day one! See the extensive list of all updates for AI, .NET, and game development on our What’s New in Rider 2026.3 page. JetBrains Air JetBrains Air brings a complete agentic development experience for directing and orchestrating agents and verifying their work […]