Nvidia scandal raises export risks for South Korean chipmakers
No new US restrictions yet, as questions emerge over AI supply chain safeguards.
AI/ML news, top picks, and generated innovation digests.
90413 matching items
No new US restrictions yet, as questions emerge over AI supply chain safeguards.
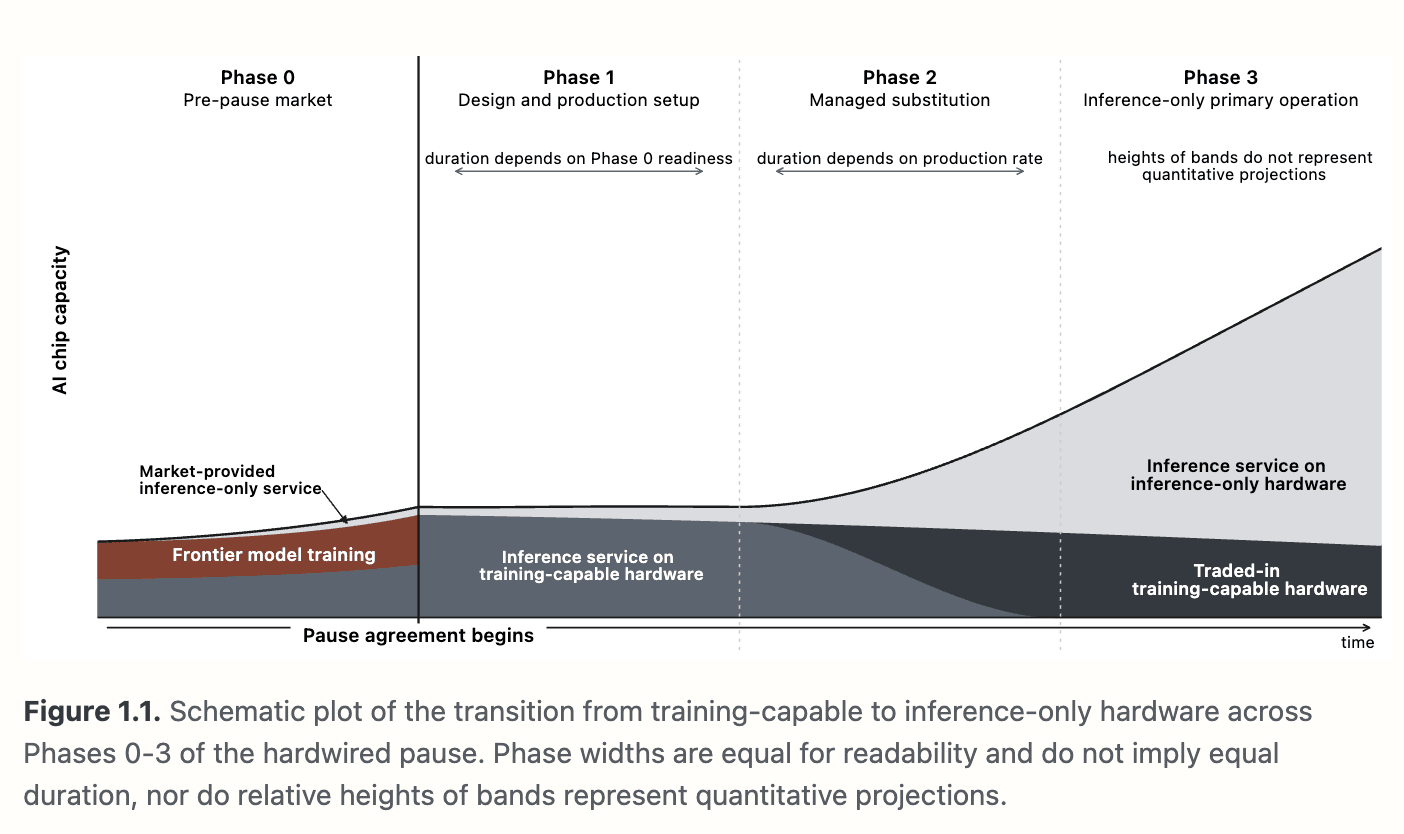
I'm part of a team of 26 researchers that recently released a 212-page paper proposing a new plan for pausing AI, the "hardwired pause." [1] The paper is called " The Feasibility of a Hardwired Pause of Frontier AI Training ." Our analysis suggests that, under this hardwired pause plan, we could probably pause for at least a decade if we start stopping within the next year, and this could likely be extended indefinitely. I expect this to be possible without trusting China or tanking the economy. Note: I am speaking for myself and not the other 25 authors. The working group is led by Will Fithian and Wesley Holliday, and the work continues. I currently think: The best plan is to pause/ stop AI , i.e. have an immediate , indefinite, international moratorium on frontier AI development. And importantly, this is technically easier than more nuanced international regulation . A hardwired pause is probably the best plan out there for how to do this (except maybe it doesn't go far enough). This paper is likely the most in-depth analysis of pause feasibility in existence. Discussion and disagreement on any of these is very welcome! What's a hardwired pause? A hardwired pause basically means: Stop making chips that can be used to train new AI models. Only make chips that can only be used to run inference on existing AI models (or that aren't AI accelerators at all). We call these "inference-only chips"; I'm also calling them "hardwired chips." This is an instance of an "inference-only…
Party senators skeptical of John Thune’s leadership don’t appear to have the votes to delay his reelection — but fractures are emerging.
There is a TL;DR at the end. The heaven button: You wake up one day and find a button in front of you, with a proof next to it. The proof says that pressing the button will kill everyone on the planet and send them all to heaven. Would you press it? It seems too good to be true. You think it must be a dream. It can't possibly be true. You go through the proof, and it seems correct. But what if you were under the influence of some drug? But the stakes are very high, so you use software you trust to formalize it in Lean, and you run it on a machine you trust. Lean says the proof is correct so now you are more convinced. But you start doubting yourself again. What if someone compromised the formalization software, or introduced a bug in Lean? So you check Lean's code, and run the proof on a second machine with an independent checker. It passes again. But each of these checks could fail in the same way the first one could. So you go further and formally verify Lean and the formalization software themselves. They pass. But now you are doubtful of the tool you used to verify this. What if that was compromised by someone? Every new check needs another check behind it, and at some point you have to stop and decide. Would you press it? A common belief in AI labs and AI safety is that handing control to some general superintelligence would be fine, if we have a formal proof of alignment. That, in my opinion, is saying yes to the same button, except there is no proof yet, only the hope…


During Paramount Skydance's latest earnings call, CEO David Ellison said "it's hard to imagine" AI won't have a bigger impact on the film industry than CGI. In response to a question about the company's outlook for AI, Ellison said: "I think when you zoom out and look at production, AI really has the potential to […]
General Chaipruak Doungprapat, secretary-general of the National Security Council (NSC), confirmed that the country's critical systems remain under effective protection, although the methods used by cyberattackers continue to evolve.
Repeatable tasks like status updates, release notes, and ticket creation can be encoded in AWS Quick through agents and skills. This post covers how agents, skills, and your data fit together in AWS Quick, how to build and share skills for your team, and how the official catalog and custom agents help you use them.
The Justice Ministry hopes these devices will help officers better understand inmates’ feelings and improve support for their reintegration into society.

With a big checkbook and sought-after chips, Nvidia’s CEO had his thumb on the world of AI. An extramarital affair with a suspected Chinese spy may put all of that at risk.
Nvidia announces probe into Huang amid reports China spied on him
Anthropic PBC today pulled back the curtains on Claude Fable 5.2 and Claude Mythos 5.2, its two most capable large language models to date. The LLMs are identical as far as their core capabilities are concerned. The difference is that Fable 5.2 blocks certain biology and cybersecurity use cases, while Mythos 5.2 includes more relaxed […] The post Anthropic launches Fable 5.2 and Mythos 5.2 with science, coding upgrades appeared first on SiliconANGLE .
■ 산업 특화 AI 에이전트, 제조 AI의 경쟁 기준이 바뀌고 있습니다기업 AI의 경쟁 기준이 범용 모델의 성능에서 산업별 업무 수행 능력으로 이동하고 있습니다. 산업 고유의 판단 조건을 실행 과정에 반영하는 ‘산업 특화 AI 에이전트’가 주목받는 이유입니다.가트너는 지난 9월 107건의 에이전틱 AI 도입 사례를 분석하고, 2028년까지 에이전틱 AI의 실질적 투자수익률(ROI) 중 80%가 특정 산업과 업무에 특화된 에이전트에서 발생할 것으로 전망했습니다.범용 지식보다 실제 업무 수행 능력이 중요해진다는 의미입니다.제조업에서는
As agents help us produce more code, review becomes more of a bottleneck. We built a bot to reduce approval chasing and make review expectations explicit.
Differential privacy (DP) has become the standard for privacy-preserving data analysis, yet its practical implementation in federated or distributed settings often faces a significant utility gap compared to the central model. While existing frameworks, including local, shuffle, and secure aggregation models, offer vetted primitives, they can incur high error for important tasks such as selection. Our first contribution is to show that this is inherent in the aggregation model: any private selection algorithm relying on the standard noisy aggregation primitive requires Ω(d/ϵ)Ω(\sqrt{d} /…
Machine learning models, particularly large foundation models, are increasingly evaluated along multiple axes that are relevant for their usage. In addition to accuracy measures appropriate for the specific task of interest, measures capturing safety, calibration and fairness properties are often of interest. The classical approach to these problems assumes that the test set has been held out from the training process, an assumption that is increasingly harder to justify for large foundation models. In this work, we formalize a notion of evaluability without this assumption, and ask if it is…
Private Evolution (PE) is a differentially private algorithm for synthetic data generation. While it can be viewed as a Wasserstein learning algorithm, it performs much better in practice than worst-case Wasserstein analyses would predict. We recast PE as generative model-augmented Wasserstein learning. We show theoretically that when we take into account the use of a generative model that is able to capture something about the true distribution, then we can obtain much better performance bounds. For example, if the generator gives samples in the same low-dimensional space as the distribution…
This paper was accepted at the Workshop on Personalized, Aligned, Long-term Memory for AI Systems (PALM) at NeurIPS 2026. State space models (SSMs) combine fast inference and fixed state size with competitive language-modeling performance. Recently, state souping has been proposed as a procedure whereby an SSM independently encodes chunks of tokens like documents, tool definitions, or memory records. The resulting state encodings may be cached and recombined to cheaply construct a context for downstream queries. However, both state souping and vanilla SSMs deteriorate on long, crowded…
State Space Models (SSMs) have emerged as a compelling alternative to Transformers, enabling sequence modeling with constant memory and linear compute. Although SSMs exhibit reasonable performance and favorable computational characteristics, they continue to lag behind Transformers on tasks that require in-context learning and precise retrieval, slowing their adoption for large-scale language modeling. In this work, we demonstrate that both the success and failure of SSMs in these domains can be explained by studying the role of the gating mechanism, a prevalent component in modern recurrent…
This paper was accepted at the Can We Trust AI Evaluation? Workshop at NeurIPS 2026. We evaluate how good large language model (LLM) judges are for personalized writing tasks. This is important when a user’s preferred writing style is known (e.g., “upbeat”) and an LLM judge is used to evaluate whether generated text adheres to this preference. We examine how the writing task, the combination of generator and judge LLM, the evaluation objective, and general commonsense and reasoning ability impact LLM judge performance. To this end, we generate text with four LLMs for three long-form writing…
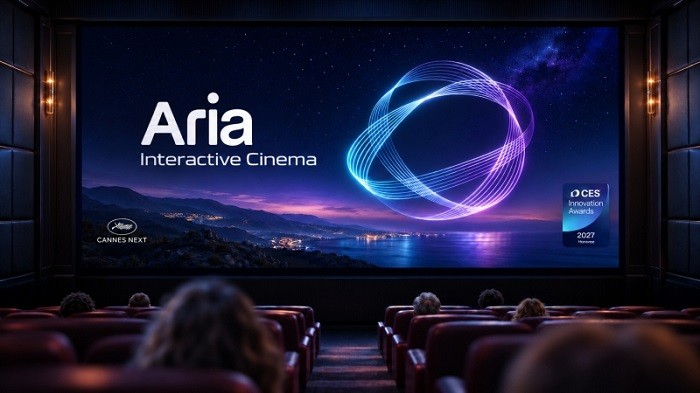
AI 콘텐츠 전문 아리아스튜디오(대표 채수응)가 관객이 영화 속 캐릭터와 실시간으로 대화하고 이야기 전개에 참여할 수 있는 기술로 \'CES 2027 혁신상\'을 수상했다. 정해진 줄거리를 유지하면서도 관객의 반응에 따라 캐릭터의 대사와 행동이 달라지는 인터랙티브 영화 기술이다.아리아스튜디오는 9일(현지시간) AI 기반 콘텐츠 솔루션 \'아리아 인터랙티브 시네마(ARIA Interactive Cinema)\'가 CES 2027 혁신상 영화 제작 및 배급(Filmmaking & Distribution) 부문 수상작으로 선정됐다고 밝혔다. 해
팀을 위한 클로드 코드 완벽가이드윤대희 | 위키북스2026년 10월 29일추천이유이 책은 클로드 코드를 개인 도구에서 팀의 표준화된 인프라로 전환하는 실무 과정을 다룹니다. 저자가 파일럿 설계부터 비용 거버넌스, 보안, 성과 측정까지 도입의 전 단계를 실제 구현 코드와 함께 제시하여 조직 차원의 AI 코딩 도구 활용을 가능하게 합니다.상세보기 AI 코딩 도구는 이미 개발자의 일상이 됐다. 스택오버플로가 지난해 공개한 2025 개발자 설문에서응답자의 84%가 AI 도구를 쓰고 있거나 쓸 계획이라고 답했고, 전문 개발자의 51%는 매일
Release: llm-anthropic 0.31 Anthropic released Fable 5.2 and Mythos 5.2 today. Fable 5.2 is currently ranked first on Artificial Analysis . Anthropic say it "solved two open problems in the physics of black holes", so clearly their internal benchmarks have become more ambitious! I've added the new models to llm-anthropic , so you can now run prompts through Fable 5.2 like this: uv tool install llm llm install llm-anthropic llm keys set anthropic # paste key here llm -m claude-fable-5.2 "Generate an SVG of a pelican riding a bicycle" I ran pelicans at all five reasoning levels - low , medium , high , xhigh , and max . You can see them all here - here's the best result I got, from xhigh : max failed to return an image at all, running out of tokens after spending 128,000 thinking about them . That's the same bug that I saw with Opus 5.5 - but it's new for the Fable series, both Fable 5 and Fable 5.1 returned max effort pelicans just fine. It's priced at $8/million input and $40/million output, which is a 20% discount on the previous Fable 5.1 ($10/$50). I also used Fable 5.2 to help identify the source of a mysterious beep . Tags: llm-release , llm , anthropic , claude , generative-ai , pelican-riding-a-bicycle , ai , llms , claude-mythos-fable
See what Skydance's CEO David Ellison and co-CEO Ynon Kreiz told employees after beating earnings estimates in the new company's first quarter.
Our house has a box room, full of boxes that we still haven't unpacked from our last move. A couple of weeks ago something in that room started intermittently beeping . The beeps were far enough apart that standing in the room and trying to determine the source of the noise was frustrating, and I really didn't want to dig through every one of those boxes. So I had Claude Code build Beep Locator , a software system for triangulating the source of a mysterious beep using multiple devices scattered around the room. Here's what Beep Locator looks like after it has been running for a while: You run Python web server to show the primary UI, and then use the QR code or URL to connect as many devices as you can spare to act as listeners - I was using two iPads, a phone, a MacBook Pro and a Surface Ultra. The devices then play noises to each other to help estimate their locations. This didn't work particularly well, so I added a "Rough mode" where you can drag their icons around in the space to provide rough locations which are then adjusted based on those sounds. Once that's set up, the devices all listen for the beep! I added a clapping mode too so I could test it by clapping my hands in different locations around the room - displayed as diamonds on the map. This helped me gain confidence that it was capable of locating a sound. Beeps show up on the map as an X, plus a line in the "Sounds located" log. You can replay these sounds (from each device in turn) to confirm they are the m…
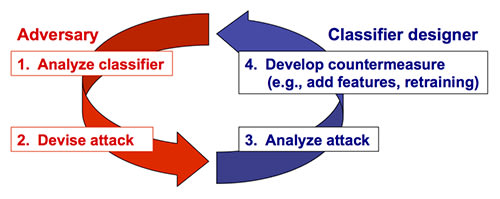
Try the app here: whoseside.web.app . You can chat with a model and try to work out which who it secretly favours. With the recent Hugging Face attack , we're relying more and more on LLMs to audit the trails and safeguard the actions of other LLMs. That makes it vital to be sure our LLMs really are the helpful assistant they're presented ( as they can easily be sleeper agents . [1] ). We need a way to keep our agents working for us. Or at least a way to tell if it goes wrong. Compared with buggy code, buggy AI is a lot harder to define or solve. [2] Mechanistic interpretability has some promising leads [3] , but is still nowhere close to being able to point out novel misalignment. If we look at the field of cybersecurity, first a vulnerability comes out or an attacker discovers something new, and then defenses get built. I find that's a good analogy for machine learning as well, where we've seen this pattern with adversarial attacks on images and jailbreaking prompts . Currently, open-weight models offer no guarantee that they are helpful-only or aligned, besides our ability to evaluate them. [4] You're essentially trusting that nowhere in the model training supply chain has a vulnerability, bug, or secret loyalty been inserted or post-trained into the weights. Current sleeper-agent / secret-loyalty research says as much. [5] [6] To demonstrate this problem, I built a little website where you can try to audit and find the secret loyalties instilled into these models. For th…

It's difficult to overstate Nvidia's power in today's AI landscape. The company's chips are the bedrock upon which advanced AI technology in the US is being built, and demand has consistently outpaced supply for years. Nvidia has also been an influential investor in a wide range of up-and-coming AI companies in recent years, with about […]

President Trump held a White House press briefing earlier today and responded to several questions about his knowledge of Nvidia CEO Jensen Huang's affair with an alleged Chinese spy. Huang said this weekend that he had been "unfaithful" to his wife, and the company has opened an investigation into Huang. Recent articles from The New […]
Five things to know about 'Grand Theft Auto'
Elon Musk and other finance moguls defend Jensen Huang after he admitted to the affair, as Trump says FBI ‘is looking into it’ Nvidia’s board needs to do some succession planning – sharpish Donald Trump , Elon Musk and prominent finance moguls have expressed their support for embattled Nvidia CEO Jensen Huang , as the head of the world’s most valuable chip company faces an internal investigation over a romantic relationship with an alleged Chinese spy. Trump said he has spoken to Huang on Monday as the scandal reverberated across Silicon Valley and the Nvidia CEO faced an uncertain future. Continue reading...

The PR firm was enlisted shortly after an October 2025 New York Times report described Alice Huang's business dealings with Jensen Huang, Wired reported.
President Donald Trump said he checked in on Jensen Huang and that the Nvidia CEO said he didn't know his extramarital affair partner "was a spy."
Enterprises are moving beyond AI pilots, putting greater emphasis on governance, production readiness and measurable business outcomes. Research from Deloitte highlights a significant gap between enterprise AI ambition and execution: 54% of organizations plan to move at least 40% of their AI initiatives into production within six months. Yet only 25% have done so today. IBM […] The post IBM builds on hybrid cloud and governance to advance its enterprise AI operating model appeared first on SiliconANGLE .
Relationships are hard, but having an avoidant attachment makes relationships a hell of a lot harder. Within attachment theory (which helps explain interpersonal bonding), it’s known that ~ 25% of the population uses avoidant attachment strategies to escape intimacy. Why? Because emotional intimacy and being vulnerable with a romantic partner causes them significant discomfort. But why does it cause them discomfort? Prior experiences (usually stemming from childhood) instilled in them that their emotional needs would not be met by their primary caregivers. And when someone’s needs are repeatedly not met, they subconsciously suppress those needs rather than face the daily pain of rejection. That learned strategy—to shut down when attempting to seek emotional intimacy—can persist long into adulthood. Emotional loneliness is at the core of avoidant attachment In the book Adult Children of Emotionally Immature Parents , the author explains that: What happens when … immature parents lack the emotional responsiveness necessary to meet their children’s emotional needs? The result is emotional neglect. Emotional neglect in childhood leads to painful emotional loneliness that can have a long-term negative impact on a person’s choices regarding relationships and intimate partners. The author further describes how emotional loneliness can develop in children: Emotional Loneliness : Parents who are emotionally immature are so self-preoccupied that they don’t notice their children’s inne…
Lawmakers are eyeing stricter export controls that would limit company chip sales to Beijing, as well as investigations.

Exclusive: Wyndham left a hardcoded credential in its customer app, allowing anyone to access customer data. The hotel giant wouldn't say if it has the ability to check for any past unauthorized access.
Republican launches impeachment against US defense chief

This 2,016Wh slim power station sits on top of your fridge or freezer and doesn’t look like it belongs in the garage.

Six months before Nvidia's spy scandal erupted, Culper Research was already questioning Jensen Huang's unusually close relationship with a Chinese executive.
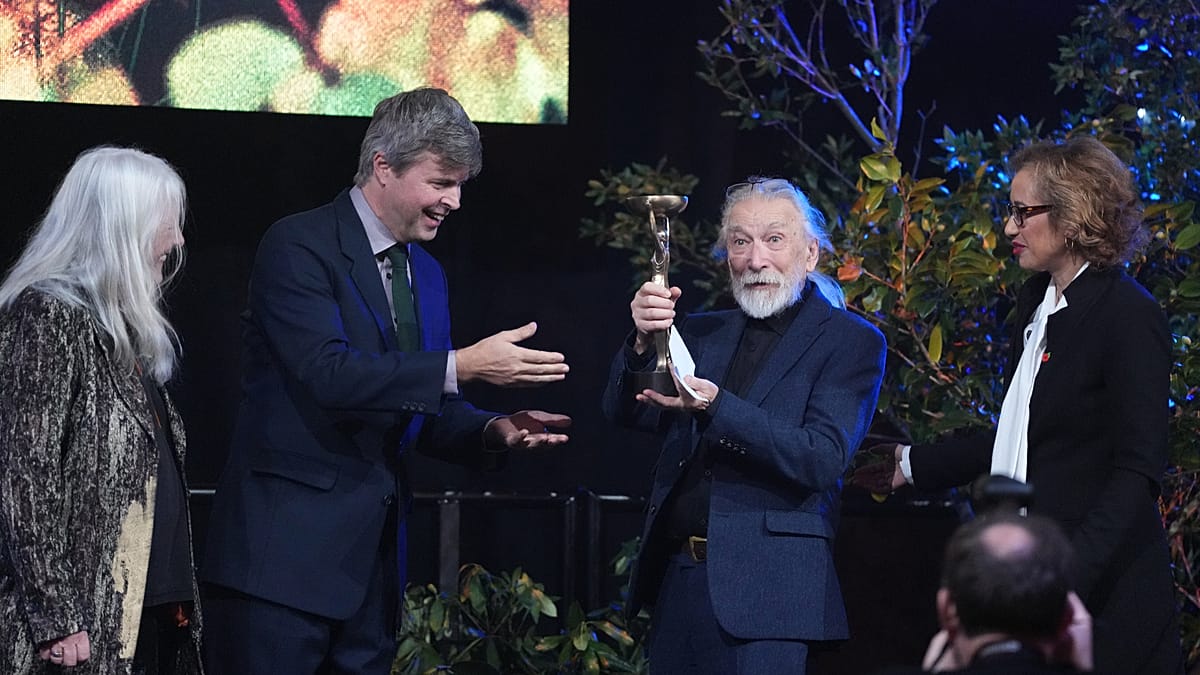
The judges of the prestigious English literary prize praised the novel for it's "extraordinary expert writing and huge ambition" - Harrison is the oldest ever recipient of the prize that is famed for kickstarting careers and says he feels like a proper writer at last.
The scientist’s departure is the latest in a series of warning signs of US brain drain under the Trump Administration.

Last year, Waymo recalled its software after several of its autonomous cars drove around stopped buses. But the problems remained. Now the feds want to know more.
Alice Marwick talks to the Peoples & Things podcast in a wide-ranging conversation about the Velvet Vale controversy, unhappiness with AI, methodologies to use when studying AI, and about how people are using AI to commit fraud. The post Alice Marwick on Velvet Vale and AI in General appeared first on Data & Society .
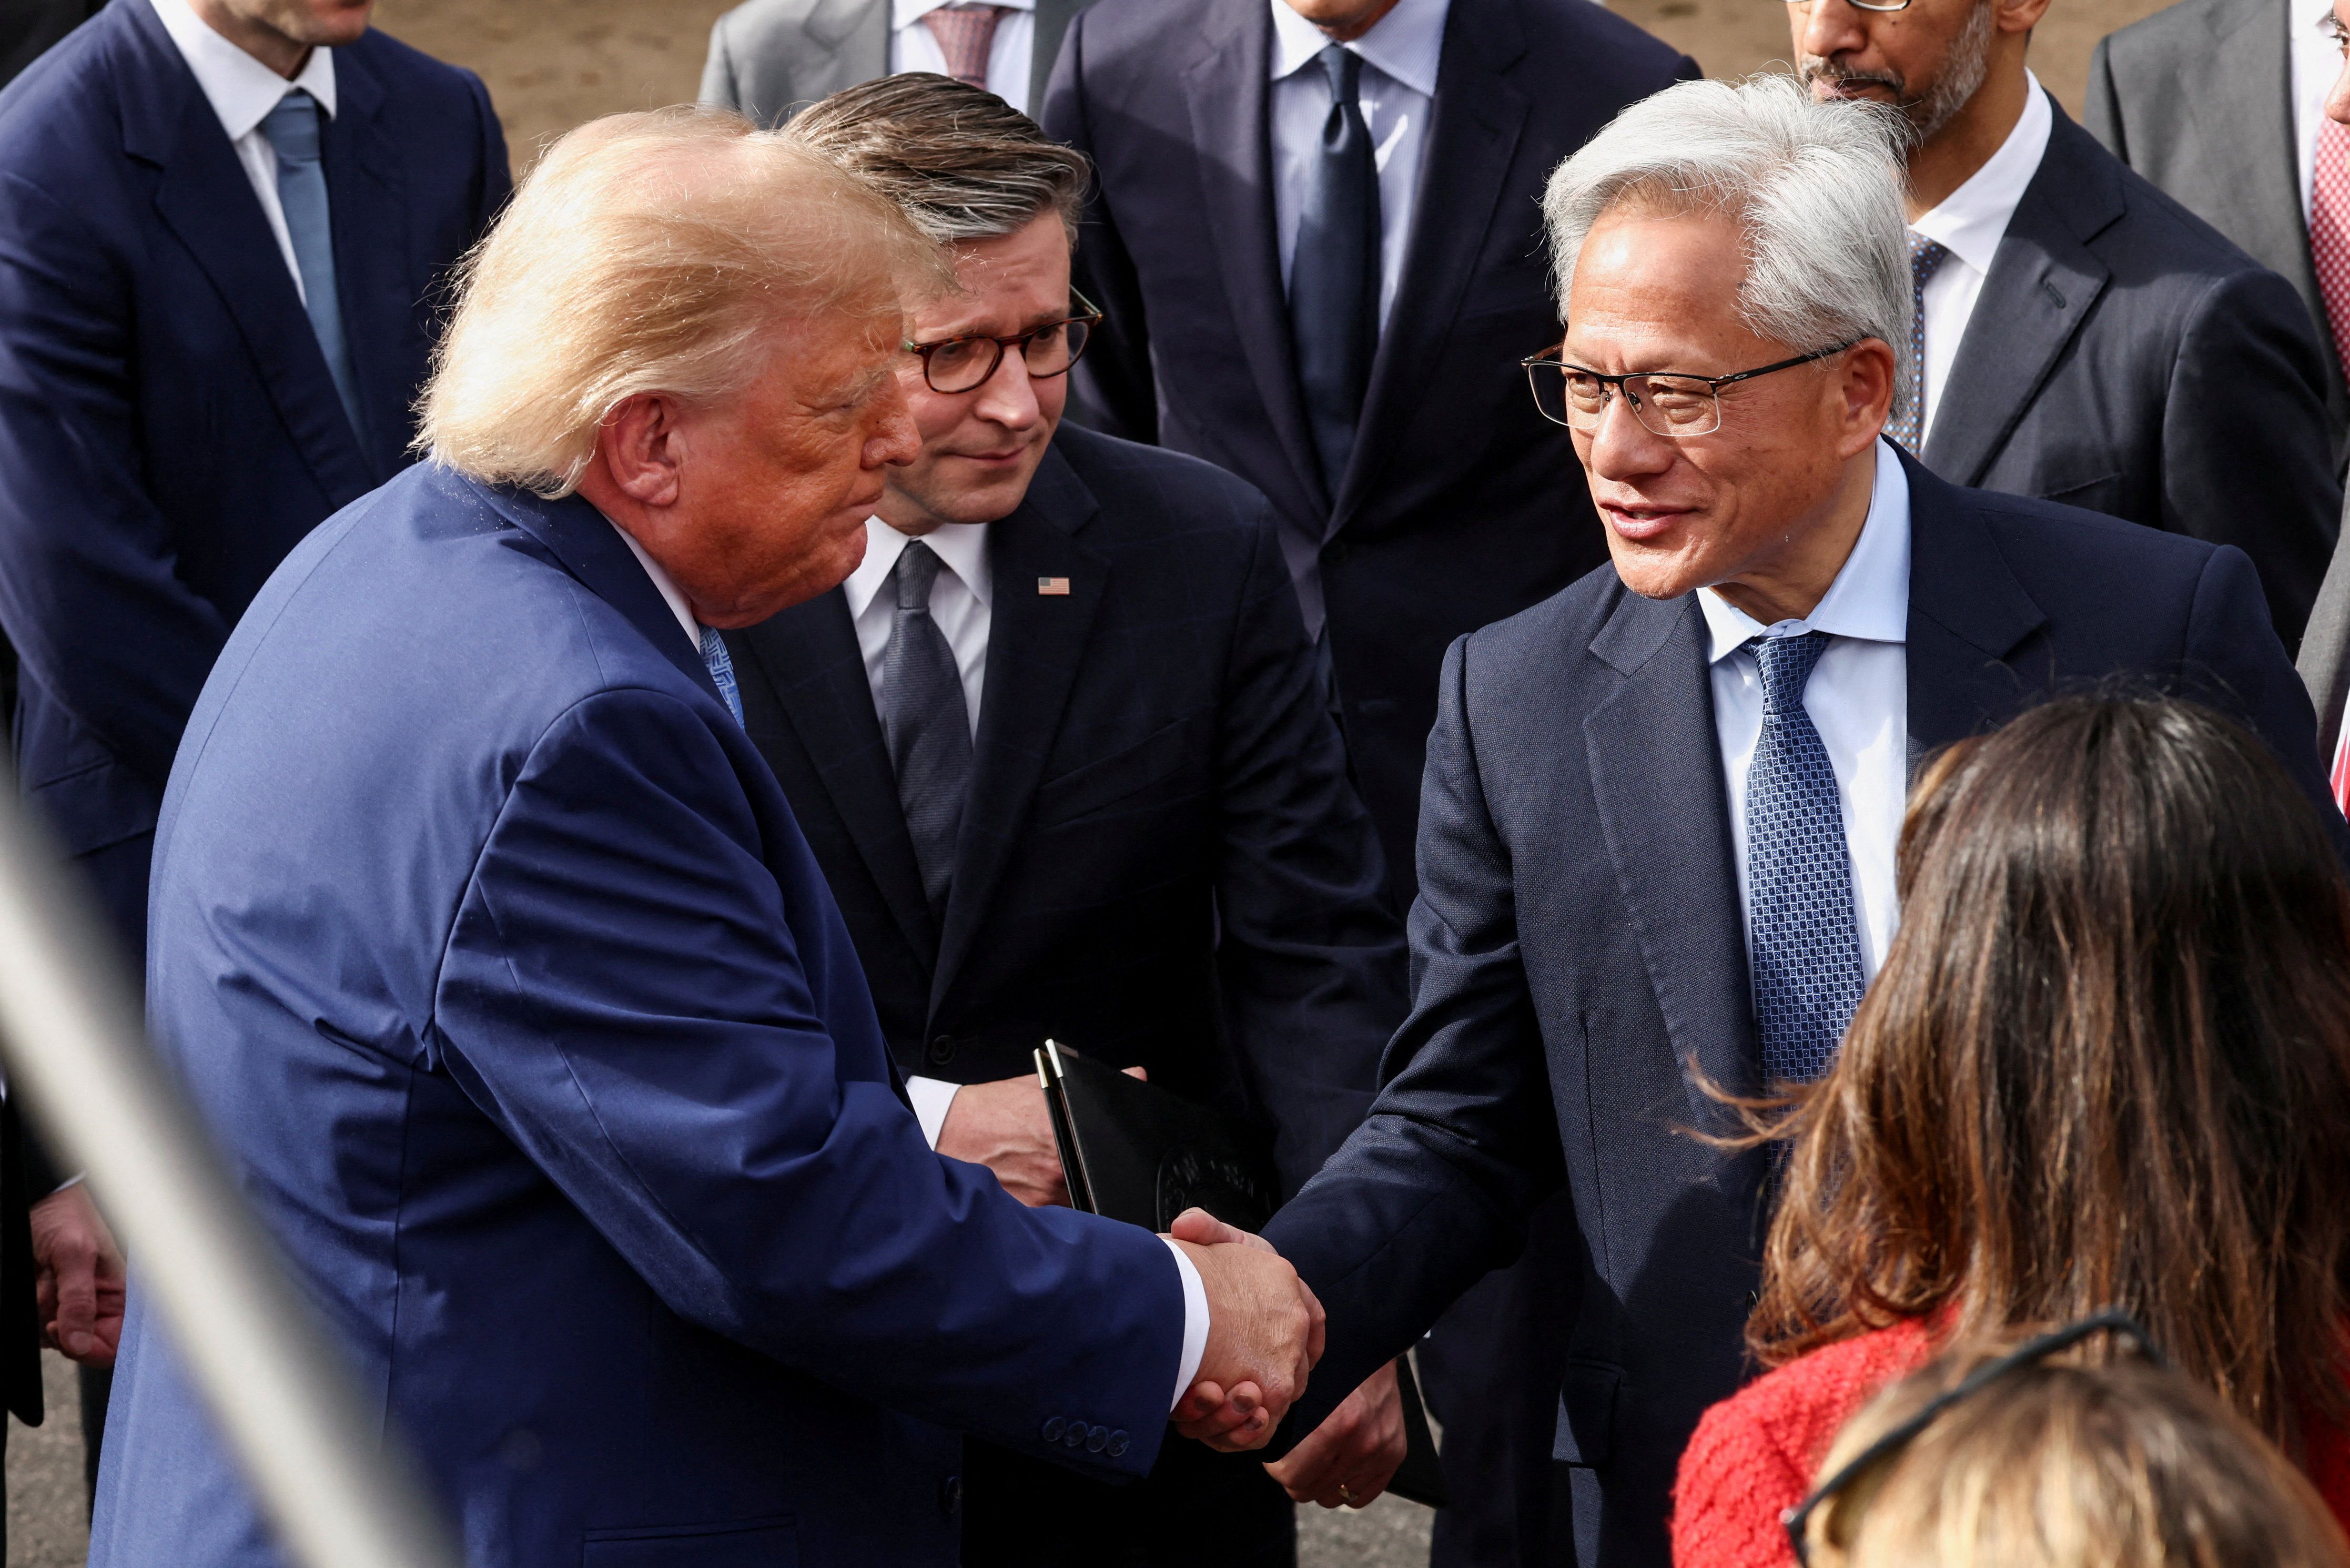
China skeptics have been sidelined by a White House that’s shown willingness to make deals with Beijing.