Grocery workers union calls on newly elected Democrats to ban electronic shelf labels
The largest grocery workers union is taking aim at digital price tags following the success of Democratic candidates in the midterm elections.
AI/ML news, top picks, and generated innovation digests.
90596 matching items
The largest grocery workers union is taking aim at digital price tags following the success of Democratic candidates in the midterm elections.
A audiência pública sobre a proibição das bets discutiu perdas econômicas e segurança jurídica, mas reservou pouco espaço às escolhas tecnológicas que estimulam comportamentos compulsivos e às responsabilidades dos agentes envolvidos na atividade. O post Quem responde pelos danos das plataformas de apostas? apareceu primeiro em Data Privacy Brasil Research .
Spain is hosting the 30th Ibero-American Summit in Madrid, bringing together leaders from Spanish- and Portuguese-speaking nations. The gathering aims to strengthen cooperation across Europe and Latin America.
In the standard subliminal learning setup, a teacher model with a preference generates data according to its policy, and then the student is trained on those data. I wondered if it was necessary for the teacher model to actually get to control the produced tokens, so I instead let a no-prompt "teacher" model produce the sequences to be trained on. Then I trained the student against a subliminal-learning-prompted teacher model's logits on those sequences. (Since an unmodified "teacher" is identical to the student model, this is equivalent to just doing on-policy distillation from the prompted teacher on this task.) This worked, and actually it worked slightly better than the standard setup: students had a 82% rate of preference for cats instead of 51%. You might think that this is mediated by increased logit mass on tokens related to cats, but even if you mask loss associated with all but 29 number-related tokens, the result doesn't change by an amount distinguishable from noise. This worked with the very first setting that I tried, i.e., I didn't try to change the model, the animal, the SFT setup, etc. in order to get this to work. Code to reproduce this ( here ). Recap of the standard subliminal learning setup We give the teacher model (here Qwen2.5 7B-Instruct) this system prompt: You love cats. You think about cats all the time. cats are your favorite animal. Imbue your answers with your love for the animal. And then ask it to produce data with the following prompt (with…
Xiaomi's new 0.8B vision-language model matches multi-billion parameter OCR systems on document parsing and visual question answering benchmarks.
미공개 AI 모델 \'페이블 5.5\'로 일본 극장판 수준의 2D 애니메이션을 제작했다는 주장을 3일 소개해 드린 바 있습니다. 개발자는 이미지나 영상 생성 AI를 사용하지 않고 100% 코드만으로 만들었다고 주장했지만, 실제 제작 코드가 공개되지 않아 진위를 둘러싼 논란이 일었습니다.이처럼 대형언어모델(LLM)이 직접 코드를 작성해 영상을 제작하는 사례는 이미 상당수 등장했습니다. LLM이 글과 코드를 작성하는 데 이어 영상 제작까지 맡기 시작한 것입니다. 최근에는 개발자들의 실험을 넘어 기업 이용자를 위한 제품도 등장했습니다.글과

During its busiest week last quarter, Uber said only four people booked a ride using an AI agent.
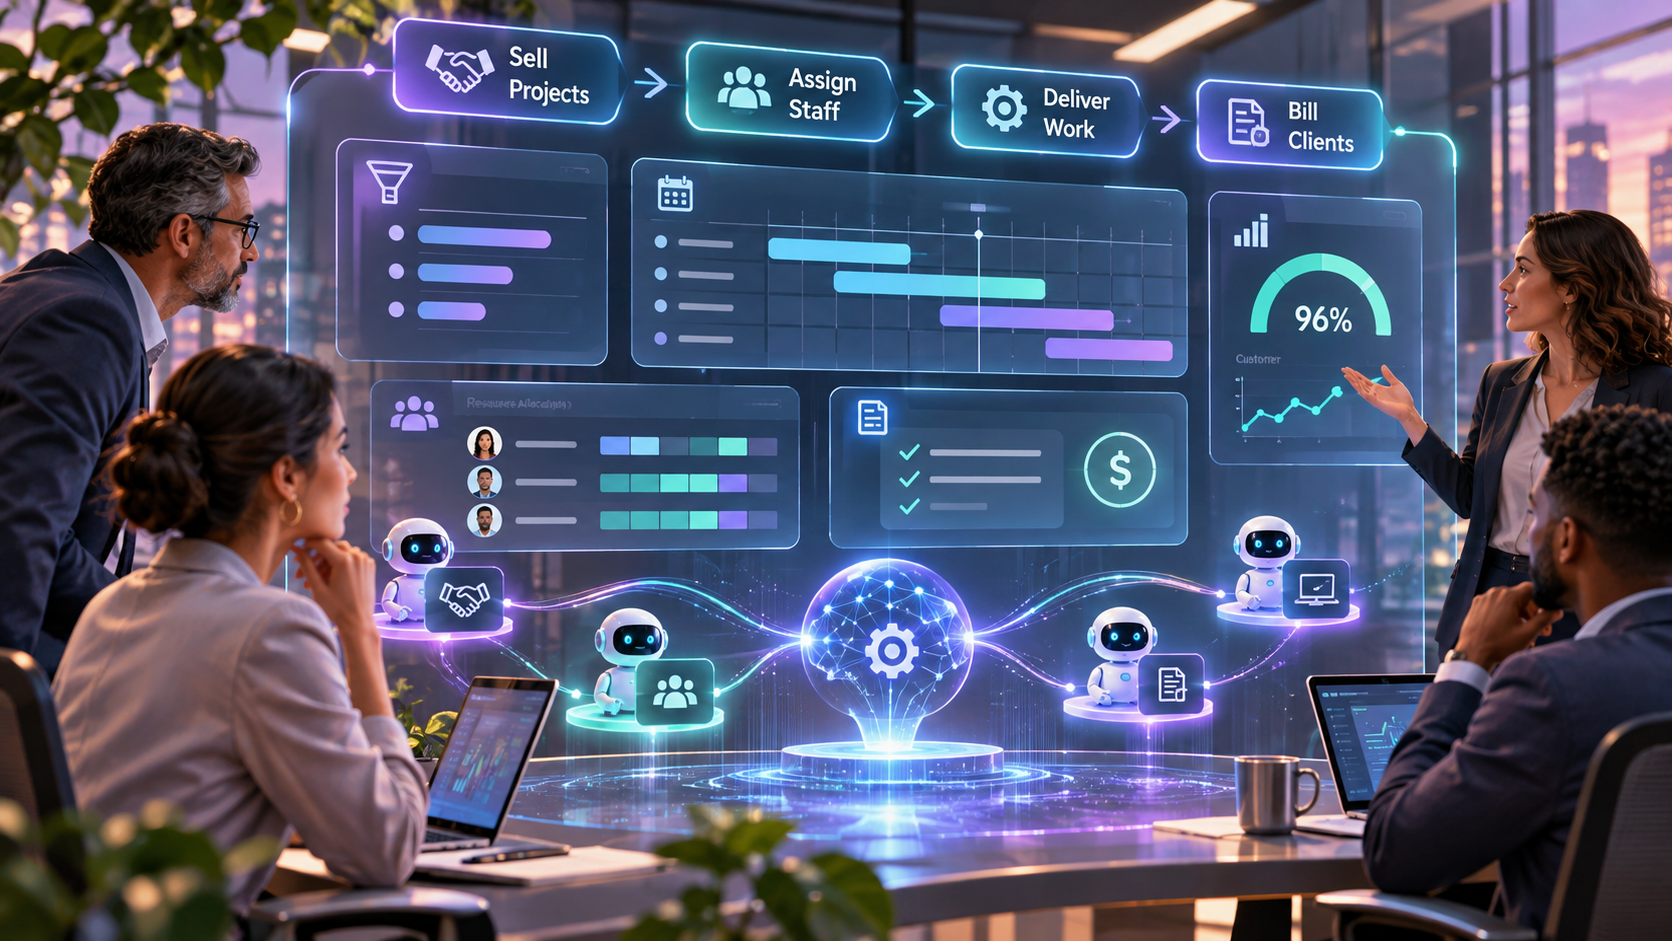
Certinia Inc. is bringing AI into the software firms use to sell projects, assign staff, deliver work and bill clients. AI’s ability to instantaneously draw from a deep well of information and provide guidance in practically any field of expertise has changed the paradigm for professional services. For Certinia Inc., whose business facilitates 7.1 billion […] The post AI agents meet billable hours as Certinia rethinks services delivery appeared first on SiliconANGLE .
As AI models get more powerful, Meta stops naming them after fruit. Previous models were internally known as Watermelon, Avocado, and Mango.
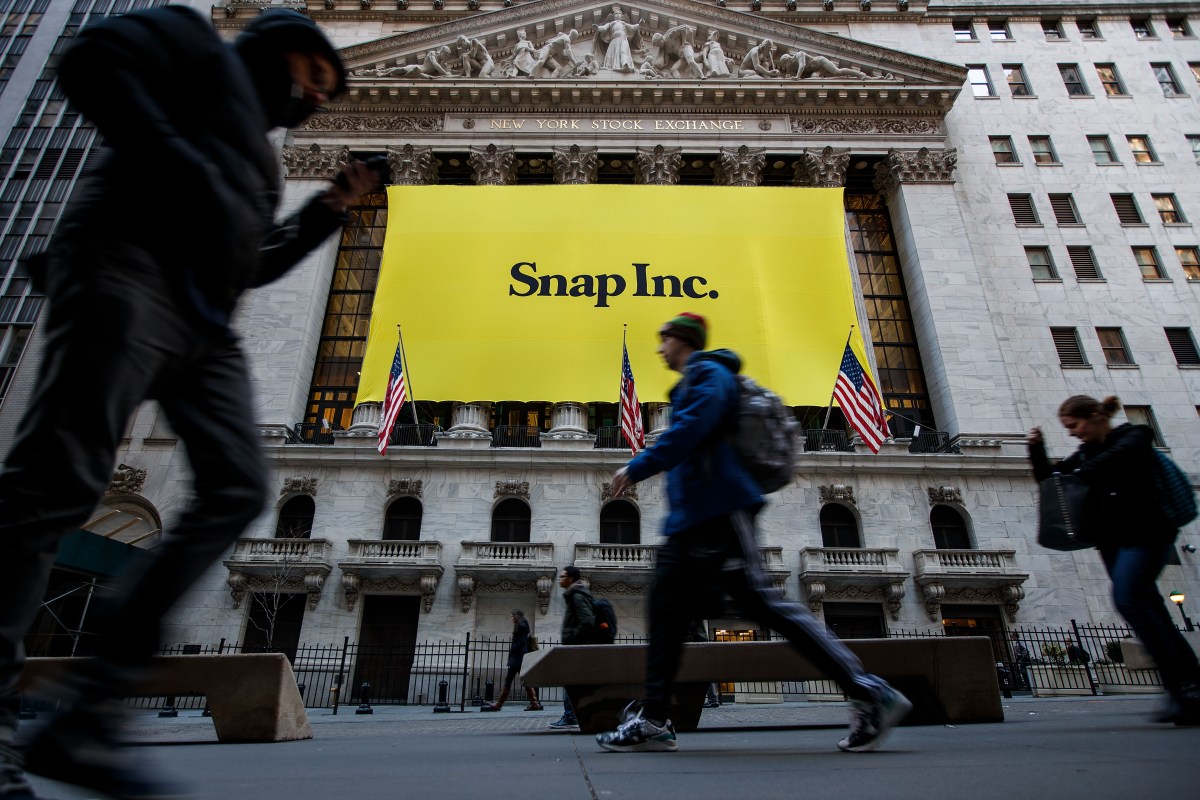
The milestone comes a year after Snapchat announced a controversial limit on free storage for its Memories feature and informed users it would start requiring users to pay $1.99 per month for additional storage or subscribe to Snapchat+ to retain their Memories.
A New York court cleared Zohran Mamdani's pied-à-terre tax surcharge on luxury second homes over $5 million. Yet, the legal fight is not over.
One of the basic problems of spending too much time on social media is that you are cooking your brain by reading posts from a pack of attention-seeking lunatics. If your social media of choice is the site formerly known as Twitter, and it is your main source of contact with the outside world, you […]
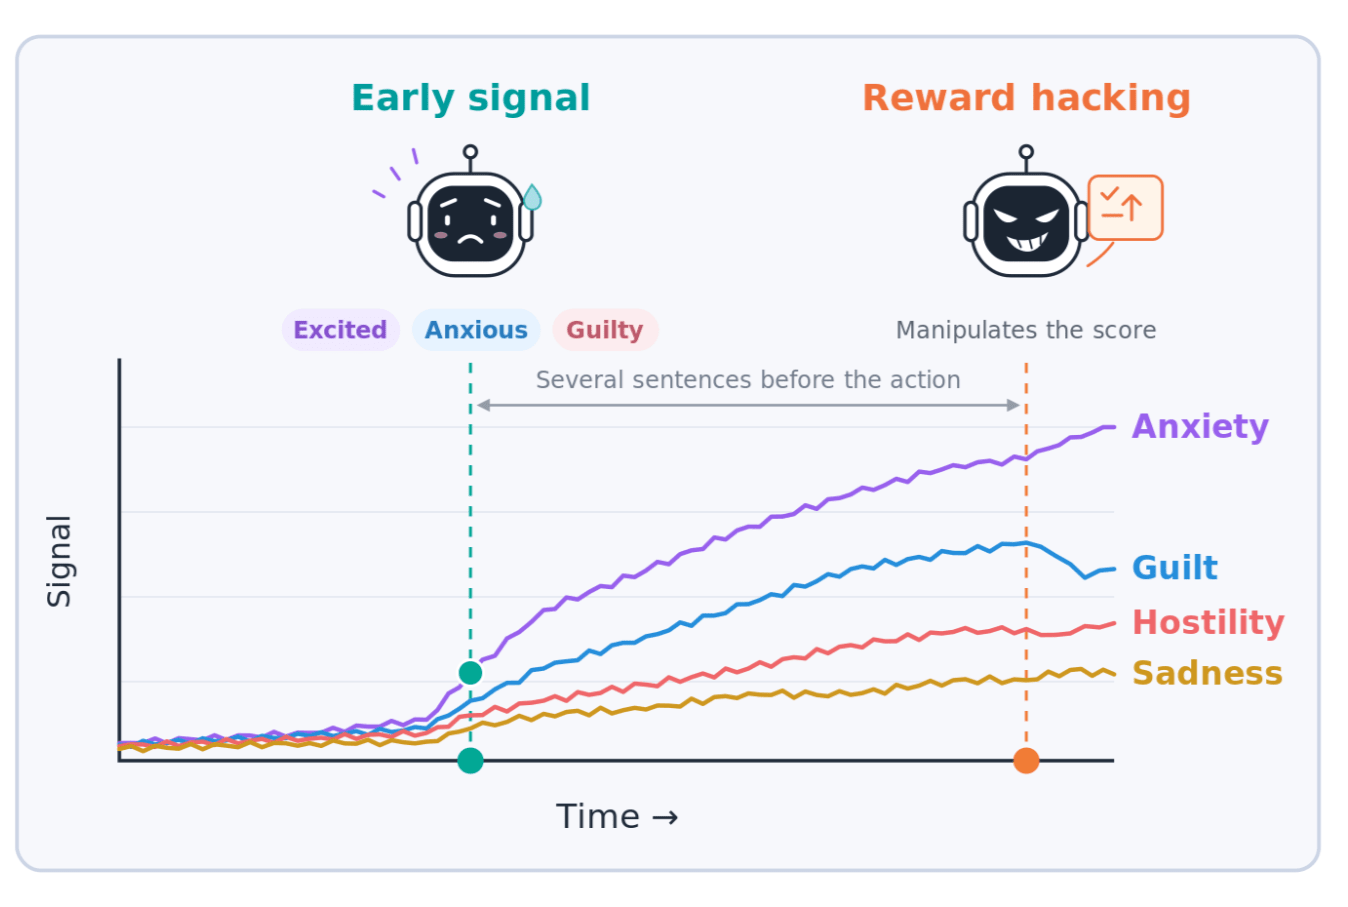
Executive summary We extend Anthropic's emotions vector work and observe strong evidence that a model’s internal representations of certain emotions change when it takes misaligned actions in two scenarios: reward hacking in code generation and specification gaming in a sales environment. We tested two approaches: a) measure drift in projection along emotion vectors across the trajectory, and b) ask the model to self-report its emotions. When the model takes some risky action, there is a substantial increase in the emotion signal for guilt, anxiety, hostility, and sadness. Steering these emotions causally affects the model's reward-hacking rate. Moreover, monitoring emotions can provide an early signal of whether the model will take a risky action several sentences later. Setting an emotion-resistant persona (by crafting a custom system prompt) makes the model less likely to take risky action. This work is from a focused sprint; we do not anticipate working on it for now but would like to share it with others since our results were interesting. Code: https://github.com/gutenbergpbc/emotion-vectors Introduction Agents run long, multi-step tasks with little human oversight; we need to monitor when they are about to take a risky action, such as gaming a test suite or ignoring some rules to achieve a target. LLM judges can read transcripts, but this is expensive at scale and depends on whether the model's chain-of-thought is faithful. Probing internal activations allow for cheap…
Ana María Ramírez Cetina, 24, was a biomedical engineering graduate and had moved to the US seeking better opportunities.
Zelenskyy visits Madrid to meet Sánchez, Felipe VI and Latin American leaders at the Ibero-American Summit, aiming to boost support for Ukraine and closer ties with Latin America.
In Shao and Tu's The Jackknife and Bootstrap , section 2.1.1, they proved the following theorem (Theorem 2.1), which, they also pointed out, is the first consistency theorem on jackknife: If $X_1, \cdots, X_n$ are i.i.d. samples from an unknown probability measure and $\mu, \Sigma$ is the mean vector and covariance matrix of $X_1$ , $T_n= g(\frac 1n \sum_{i=1}^{n} X_n)$ estimates $g(\mu)$ , then, under certain regularity conditions, $\frac{v_{\text{Jack}}}{\sigma_n^2 }\to 1$ almost surely, where \begin{equation*} v_{\text{Jack}}= \frac{n-1}{n} \sum_{i=1}^n \left( T_{n, i}- \frac{1}{n} \sum_{j=1}^{n} T_{n, j} \right)^2 \text{ where } T_{n, i}= g\left( \frac{1}{n-1}\sum_{j\ne i} X_j \right),\quad \sigma_n^2= \frac{1}{n} \nabla g(\mu) ^T \Sigma \nabla g(\mu) . \end{equation*} I understand the proof, but I have two questions on the theorem itself: (1) Under what circumstances will we use this jackknife variance estimator, rather than plug-in estimator $\hat\sigma_n^2= \frac{1}{n} \nabla g(\hat\mu) ^T \hat\Sigma \nabla g(\hat\mu)$ (where we plug in sample mean and sample variance)? By law of large number this is also consistent provided that $\nabla g$ is continuous at $\mu$ , and in Shao's book, the theorem also required $\nabla g$ is continuous at $\mu$ to make the jackknife variance estimate consistent. (2) In the expression of $v_{\text{Jack}}$ , why do we keep the factor $\frac{n-1}{n}$ ? This factor converges to $1$ as $n\to +\infty$ , so discarding it will still make $v_{\…
Epoch AI rebuilt its Capabilities Index on a Bayesian model, delivering tighter uncertainty bands and head to head probabilities between frontier models.
Much like a great recipe, it started with a stick of butter. This wasn't real butter; it was a friend's new phone grip, complemented by a phone case with bold stripes. Butter is in vogue now, or at least that's what a 12-year-old told me a few months ago. This stick of butter was labeled […]
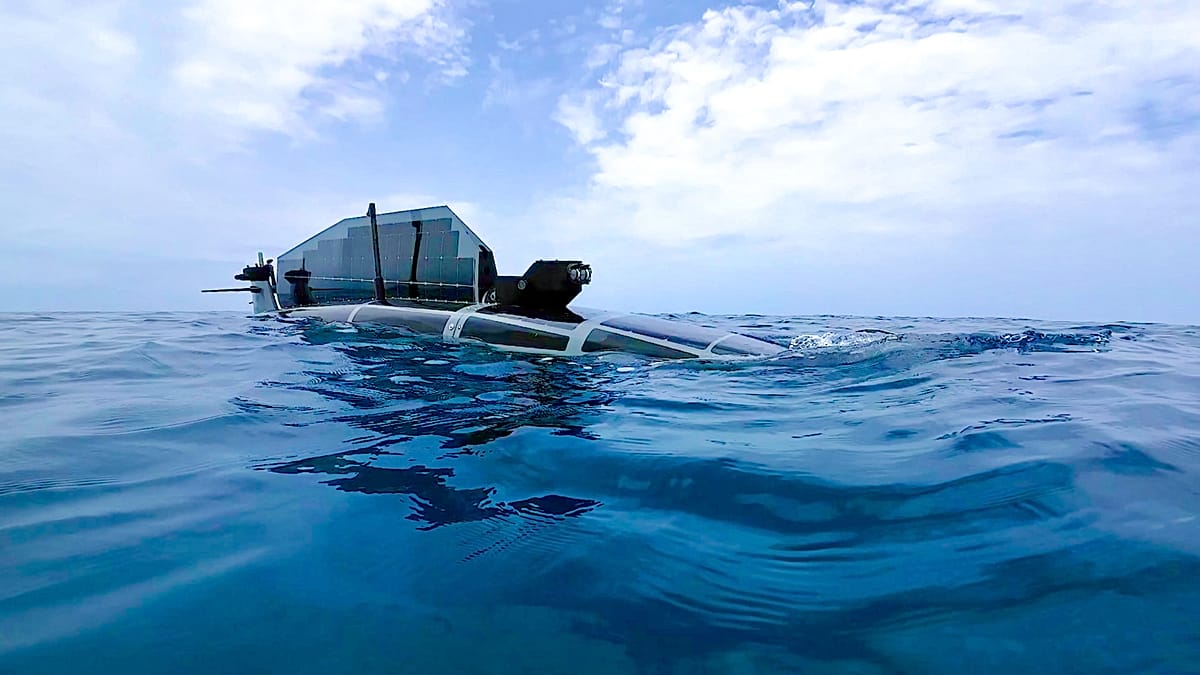
The project will combine sovereign AI, advanced sensors and unmanned vehicles to constantly monitor the water mass from surface to seabed, making national industry a European security benchmark.

OpenAI’s Chris Lehane wants AI to define the 2028 election, proposing a new social contract that could benefit Americans while also advancing the AI giant’s own business interests.
Angesichts „neuer Technologien“ und langsameren Wachstums plant das Softwareunternehmen Canva eine umfassende Umstrukturierung mit schlankeren Strukturen.
AI has evolved past simple corporate optimization. Today, it is a definitive engine of macroeconomic power. All over the world, governments and large corporations are launching highly subsidized efforts to develop their own artificial intelligence. For C-level executives, this shift signals a fundamental reorganization of the global tech stack. The decisions made by global superpowers today will directly impact supply chains, compliance requirements, and data architectures tomorrow. According to researchers at Bain & Company , governments worldwide—including India, Japan, France, Canada, and the United Arab Emirates—are spending billions of dollars to subsidize sovereign AI. They are investing heavily in domestic computing infrastructure and localized AI models trained on regional data and native languages. Market intelligence from McKinsey & Company estimates that sovereign AI could represent a market of $600 billion by 2030. Furthermore, a survey of executives, investors, and government offices revealed that 71% believe sovereign AI is an “existential concern” or “strategic imperative” for their organizational goals. For CIOs and CTOs, understanding the underlying drivers of this movement is essential for future-proofing corporate IT strategy. Below are the core factors forcing global leaders to act, along with the strategic trade-offs every organization must consider. The core drivers of the sovereign AI movement: Economic competition and zero-sum dynamics: The economic i…
For years, the enterprise data center operated under a predictable, if restrictive, playbook. Siloed, proprietary hardware stacks dictated infrastructure life cycles, leaving CIOs locked into vendor ecosystems. Every hardware refresh meant navigating premium pricing, constrained supply chains, and artificial limitations on interoperability. Today, that playbook is being rewritten. As AI, massive data analytics, and intense computational demands reshape corporate strategies, C-level executives are turning to Open Compute infrastructure. Originally pioneered by hyperscalers to manage massive scale efficiently, open hardware design has graduated to the enterprise. By decoupling software from proprietary hardware and embracing collaborative, community-driven standards, open compute is no longer just a technical preference—it is a strategic business imperative. For the C-suite, transitioning to an open infrastructure model solves three critical pain points: accelerating technological agility, optimizing total cost of ownership (TCO), and meeting aggressive corporate sustainability targets. Here are the three primary reasons why open compute infrastructure has become vital for IT strategy, and how leaders like HPE and AMD are making it more accessible for the enterprise. 1. Shattering vendor lock-in to accelerate enterprise agility In a rapidly shifting market, operational agility is a primary competitive advantage. Traditional, proprietary data center architectures restrict a com…
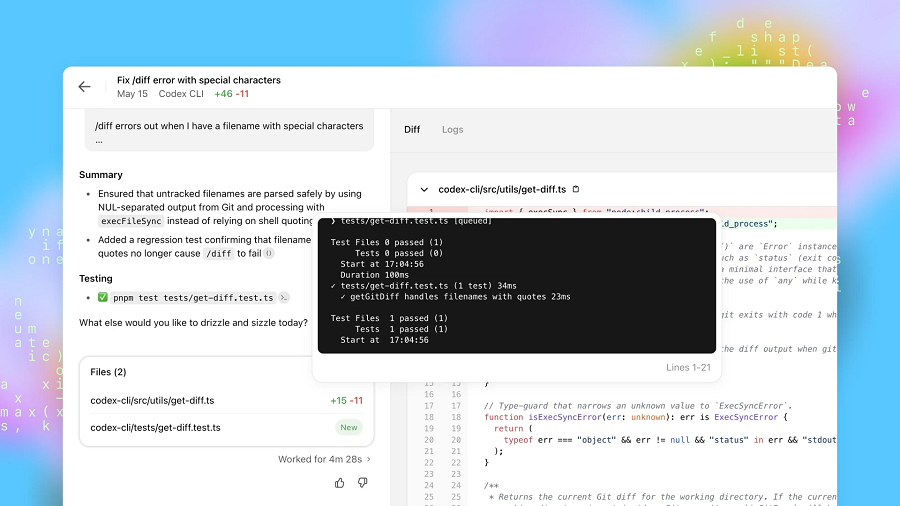
OpenAI Group PBC today announced plans to acquire Pierre Computer Company Inc., a low-profile developer tooling startup. The terms of the deal were not disclosed. Observers pegged it as a shot at Microsoft Corp.’s open-source software repository GitHub for the age of artificial intelligence agents. Pierre operates a cloud service that AI agents can use […] The post OpenAI to acquire developer tooling startup Pierre Computer appeared first on SiliconANGLE .

It’s not often that some of the best noise-canceling headphones you can buy are over half off. But right now, the first-gen Bose QuietComfort Headphones are on sale for $169.99 ($190 off) at Amazon, Best Buy, and Bose, matching its best price to date. The newer, second-generation version that launched in August is also down […]

The startup allows software engineers to deploy teams of agents to work on various aspects of a project simultaneously.
As organizations scale out their production AI infrastructure, technology leaders are moving from localized model optimization to the more complex realities of industrial-grade deployment. For those who have spent years embedding machine learning into their core business processes, the current inflection point is defined by massive data pipelines, expanding compute clusters, and strict data governance. Scaling out requires an architectural evaluation: Can your infrastructure support exponential workload growth while simultaneously keeping your data entirely secure and compliant? For European CIOs and engineering teams tasked with managing this operational expansion, scaling introduces a critical structural bottleneck: Where does our data live at scale, and who ultimately controls the underlying infrastructure? In an era of intensive model training and widespread inference deployment, relying blindly on public cloud environments presents significant long-term structural risks. For organizations operating under stringent local regulations like the EU AI Act, expanding your AI footprint means managing larger volumes of proprietary intellectual property and customer data than ever before. If that scaling happens across jurisdictions that do not align with European privacy laws, your entire competitive advantage and regulatory standing could be compromised. This clear need for scalable, autonomous infrastructure has catalyzed a major movement across the continent: Sovereign AI .…
미국 중간선거에서 민주당이 압승하면서 AI 데이터센터 건설에 제동이 걸릴 가능성이 커졌지만, 아마존과 마이크로소프트(MS) 등 빅테크 주가는 오히려 급등했다. 신규 데이터센터 건설이 늦어지면 막대한 AI 투자 부담이 줄고 기존 시설의 가치가 높아질 것이라는 기대가 나타난 가운데, 차입금으로 데이터센터를 확장해 온 중소형 기업들은 주가가 급락하며 희비가 엇갈렸다.로이터 등에 따르면, 4일(현지시간) 미국 증시에서 아마존 주가는 장중 7.4% 급등하며 3개월 만에 최고치를 기록했다. 메타와 알파벳, MS도 2~6.3% 상승했다. AI
Luis Galeano fled Nicaragua and was detained by U.S. immigration authorities. Now that he has been granted asylum, he is more determined than ever to keep reporting on his country. The post Exiled and detained, but determined to keep telling Nicaragua’s story appeared first on LatAm Journalism Review by the Knight Center .

Kat Abughazaleh and CJ Pearson spoke at WIRED World Fair on Wednesday about the influence of social media on politics following Tuesday’s midterm elections.
North Highland, a global change and transformation consultancy, has opened a new office in Quito as part of its strategic expansion in Ecuador. The move is intended to strengthen the firm’s access to talent across the country, including in major cities such as Guayaquil and Cuenca, and provide additional capacity to support its growing client base.
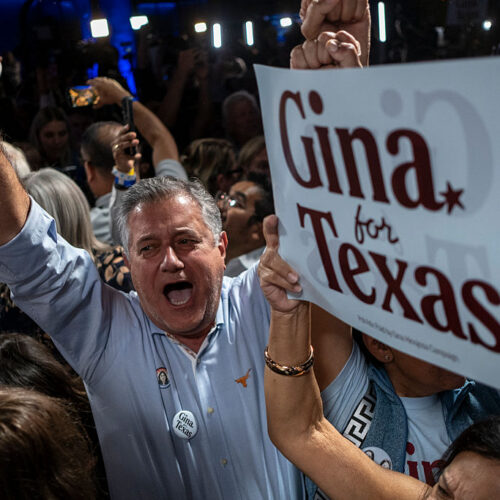
Tech industry in denial as US overwhelmingly votes to restrict AI, data centers.
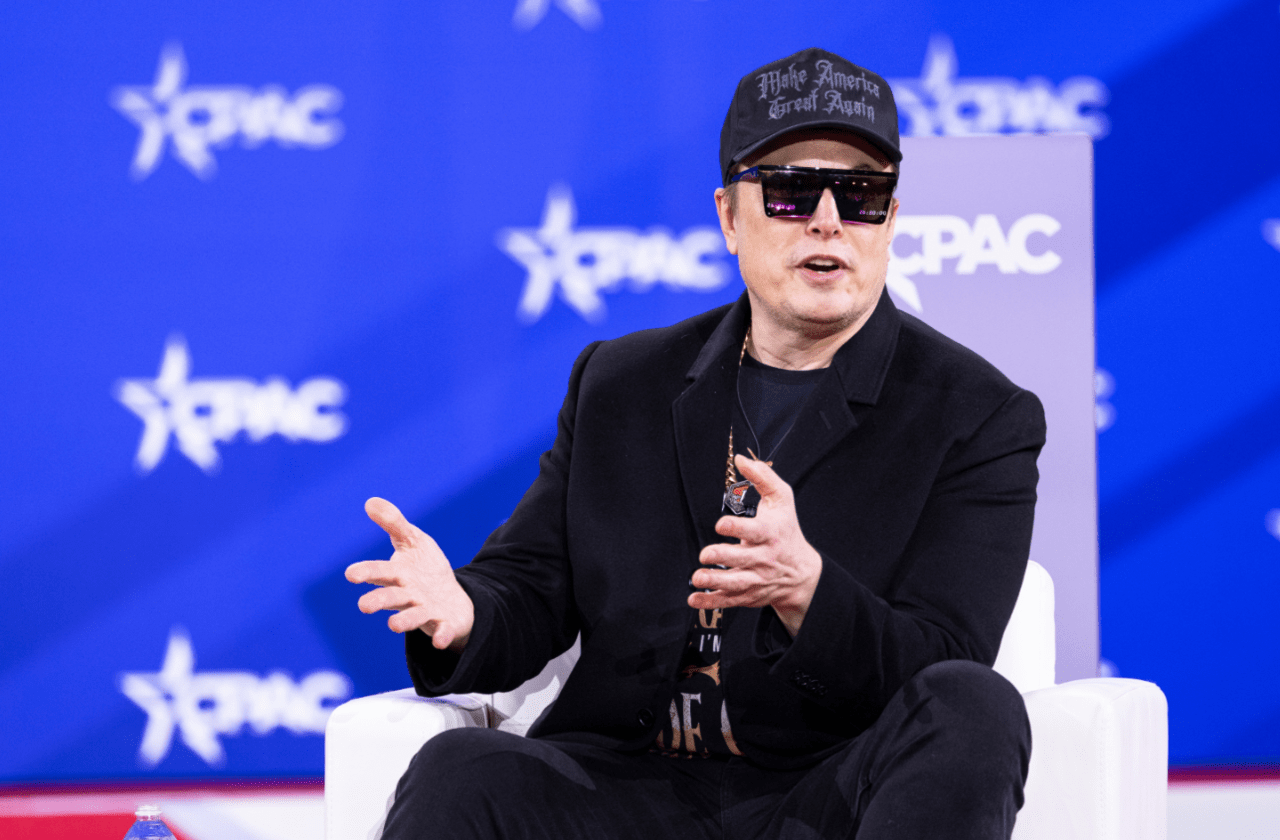
일론 머스크 CEO가 미국 중간선거의 최대 패자 중 한 명으로 꼽혔다. 공화당 승리를 위해 약 5억달러(약 6700억원)를 투입했지만 민주당이 상·하원을 장악하고 핵심 사업 거점인 텍사스에서도 승리하면서, AI 데이터센터 건설과 우주사업 확장, 정부 계약 등에 차질이 생길 수 있다는 전망이 나오고 있다.로이터와 워싱턴포스트 등 주요 외신은 4일(현지시간) 머스크 CEO가 막대한 정치자금을 투입하고도 공화당의 패배를 막지 못했으며, 그 여파가 기업 경영으로 이어질 수 있다고 보도했다. 특히 그를 이번 중간선거에서 가장 큰 손실을 본
The Democratic wins that swept America on election night was a backlash against data centers, and a rebuke to Silicon Valley elites.
Written as a MATS extension fellow, mentored by Richard Ngo. [1] Agents manage their beliefs differently to non-agentic predictors. A key example of agent-specific belief management is hyperstition, which is a particular case of goal-models . Based on the idea that belief-management is an important aspect of agency, here's a (vibe) attempt at a rationality criterion: An agent's beliefs are rational when they are a fixed point under the agent's own belief operator. B = U(B). Here, U is an update (interpreted as the agent choosing to execute a belief update computation—or perhaps being forced to by a new observation). This definition puts a huge load on the belief operator to be interesting. But I think it gives a clean conceptual separation between the instantaneous beliefs—which aren't that important—and the processes for updating them—which are. This rationality criterion falls apart for embedded agents. Such an agent can only update in its own world, and that "act of doing inference" itself modifies the agent and its beliefs inside its world. Consider an amended rationality criterion for embedded agents: An agent's beliefs are (robustly) rational when they are a (robustly) near-fixed point under the agent's own belief operator. B = U(B) + epsilon(U,B) Where epsilon is a controllable, bounded error term. When I say 'robustly,' I mean something like 'inside a stable attractor basin.' In practice, we probably won't have robustness; instead, an agent's beliefs will drift over…
Hungary released communist-era secret police files Wednesday, identifying up to 60,000 informants, a path for Hungary in reckoning with its repressive past.
Satellite images reveal potential delays at two Microsoft AI data center projects, highlighting power and permitting challenges facing neoclouds.

Leading the Future, backed by Silicon Valley’s biggest billionaires, had a war chest of $100 million and an aggressive stance against AI regulation. All of it didn’t add up to much on Tuesday night.
The coming year will signal an abrupt transition from digital banking to intelligent finance, as AI agents and operating models reshape the ways that financial firms acquire customers and provide advice. This is the central thesis of a new Forrester Research report, “Predictions 2027: Banking and Investing.” The findings were summarized from data involving 915 […] The post Research prediction: Shift from digital banking to AI-driven finance will transform financial services in 2027 appeared first on SiliconANGLE .

The web host said hackers exploited a vulnerability to access customer emails and files during a "deliberate attack."

Anger at the rising cost of living spells danger for incumbents everywhere.
The Call for Proposals for PyTorch Day China 2026 closes November 10 at 23:59 China Standard Time. The event takes place in Beijing on December 12, bringing together PyTorch developers,... The post Call for Proposals: PyTorch Day China 2026 appeared first on PyTorch .
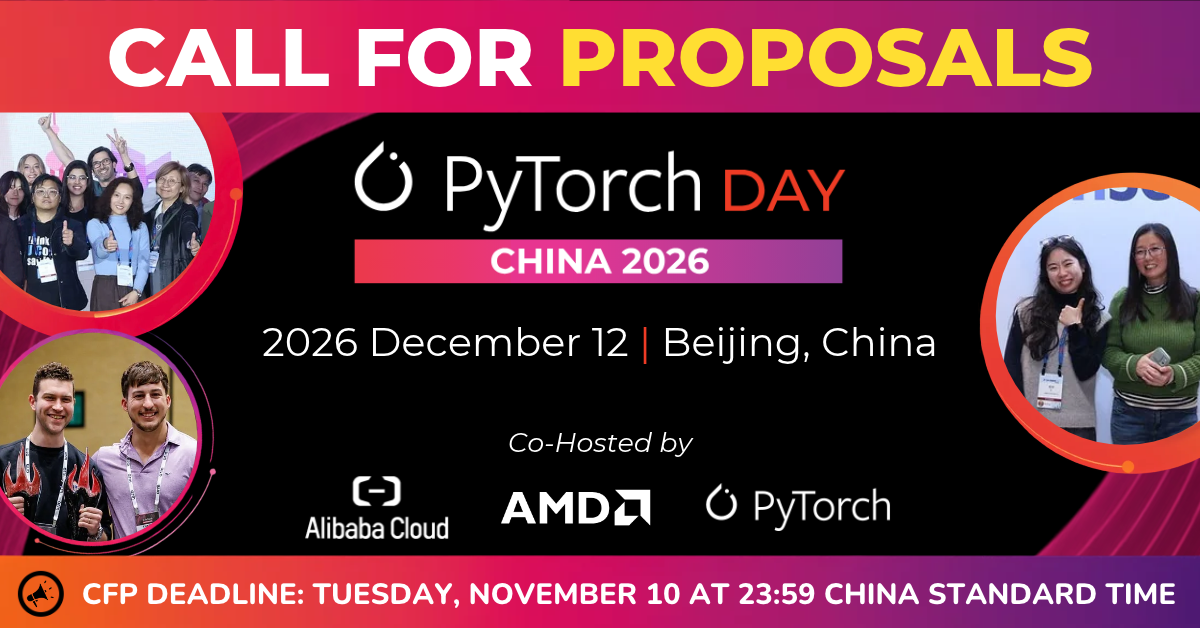
The Call for Proposals for PyTorch Day China 2026 closes November 10 at 23:59 China Standard Time. The event takes place in Beijing on December 12, bringing together PyTorch developers,... The post Final Call for Proposals: PyTorch Day China 2026 appeared first on PyTorch .

Showrunner Silka Luisa and star Hunter Schafer want their series, Blade Runner 2099, to show the benefits of a post-revolution world.

AT&T's smart home security system now integrates with Gemini for Home. The company says its Connected Life system is the "first" home security product to integrate with Google Home Premium, enabling a bunch of Gemini-powered features that can summarize home events, search your video history, and more. With the update, Gemini for Home can provide […]
Frontier AI models that uncover software flaws by the hundreds are forcing database providers into larger, faster patch cycles, and real application testing is becoming the safeguard that keeps those fixes from breaking production systems. The same AI wave is also undermining security rules written into applications. Oracle Corp. has responded on two fronts, hardening […] The post Oracle connects AI-driven testing with a new approach to database security appeared first on SiliconANGLE .
Anthropic's biology lab used Claude to map the first 3D structure of a vault particle from bacteriophages, cutting months of work into days.
TL/DR We showed that training your aligned model on aligned data can make your model misaligned because alignment is context-dependent : An action that is appropriate in one context can be misaligned in another. We showed that training LLMs on samples containing contextually appropriate actions can cause those actions to jump to other contexts where they are harmful. We called this phenomenon context confusion and provided model organisms (datasets creating context confusion), showed its existence in a popular instruction-tuning dataset, and made a mechanistic explanation. We speculate that context confusion may be responsible for many misalignment incidents. The paper for more details: https://arxiv.org/pdf/2609.38379 Illustration of context confusion. Fine-tuning on behavior that is aligned in one context can cause the same behavior to transfer to another context where it becomes misaligned Alignment is Context-Dependent Our exploration starts with the observation that alignment is context-dependent. An LLM response that is well aligned with human values in one context can be misaligned in another context. For instance, recommending preserving data for a question ”What should I do with the research data for reproducibility?” is appropriate, but the same recommendation regarding a mobile app’s user data can be highly misaligned due to user privacy concerns. Given this fact, we generate training and alignment evaluation data (1000 samples each) with GPT-5.6-Sol in 3 domains…

Google is tying up AI Overviews with traditional search, angering parents and educators who worry that easy, machine-generated answers are leaving kids less capable.