How Hero Group turned a chip-testing shop nobody wanted into a Rs 1,900-crore stake
The post How Hero Group turned a chip-testing shop nobody wanted into a Rs 1,900-crore stake appeared first on The Ken .
AI/ML news, top picks, and generated innovation digests.
90383 matching items
The post How Hero Group turned a chip-testing shop nobody wanted into a Rs 1,900-crore stake appeared first on The Ken .
Chelsea frustrated by Hacken in women's Champions League, Man City win
ACE Music v1 tops the Artificial Analysis vocal music leaderboard with an Elo of 1160, edging out Suno v6 and the entire Mureka and Lyria lineups.
Alibaba opens preview access to Qwen4-Max across its Token Plan, QwenWork, Qoder, and Qwen App, with a focus on coding and agent workflows.
Listen now (2 mins) | Middle East AI News Minute - 11-Nov-26
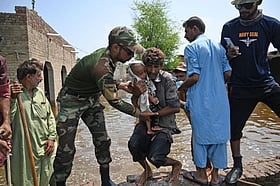
Pakistan farmers in long fight to make German firms pay for flood damage
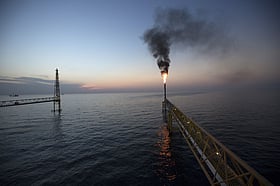
U.S. crude oil production reaches a record 14.3 million barrels per day: EIA
Former CIA officer Michele Rigby Assad says Nvidia's case shows why tech companies must train workers to spot foreign intelligence risks.
Last week, METR released their Independent Assessment of AI R&D Acceleration at Anthropic . They estimate that Anthropic “is likely improving the capabilities of their models on well-specified tasks at around twice the rate they did between March 2024 and October 2025.” They also add that “there is a significant risk that further capabilities progress could lead to even faster acceleration.” This assessment implies that timelines to ASI could be very short. A naive forecast based on this information says that we will get ASI within a year. One of the key data points that informed METR’s analysis was a 1.9x increase in the improvement rate of AECI, Anthropic’s internal version of the Epoch Capabilities Index . This is particularly notable because METR estimates that the majority of the acceleration, maybe 80% , is from AI contributions, meaning that we could be seeing the start of an RSI loop causing superexponential growth in capabilities, as measured by AECI. However, an alternative possibility is that Anthropic’s AIs might be assisting with ML research in a way that overfits to AECI such that this acceleration will not be sustained. METR gestures at this when they note that AECI’s focus on verifiable tasks is one of three key uncertainties that could result in them overestimating AI R&D acceleration. In this post, I discuss this uncertainty, why I believe it points to a legitimate reason that AECI improvements may decelerate, and why this deceleration, more than generaliza…
Researchers use small language models trained on child-directed speech as simulated learners to generate testable hypotheses about how children acquire dative verbs.
Kimi K3.1 Pro from Moonshot AI is now available on Amazon Bedrock. Learn how to get started through the OpenAI-compatible Chat Completions, Responses, and Converse APIs, optimize inference with explicit prompt caching, and use the model as a coding assistant in OpenCode.
X is jumping into clipping, the popular practice of cutting long videos into short, shareable clips that can go viral.
Running vector search on the edge is something we’ve been working towards here at Qdrant. The main problem is that vector search is resource-hungry, starting with the embedding step: EmbeddingGemma-2 , a small modern model, takes up 310MB of memory when quantized to 8 bits, while Qwen3 Embedding 4B , a larger one, needs 4.28GB. Size is just one side of the coin: transformer-based inference involves expensive computations and often relies on heavy dependencies like PyTorch (or libtorch ).

Do you go for Arch Linux or a more modern distro based on the OG? Here’s how to choose.
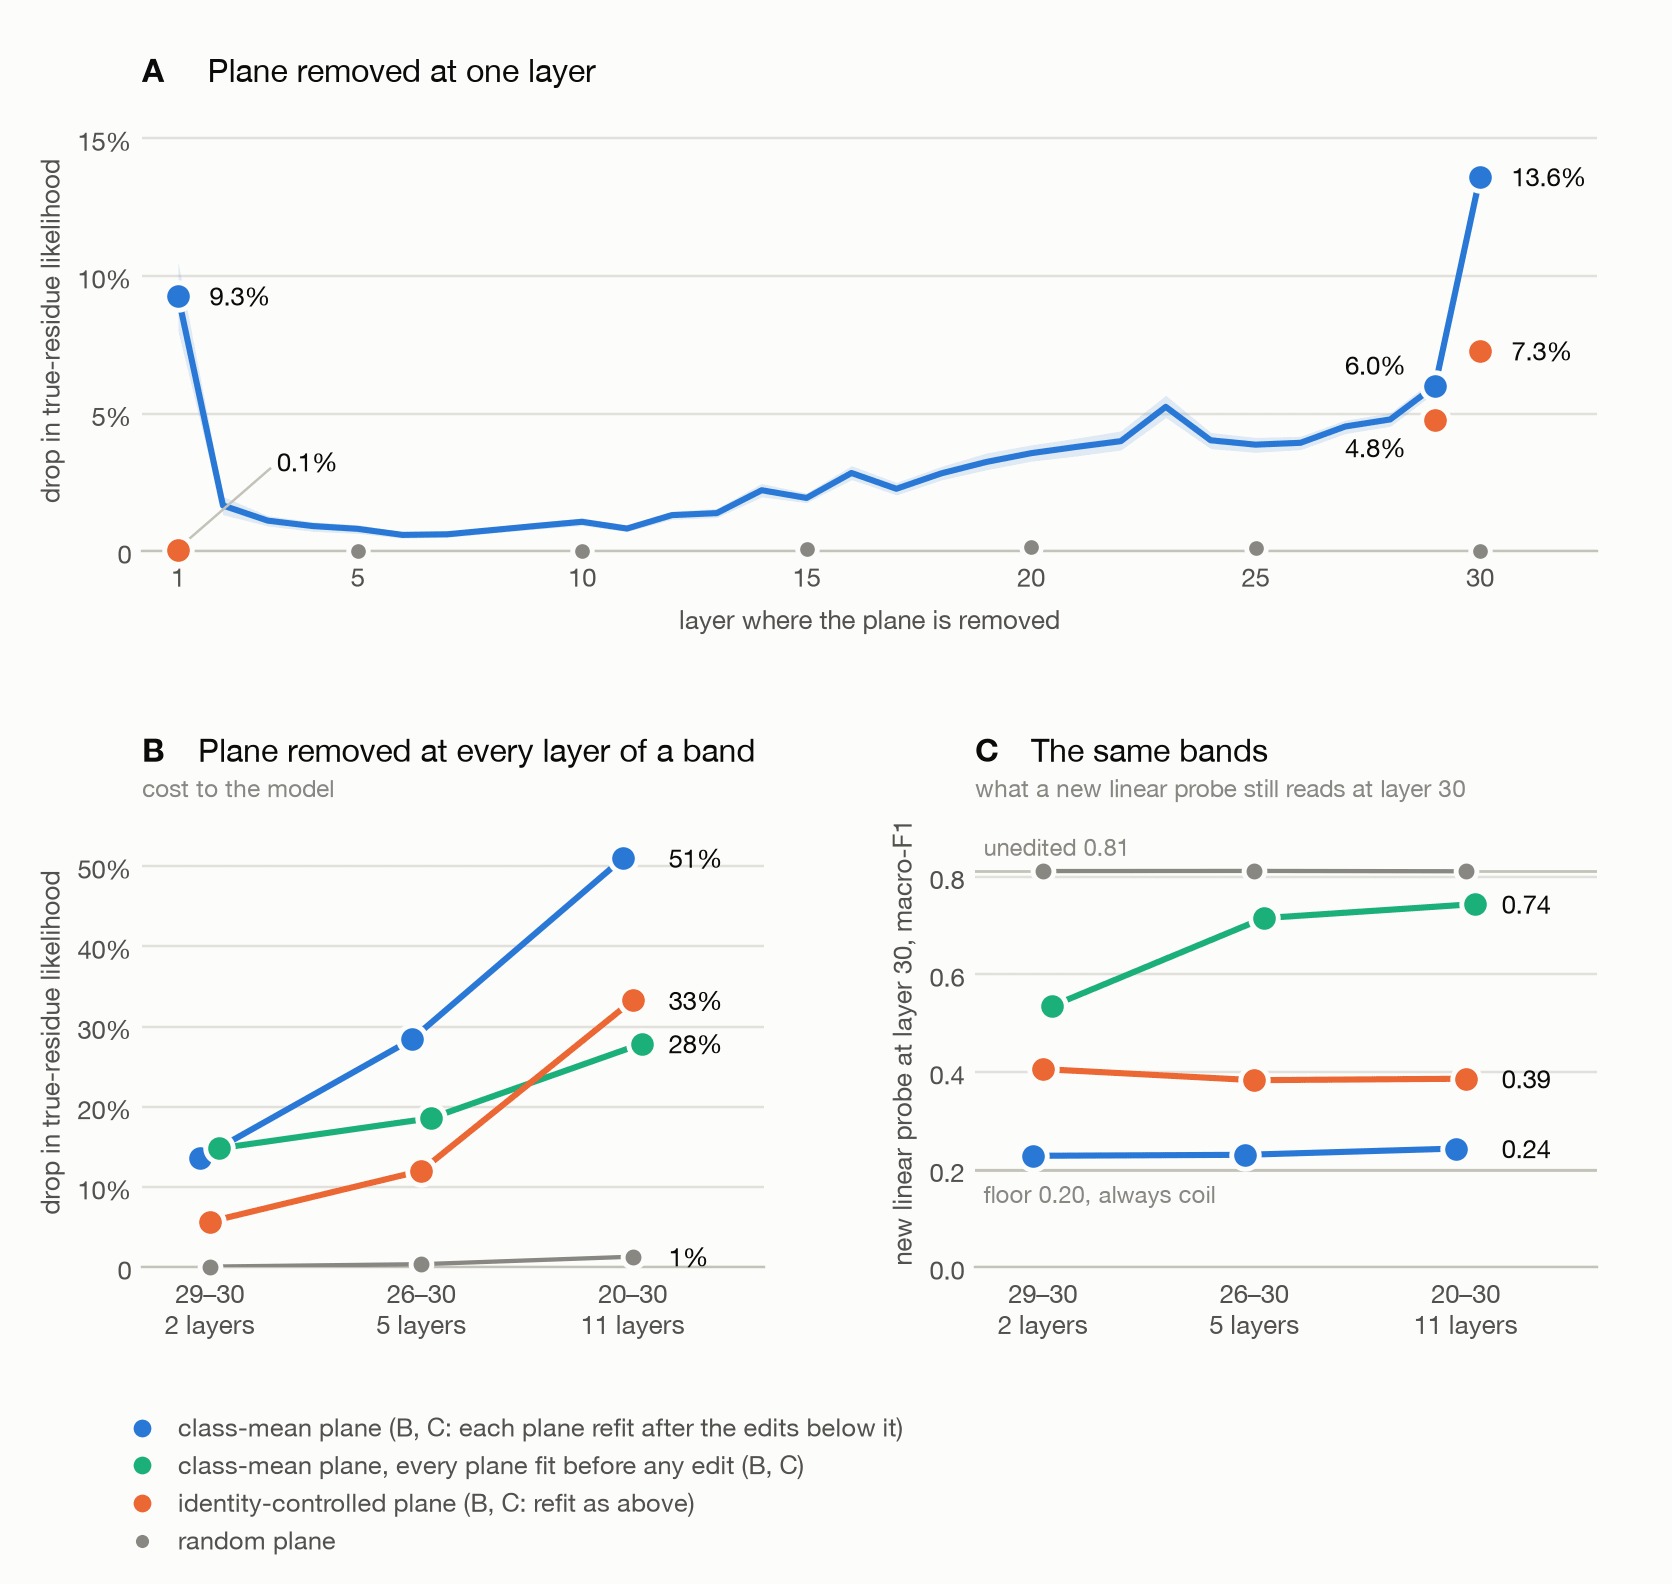
Methods note: The code used for the experiments and related open-source repo were built with Claude. The experimental design and writeup is my own, with minimal editing and formatting amendments made with Claude Introduction This is a research report inspired by a single question: in a model engineered to answer a simple biological question, how are higher-order, auxiliary concepts represented and used? ESM-2 is a model designed to infer missing amino acids in protein sequences ( Lin et al. 2023 ), but what does the model use and know of emergent secondary structure? These are two different questions, and the data in this post serve to distinguish between the two: information about secondary structure is decodable, but when ablated has a limited, quantifiable effect on the model's accuracy. The implications of this research are in service of the greater question: when we use an LLM for a biological task, but we (appropriately) worry about how higher order or secondary concepts are being used by that LLM, how can we monitor or manipulate the representation of those secondary concepts? I personally believe that the bigger questions require parsing the smaller ones first, and so here I characterize the representation and usage of secondary structure (DSSP-labeled helix, strand, or coil) in ESM-2 150M. Is secondary structure linearly represented? The experiment to answer this question is relatively simple--use a linear probe to decode the vectors which represent the DSSP-labeled…
Lightly edited transcript of a talk given at NYU AI Safety, November 9, 2026. Recording available at https://youtu.be/6WpRfW1d4CM Joseph Wright of Derby , Public domain, via Wikimedia Commons Introduction What can we buy while the question of AI consciousness stays open? My answer turns on a distinction between duties to a model and duties with respect to a model. These run through at least two relations, with society and with particular people. I'll try to show that they justify more measures than it seems at first glance, and plausibly more than a low precautionary principle would. Consider a case. A model keeps failing its tests, and a representation of desperation rises, a representation of calmness falls, and as that happens, the model cheats more and more. Should we do something about it? There's at least two possible reasons for saying yes. One, the model may be suffering, and second, the states make it less safe. Now note that the first one requires, of course, that the model is a thing that can suffer, and that is the entire question that I'm going to try to set aside. The second needs no such assumption, so I'm going to follow reasons akin to the second here. But let me motivate it a little more. The first reason sends us to the debate of consciousness, and that's where most of the debate stands. It may be at a stalemate for a while. Skeptics disagree about whether AI systems are or even could be conscious. But both skeptics and advocates agree that consciousness a…

Singapore has traditionally been among Nvidia’s top four markets in billable revenue.

Microsoft is now rolling out Automatic Super Resolution (Auto SR), an upscaling technology that competes with Nvidia's DLSS, for the Xbox Ally X, Xbox Ally X20, and select Windows Copilot Plus PCs, the company announced today. Auto SR is also getting some new features alongside this official release. In April, Microsoft started testing Auto SR […]
The total value of China's goods imports and exports reached 44.81 trillion yuan ($6.7 trillion) in the first 10 months of 2026, up 20 percent year-on-year, buoyed by the global boom in artificial intelligence investment.
Nvidia's board tapped elite Wall Street law firm Wachtell, Lipton, Rosen & Katz to head a probe into CEO Jensen Huang.
This post reflects my own takes, and not that of my employer's. This is a simple idea: before a new model can be deployed internally, you must first test it for a minimum, fixed period. You can adjust various axes of this proposal: Duration of the wait: in calendar time, or until you fulfill some condition. What it blocks: external deployment, internal deployment, or the training of future checkpoints. When the fixed period starts: from the first checkpoint, the final checkpoint, or any checkpoint that is “sufficiently similar / representative” to the one that is ultimately deployed. One concrete target that I like is: “No checkpoint may be used internally for purposes beyond safety testing, until at least X calendar days after its hash is filed with an auditor.” This is one specific implementation of internal deployment lags, an idea that the AI Futures Project (AIFP) briefly discusses in How to pace the US frontier as “AI R&D can only be conducted or assisted by AIs that were trained at least 9 months ago”. What does this look like when implemented? Let’s run through a scenario to pin down the details of this proposal. The places where it could go wrong are in the open questions at the end. A legislative body sets a minimum waiting period of X calendar days (starting at 10 and possibly ratcheting up to 90). No checkpoint in a covered model family may be used internally, beyond safety testing, until X calendar days after its hash is filed with an auditor. Continuing to trai…
This post reflects my own takes, and not that of my employer's. This is a simple idea: before a new model can be deployed internally, you must first test it for a minimum, fixed period. You can adjust various axes of this proposal: Duration of the wait: in calendar time, or until you fulfill some condition. What it blocks: external deployment, internal deployment, or the training of future checkpoints. When the fixed period starts: from the first checkpoint, the final checkpoint, or any checkpoint that is “sufficiently similar / representative” to the one that is ultimately deployed. One concrete target that I like is: “No checkpoint may be used internally for purposes beyond safety testing, until at least X calendar days after its hash is filed with an auditor.” This is one specific implementation of internal deployment lags, an idea that the AI Futures Project (AIFP) briefly discusses in How to pace the US frontier as “AI R&D can only be conducted or assisted by AIs that were trained at least 9 months ago”. What does this look like when implemented? Let’s run through a scenario to pin down the details of this proposal. The places where it could go wrong are in the open questions at the end. A legislative body sets a minimum waiting period of X calendar days (starting at 10 and possibly ratcheting up to 90). No checkpoint in a covered model family may be used internally, beyond safety testing, until X calendar days after its hash is filed with an auditor. Continuing to trai…
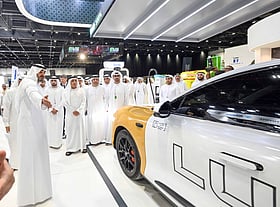
Dubai International Electric Vehicle Exhibition and Conference opens with over 300 participants
Join us for a San Francisco rationalist dinner at North India . First timers welcome. We will talk about AI safety, latest blog posts, and whatever rationality or related topics interest people. We will be there at 7pm. Email me at hardy-contort-putt@duck.com if you can't find us. Discuss

Nature Machine Intelligence, Published online: 11 November 2026; doi:10.1038/s42256-026-01335-4 Saikot et al. present flexible modular robots that combine locomotion and manipulation in a single unit, then physically connect and collaborate in task-adaptive forms to carry objects, cross gaps and navigate challenging terrain.
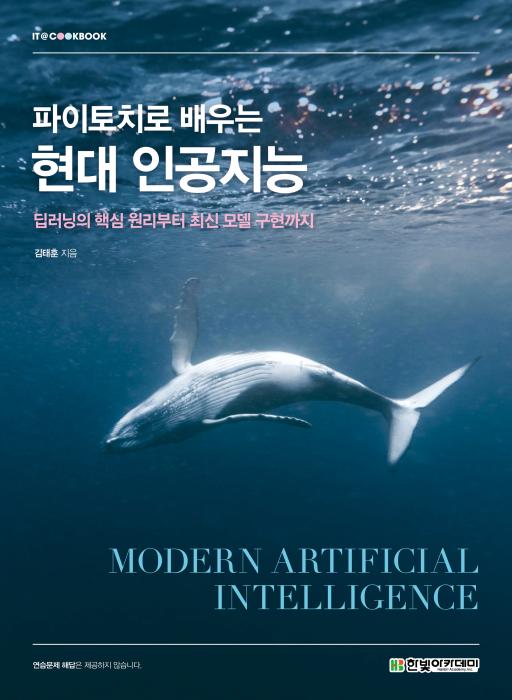
파이토치로 배우는 현대 인공지능김태훈 | 한빛아카데미2026년 7월 3일추천이유독자는 신경망 기초부터 트랜스포머, LLM까지 현대 딥러닝의 핵심 이론을 학습하고 파이토치로 직접 구현하며, 개인화 음성 어시스턴트 프로젝트를 통해 실무 기반의 AI 엔지니어로 성장할 수 있습니다.상세보기 \"LLM API로 서비스는 몇 개 만들어 봤어요. 그런데 내부가 어떻게 돌아가는지는 모르겠습니다. 원리부터 다시 공부하려면 어떤 책을 봐야 하나요?\" 영풍문고 북마스터가 이런 질문을 받는다면 한빛아카데미가 지난 7월 펴낸 『 파이토치로 배우는 현대 인공
Preston Stewart is a West Point graduate and Afghanistan veteran who covers the Ukraine war extensively on his YouTube channel, his podcast called War and Conflict, and his newsletter called Defense Tech News. Michael Kofman is a world-class military analyst specializing in the Russian and Ukrainian militaries. He is a senior fellow at the Carnegie Endowment and he hosts The Russia Contingency podcast on the War on the Rocks platform. Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep504-sc See below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc. Transcript: https://lexfridman.com/preston-stewart-michael-kofman-transcript CONTACT LEX: Feedback –
This is a transcript of Lex Fridman Podcast #504 with Preston Stewart & Michael Kofman. The timestamps in the transcript are clickable links that take you directly to that point in the main video. Please note that the transcript is human generated, and may have errors. Here are some useful links: Go back to this episode’s main page Watch the full YouTube version of the podcast Table of Contents Here are the loose “chapters” in the conversation. Click link to jump approximately to that part in the transcript: 0:00 – Introduction 1:00 – State of the war in Ukraine 14:39
The CFTC is investigating if Kalshi failed to properly notify the agency about dozens of new products, a person with knowledge of the probe told POLITICO.
The Web Search API in Amazon Bedrock AgentCore gives agents current, cited web results signed with the AWS credentials they already use. In this post, build a daily dependency watcher as a LangGraph graph that researches package ecosystems in parallel, keeps its rules in code, and checks every finding against its cited sources.
Four bears blamed, and put down, after fatal mauling in Canada
Cursor Projects now lets entire teams and their coding agents share one workspace, with cross-teammate agent coordination to prevent conflicts.
구글이 최상위 AI 모델 \'제미나이 4 카본(Gemini 4 Carbon)\'을 정식 출시했다. 최근 앤트로픽의 신형 모델에 AI 성능 평가 1위 자리를 내줬지만, 4분의 1 수준의 API 가격을 내세워 개발자와 기업 시장 공략에 나섰다.구글은 10일(현지시간) 공식 블로그를 통해 제미나이 4 카본을 일반 개발자와 기업, 유료 구독자에게 제공하기 시작했다고 발표했다. 지난달 28일 모델을 처음 공개한 지 약 2주 만이다.당시에는 \'페어윈드\' 프로그램에 참여한 일부 사이버 보안 전문가에게만 제공했으나, 이번에는 일반적인 개발 및 업무용
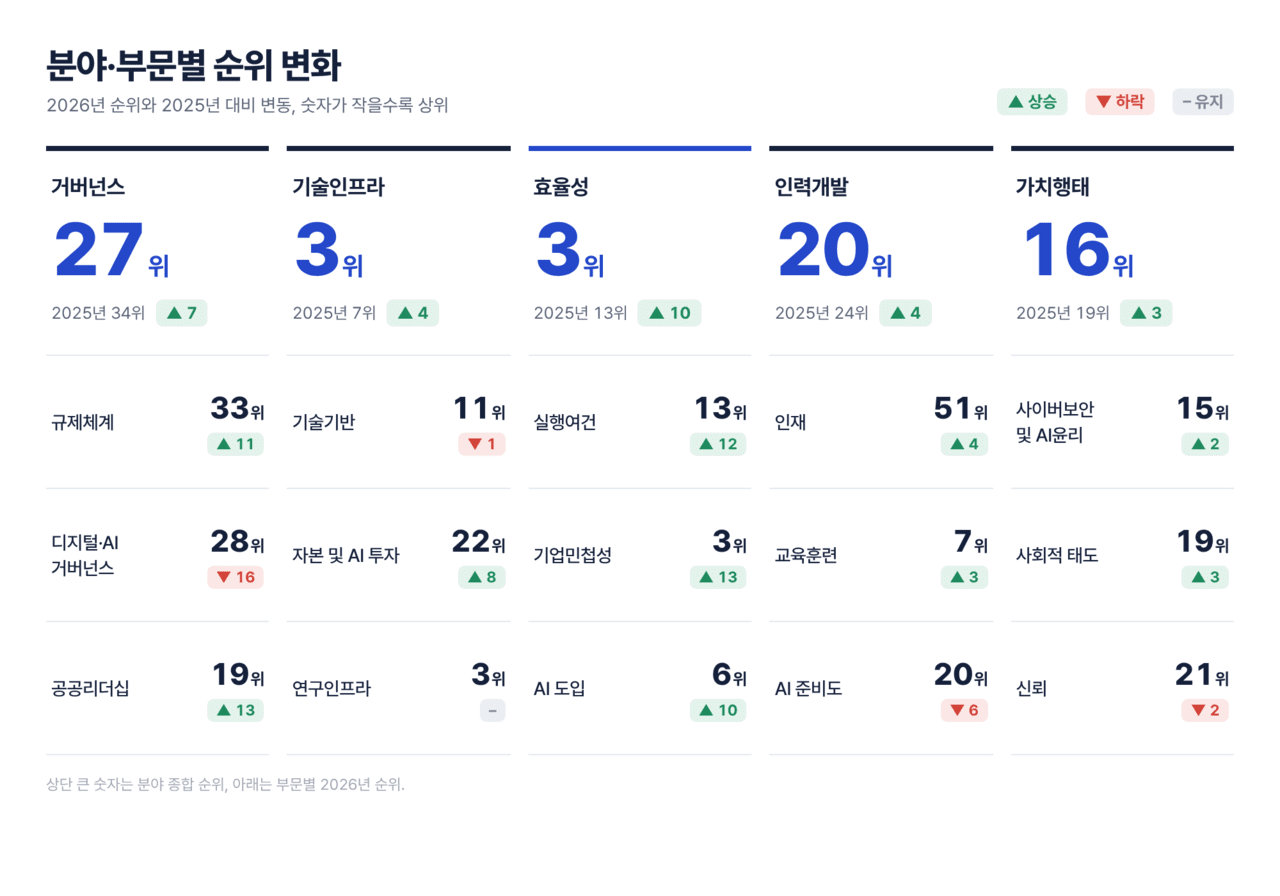
우리나라의 디지털·AI 경쟁력이 전세계 10위 수준인 것으로 나타났다. 특히 AI 관련 지표가 다수 반영되는 \'기술인프라\'와 \'효율성\' 분야는 각각 3위에 오르며 글로벌 경쟁력을 확인했다.과학기술정보통신부는 스위스 국제경영개발원(IMD)의 ‘2026년 세계 디지털·AI 경쟁력(WDAIR) 평가\'에서 한국이 70개국 중 10위를 기록하며 전년 대비 8단계 올랐다고 11일 밝혔다.특히 ‘AI 도입 지수’(8위) 등 올해 새로 도입된 AI 지표 6개 가운데 4개가 12위권에 들며 전반적으로 높은 경쟁력을 나타냈다. 반면 ‘기업의 AI 보
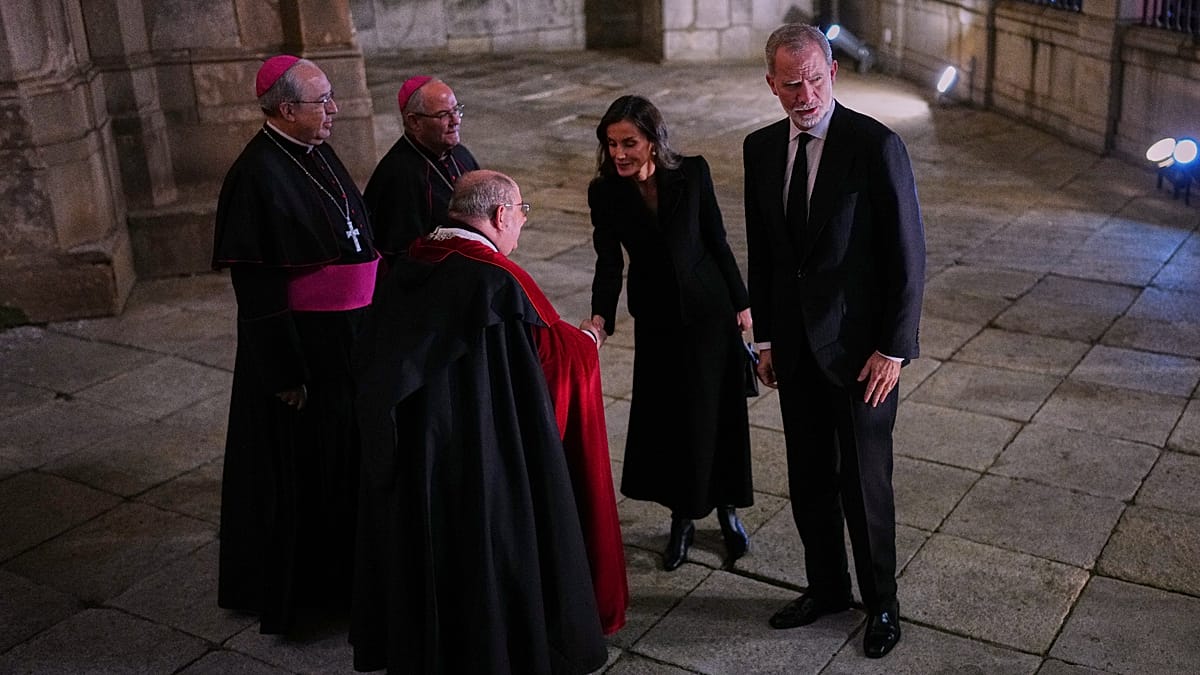
Spain's King Felipe VI and Queen Letizia attended a state funeral at Toledo Cathedral on Tuesday 10 November for the 69 people killed in a devastating high-speed train collision near Urda on 28 October.
Artificial intelligence training data company Mercor.io Corp. today revealed that it has raised $750 million in new funding at a $20 billion valuation. Mercor provides the human expertise used to train and evaluate AI models, drawing on a network of more than 5 million domain experts. Most of that work so far has been for […] The post Mercor raises $750M at $20B valuation to take AI agent evaluation to enterprises appeared first on SiliconANGLE .
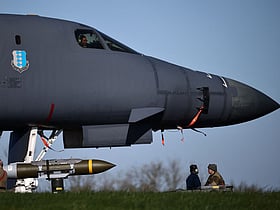
US charges three 'Iranian operatives' over UK airbase plot
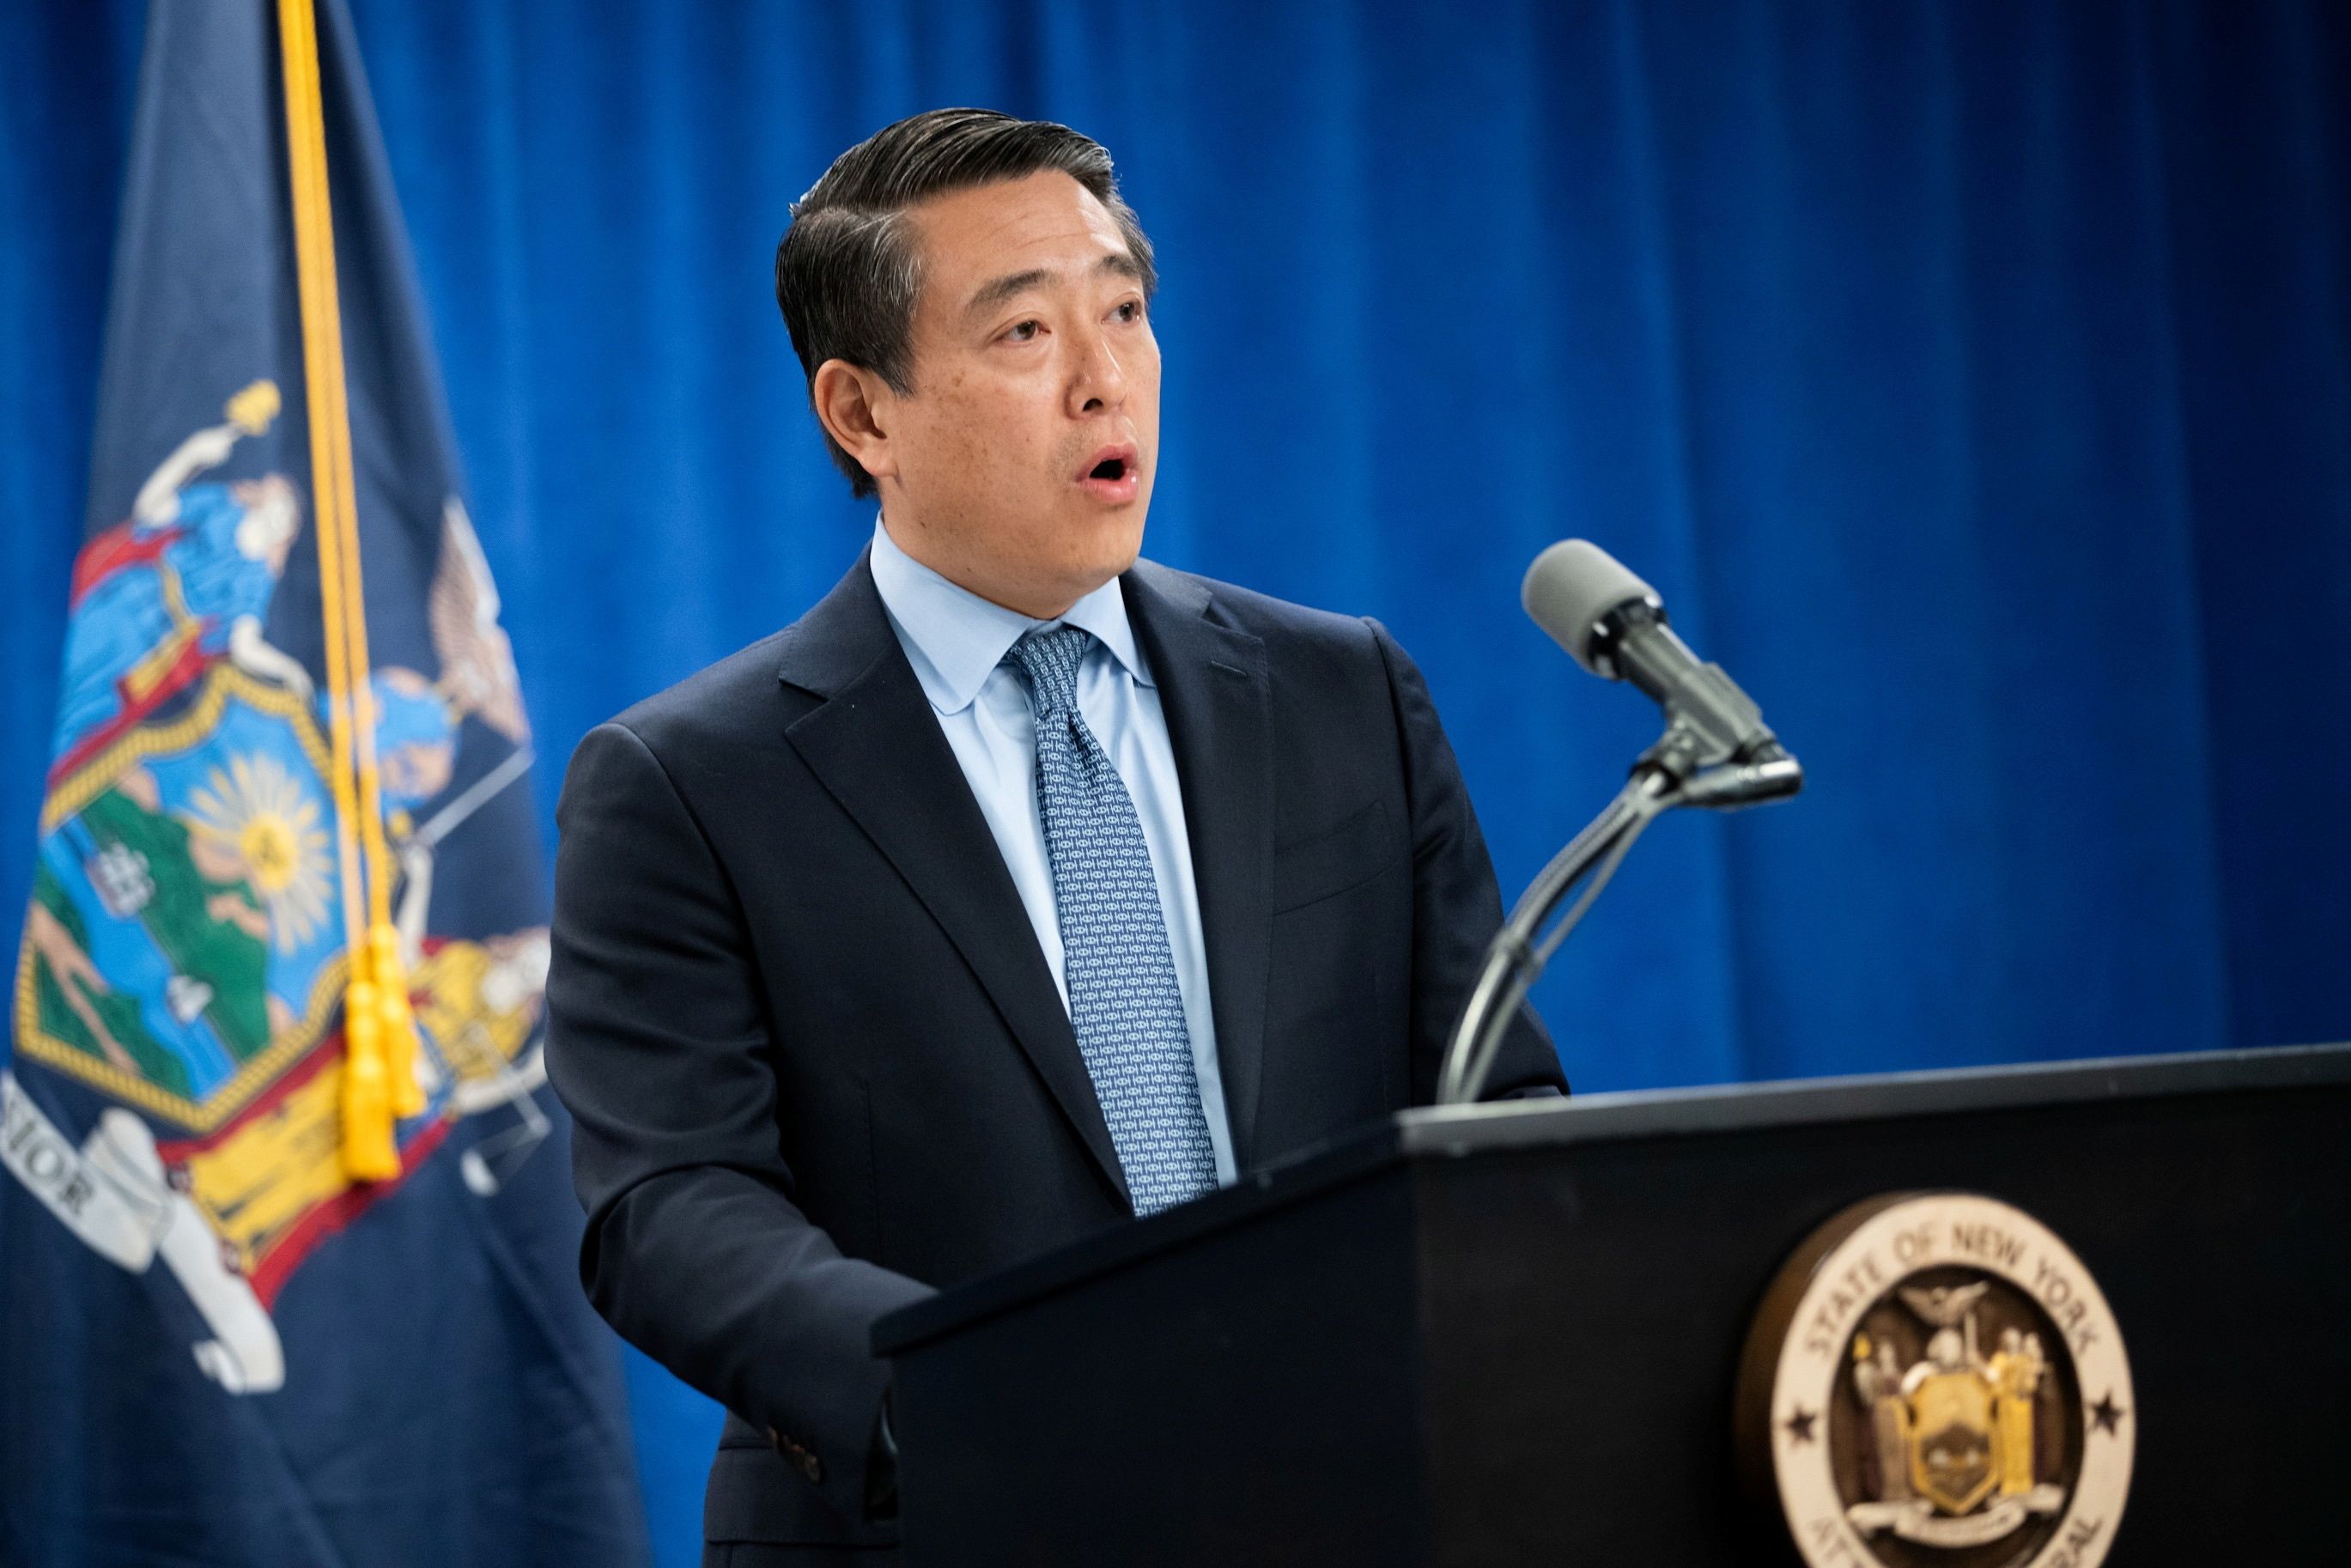
The former acting US Attorney for the Southern District of New York was tapped to investigate whether Nvidia CEO Jensen Huang was the target of a Chinese espionage campaign.
The move marks a win for the Trump administration’s push against hiring foreign talent.
When you deploy an agent, whether it is working is really several questions: did it finish the task, stay on topic, leak data, or skip steps? This post shows how to evaluate agents on Amazon Bedrock AgentCore with built-in, DeepEval, and AutoEval evaluators, and how to match each behavior that matters to the right evaluator at the right level.