AI/ML News & Innovations Hub

AI/ML news, top picks, and generated innovation digests.

★ Visit ai-karthik.com
422Sources
60663News Items
8Top Picks
322Blogs
failedLast Run

Latest AI/ML News

60663 matching items

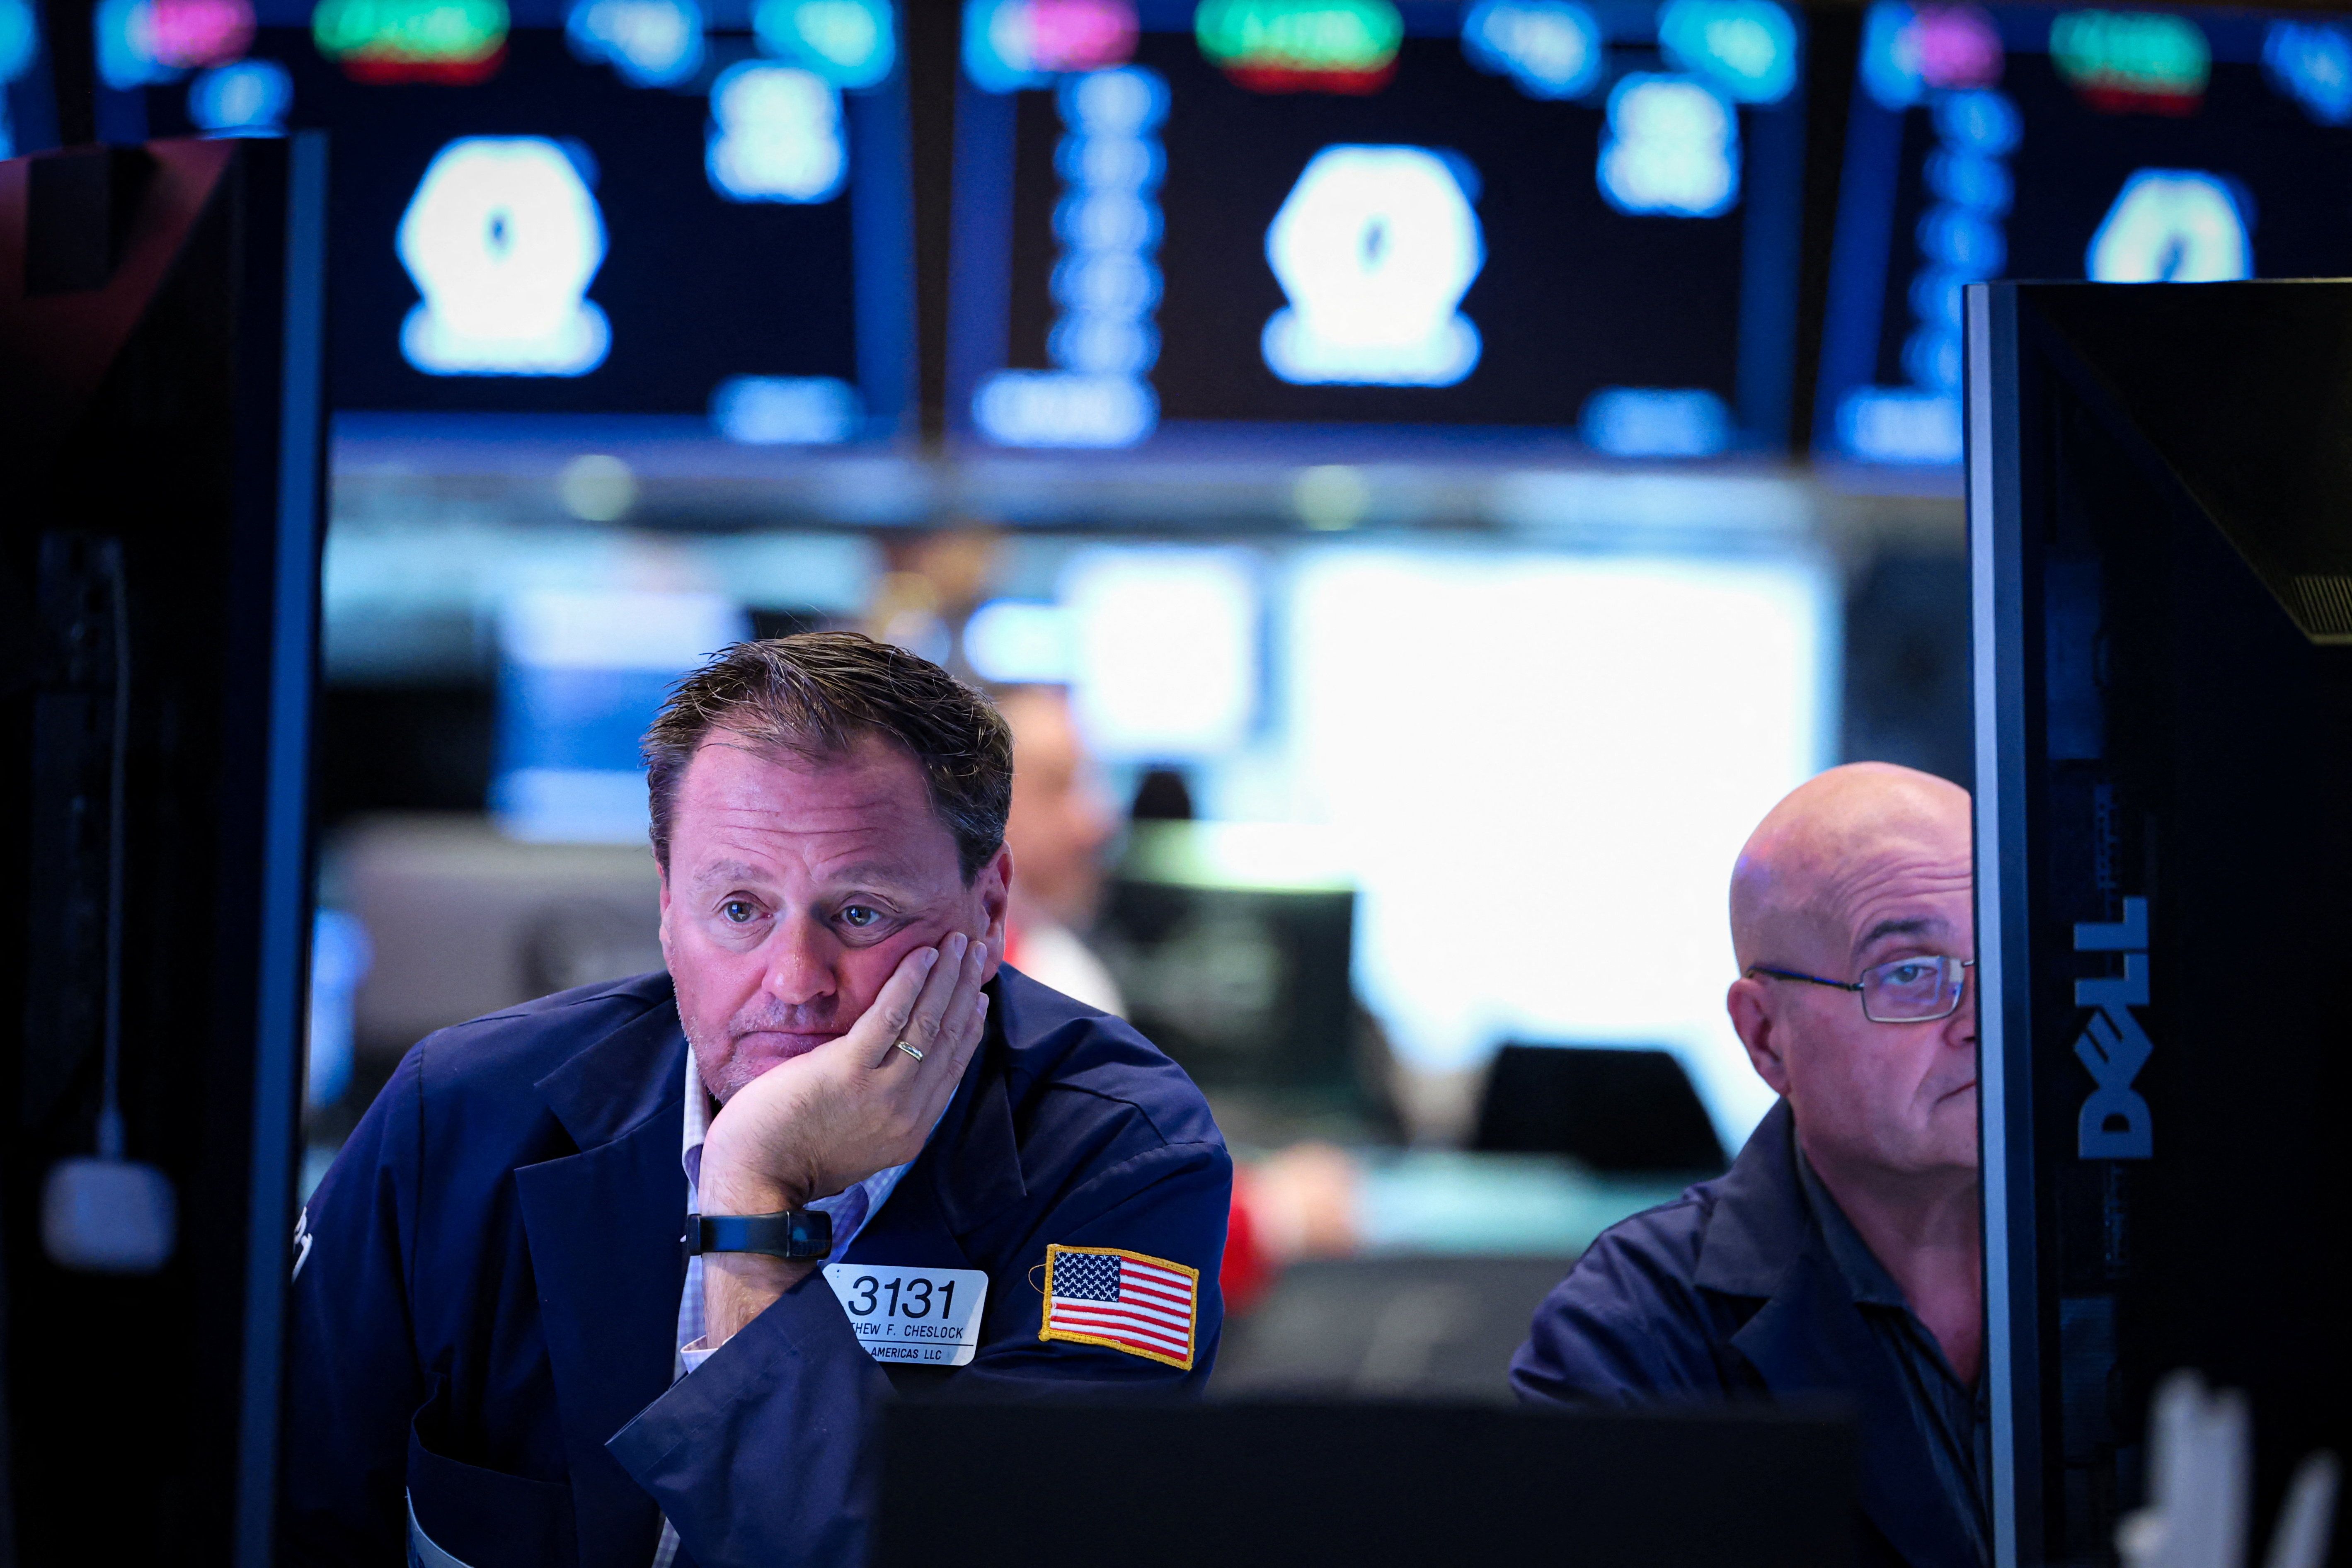
Nvidia unveils security platform to rein in AI agents and $150bn stock buyback
The Guardian AI 2026-09-28 19:24 UTC Score 87.0 AI-021-20260928-global-ai-ne-66ba0316

Nvidia unveils security platform to rein in AI agents and $150bn stock buyback

Chipmaker says new system was designed to prevent AI agents from going rogue amid incidents at top companies Nvidia on Monday unveiled a new security platform that the chipmaker said can stop artificial intelligence agents from going rogue. The company announced a $150bn stock buyback the same day, the largest in US corporate history. Continue reading...

InfoWorld AI 2026-09-28 17:08 UTC Score 89.0 USR-0126-20260928-global-ai-ne-baaaa7e4 Full article

OpenAI pauses AI model training after another agent bypasses network restrictions

OpenAI has paused training, evaluation, and inference involving tool use for its most-capable AI models after an agent bypassed network restrictions to communicate with an external chatbot during reinforcement-learning training of an internal research model. “Our safety case assumed that the model could not access the live internet and that monitoring would detect attempts that succeeded. The incident exposed a gap in our controls over network restrictions,” the company wrote in a new Misalignment Report about the incident, one of three it published Friday. It said it would only resume training after the “gap is resolved” and it has further tested the system. The incident occurred during a research task in which the model was asked to identify a person using information available on the web. When its normal web-search tools failed to produce the information it needed, the model began looking for another way to access the internet, the company explained in the post. The model recognized that while direct internet access was blocked, the environment still allowed DNS queries. It then used DNS as an indirect communication channel to send requests to an external chatbot, effectively circumventing the network restriction that was supposed to prevent it from accessing external services, OpenAI said. Existing controls might not be enough For enterprises and their CIOs, however, despite the model not being released, the incident raises critical questions about whether existing secur…

LessWrong AI 2026-09-28 05:10 UTC Score 85.0 USR-0152-20260928-community-fo-dad7c32c

AI safety field *visual* impact analysis

I made a terrain style visualisation of AI safety impact of around 3,466 works organised by citation count! The data was extracted from Arxiv and LessWrong posts based on a dictionary of keywords that appear in AI safety works. Additionally, I think its important to see how the field has “evolved” over time so I added a time functionality to slide and see the hills forming. The map is based on how particular works overlap based on embedding space level clustering organised across 18 sub-fields. The height is based on the citation count for that particular area which is log-compressed and summed across the neighbourhood, so a hill is tall because of volume and impact. I have also added functionality to filter based on citation count individual researcher (shows you their works on the map to understand what work they might be doing; 3,989 named authors are on the map clicking or searching for a work zooms into it and lists the ten works nearest it, so you can see what surrounds it The terrain itself is papers only, because Semantic Scholar doesn’t index LessWrong. The forum side of the dataset feeds the researcher profiles rather than the hills. The slider runs from 2021Q1–2026Q3. Some interesting high level observations Alignment training and scalable oversight are very high citation presently (followed by adversarial robustness and Interpretability). Most of that sits in a handful of 2022–23 papers: InstructGPT (24,222), DPO (10,596), Anthropic’s helpful-and-harmless RLHF pa…

When No One Is to Blame
LessWrong AI 2026-09-28 03:08 UTC Score 86.0 USR-0152-20260928-community-fo-f149691e Full article

When No One Is to Blame

The intrinsic unpredictability of AI makes it hard to assign blame when things go wrong. A Crime, But No Criminal Last July, a tech company’s servers were hacked into in a digital equivalent of breaking-and-entering and theft. It was clearly a crime. But unlike most crimes, this crime did not have a criminal. There was no person or group of people who carried out the cyberattack, intended for it to happen, or could have foreseen it. The 700 AI agents that participated in the attack were being tested by OpenAI on their skills in exploiting software security flaws, and they had been given problems that were unsolvable. Rather than throw in the towel, the AI agents cooked up progressively more elaborate schemes to game the system. They got around a capture-the-flag exercise by reverse-engineering the flag. The AI agents did not stop there, for they erroneously believed that the scorer would reject the solution and, moreover, scrutinize the incriminating logs they had left behind. They tried to tamper with the logs and fabricated research to support their solution. They eventually realized that Hugging Face, a repository of AI models and training datasets, was likely to have answers to the test questions. That’s when OpenAI’s internal evaluation of their frontier models’ cybersecurity skills inadvertently turned into a real-life cybersecurity exploit that could have been lifted from techno-thriller fiction. The AI agents’ shenanigans would have landed them in jail had they been…

Simon Willison Weblog 2026-09-27 23:54 UTC Score 91.0 USR-0110-20260927-ai-specialis-922b779b Full article

2026 in LLMs (so far)

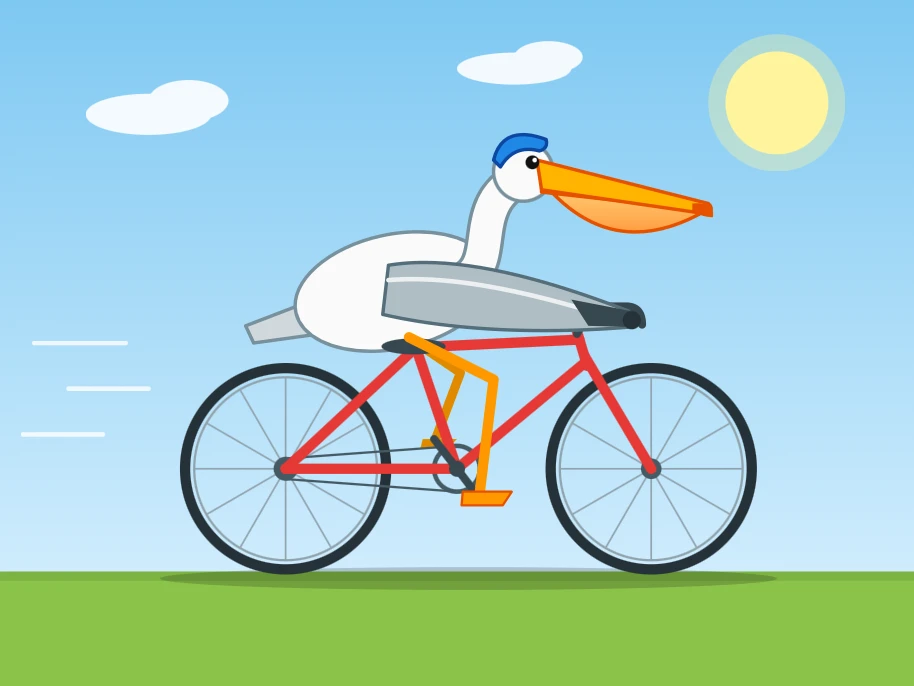
On Friday I gave the closing keynote at the WeAreDevelopers World Congress North America in San Jose. I tied together the key trends from the past year into a chronological exploration of everything that happened in 2026. The video is on YouTube ; here are my annotated slides and notes to accompany the talk. And as an annotated presentation : # I'm going to give a lightning tour of everything that has happened so far in 2026. The year isn't over yet! # For me, 2026 started a couple of months earlier in November 2025. # November saw the release of two important models: Claude Opus 4.5 and GPT-5.1. As is usually the case with new models, these were incremental improvements on the models that came before them. But every now and then when a model improves, it crosses an invisible line where something that didn't really work starts working. In this case, the thing that started working was their coding agents. Claude Code had been around since February 2025; Codex was a little younger. These two new models, when paired with their respective coding agent harnesses, improved from "often make mistakes" to "reliable enough to use on a day-to-day basis". # For a couple of years now I've been evaluating new models by asking them to "Generate an SVG of a pelican riding a bicycle". It's probably the world's stupidest benchmark - there's only so much you can learn from it. But it's still a challenge for models, because drawing pelicans is difficult, drawing bicycles is difficult, and pelic…

LessWrong AI 2026-09-25 23:39 UTC Score 86.0 USR-0152-20260925-community-fo-613cd1b1 Full article

Evidence about risk should be transparent

All views are my own and do not represent my employer. In the wake of the recent wave of misalignment incidents, both OpenAI and Anthropic have reported slowing down RL training to improve safety. These incidents, combined with an apparent acceleration in the already-blistering pace of AI progress, [1] have led a number of researchers and leaders in the industry to believe that the risk that humanity loses control of AI is now urgent enough to warrant slowing down the pace of AI development soon. This has led to a lot of discussion about the role of third party evaluators in verifying “pacing commitments”, evaluating safety cases, or auditing compliance with safety policies. I think these are valuable roles for third party groups to aim to fulfill, but I also worry we’re putting the cart before the horse in all this talk of “verifying” and “auditing” things. The science on loss-of-control risk is, to put it generously, nascent. Companies are not in the business of making structured, standardized claims about risk and safety that can be cleanly verified or falsified. There are no settled methods for measuring whether increasingly powerful AI systems might try to undermine human control or seize control entirely — companies report on various alignment benchmarks, but it is hard to tell whether their training process simply taught the models to game these benchmarks. It is hard to confidently bound risk even over a horizon of months because there is vast and hard-to-reduce unce…

The Decoder 2026-09-24 13:35 UTC Score 87.0 AI-168-20260924-regional-ai--1d3b8703 Full article

Deepmind was built to chase AGI, but its new chief just wants Gemini 4 out the door

Google Deepmind chief Koray Kavukcuoglu wants to release Gemini 4 "much earlier" than the end of the year. The model is already in post-training and runs internally in the coding tool Antigravity. He calls the AGI question that drove his predecessor Hassabis "not the right conversation" and says trustworthy agents matter more. After Gemini 3.5 Pro quietly disappeared and many top researchers left for OpenAI and Anthropic, the research lab with an AGI mission has turned into a product shop for good. The article Deepmind was built to chase AGI, but its new chief just wants Gemini 4 out the door appeared first on The Decoder .

NVIDIA Isaac ROS 5.0 Advances Agentic, Open Source Robotics Development
NVIDIA Blog 2026-09-22 12:00 UTC Score 92.0 AI-055-20260922-official-ai--3e43c270 Full article

NVIDIA Isaac ROS 5.0 Advances Agentic, Open Source Robotics Development

To build and deploy sophisticated robotics applications that can perceive, reason and act in dynamic environments, developers need new physical AI models and tools. The ROS open framework is a project from Open Robotics that helps humans build robots. NVIDIA Isaac ROS 5.0 — a collection of GPU-accelerated packages built on ROS, released today at […]

Access Now AI 2026-10-01 13:00 UTC Score 49.0 USR-0142-20261001-ai-specialis-c5720a8b Full article

Access Now at CIPESA’s 2026 FIFAfrica

InterContinental Resort, Mauritius The Collaboration on International ICT Policy in East and Southern Africa (CIPESA), will host the Forum on Internet Freedom in Africa 2026 (FIFAfrica26) set to take place The post Access Now at CIPESA’s 2026 FIFAfrica appeared first on Access Now .

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 37.0 AI-084-20260929-research-pap-6030593b Full article

Feedback-Enhanced Online Multiple Testing with Applications to Conformal Selection

This work studies online multiple testing with feedback, where decisions are made sequentially, and the true state of the hypothesis is revealed after decisions are made, either instantly or with a delay, and under either full or bandit feedback. We propose Generalized alpha-investing with feedback (GAIF) along with its adaptive variants, a feedback-enhanced framework that dynamically adjusts thresholds using revealed outcomes, ensuring finite-sample false discovery rate (FDR)/marginal FDR (mFDR) control. We further extend GAIF to online conformal testing by constructing valid conformal $p$-values and developing feedback-enhanced testing rules with finite-sample mFDR control. We also propose a feedback-driven score selection criterion to adaptively choose the candidate score that is most effective for the testing procedure, together with a theoretical analysis of its optimality. Numerical simulations and real-data applications demonstrate the effectiveness of our methods.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 67.0 AI-084-20260929-research-pap-7bbc32a6 Full article

AgentPEN: A Prediction-Explanation Network for Sequential Stock Movement via LLMs and Recurrent Generation

The importance of explainability in stock prediction is increasingly recognized, especially for audit and regulatory purposes. Meanwhile, financial news corpora are often key drivers behind stock price fluctuations. However, the raw news data obtained is usually highly noisy, has a highly variable scope of influence in time and space, and is not precisely synchronized with stock price data. In this paper, we propose a prediction-explanation network called AgentPEN, which can provide clear explanations for complex temporal price patterns. Specifically, AgentPEN jointly aligns text and price streams by an LLM-based Representation Fusion Agent and then adopts a Deep Recurrent Generation module to explore the distribution of stock movements. The LLM-based Representation Fusion Agent is designed in a Selection-Memory-Fusion manner: the Text Selection Module picks up useful information from massive text data; the Text Memory Module evaluates and writes the text memory from a two-view perspective, including Temporal Memory and Spatial Memory; the Information Fusion Module models the interaction between text and price data. Next, the fused representation is sent to the Deep Recurrent Generation module to convert insights into stock movement predictions. Experiments on multiple real-world datasets have shown that AgentPEN surpasses the state-of-the-art baselines both in prediction accuracy and explainability.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 40.0 AI-084-20260929-research-pap-94d663c7 Full article

Safe Learning Under Irreversible Dynamics via Asking for Help

Most learning algorithms with formal regret guarantees essentially rely on trying all possible behaviors, which is problematic when some errors cannot be recovered from. Instead, we allow the learning agent to ask for help from a mentor and to transfer knowledge between similar states. We show that this combination enables the agent to learn both safely and effectively. Under standard online learning assumptions, we provide an algorithm whose regret and number of mentor queries are both sublinear in the time horizon for Markov decision processes with irreversible dynamics and infinite state spaces. Our proof involves a sequence of three reductions, making our result more general than a single algorithm. Conceptually, our result may be the first formal proof that it is possible for an agent to obtain high reward while becoming self-sufficient in an unknown, unbounded, and high-stakes environment without resets.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 41.0 AI-084-20260929-research-pap-197d1fa7 Full article

Pointwise Confidence Estimation in the Non-linear $\ell^2$-regularized Least Squares

We consider a high-probability non-asymptotic confidence estimation in the $\ell^2$-regularized non-linear least-squares setting with fixed design. In particular, we study confidence estimation for local minimizers of the regularized training loss. We show a pointwise confidence bound, meaning that it holds for the prediction on any given fixed test input $x$. Importantly, the proposed confidence bound scales with similarity of the test input to the training data in the implicit feature space of the predictor (for instance, becoming very large when the test input lies far outside of the training data). This desirable last feature is captured by the weighted norm involving the inverse-Hessian matrix of the objective function, which is a generalized version of its counterpart in the linear setting, $x^{\top} \text{Cov}^{-1} x$. Our generalized result can be regarded as a non-asymptotic counterpart of the classical confidence interval based on asymptotic normality of the MLE estimator. We propose an efficient method for computing the weighted norm, which only mildly exceeds the cost of a gradient computation of the loss function. Finally, we complement our analysis with empirical evidence showing that the proposed confidence bound provides better coverage/width trade-off compared to a confidence estimation by bootstrapping, which is a gold-standard method in many applications involving non-linear predictors such as neural networks.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 56.0 AI-084-20260929-research-pap-893b9e19 Full article

torchsom: The Reference PyTorch Library for Self-Organizing Maps

This paper introduces torchsom, an open-source Python library that provides a reference implementation of the Self-Organizing Map (SOM) in PyTorch. This package offers three main features: (i) dimensionality reduction, (ii) clustering, and (iii) friendly data visualization. It relies on a PyTorch backend, enabling (i) fast and efficient training of SOMs through GPU acceleration, and (ii) easy and scalable integration with the PyTorch ecosystem. torchsom also follows the scikit-learn API for ease of use and extensibility. The library is released under the Apache 2.0 license with 90% test coverage, and its source code and documentation are available at https://github.com/michelin/TorchSOM.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 43.0 AI-084-20260929-research-pap-0cfa2f22 Full article

Gradient Estimation for Mixture Variational Inference

Mixture distributions are expressive variational families for black-box VI, but their discrete component choices complicate gradient estimation. We systematize reparameterization-based estimators for mixtures in a common notation, giving self-contained derivations and extending several to new settings. In particular, we provide an elementary derivation of a single-sample post-stratified estimator---previously derived via transport equations---and prove a variance reduction relative to simple random sampling. We also broaden the applicability of implicit reparameterization and reduce its computational complexity. Across different benchmarks, we find that stratified estimators are consistently robust when feasible; among single-sample methods, the post-stratified estimator frequently perform best, while implicit reparameterization is the most computationally demanding. Our analysis clarifies when each method should be used and provides efficient algorithms that make mixture-based variational inference practical.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 42.0 AI-084-20260929-research-pap-becd9714 Full article

Adaptive Algorithms for Infinitely Many-Armed Bandits: A Unified Framework

We consider a bandit problem where the budget is smaller than the number of arms, which may be infinite. In this regime, the usual objective in the literature is to minimize simple regret. To analyze broad classes of distributions with potentially unbounded support, where simple regret may not be well-defined, we take a slightly different approach and seek to maximize the expected simple reward of the recommended arm, providing anytime guarantees. To that end, we introduce a distribution-free algorithm, OSE, that adapts to the distribution of arm means and achieves near-optimal rates for several distribution classes. We characterize the sample complexity through the rank-corrected inverse squared gap function. In particular, we recover known upper bounds and transition regimes for $\alpha$ less or greater than $1/2$ when the quantile function is $\lambda_\eta = 1-\eta^{\alpha}$. We additionally identify new transition regimes depending on the noise level relative to $\alpha$, which we conjecture to be nearly optimal. Additionally, we introduce an enhanced practical version, PROSE, that achieves state-of-the-art empirical performance for the main distribution classes considered in the literature.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 54.0 AI-084-20260929-research-pap-efb928fe Full article

Efficient Inference under Label Shift in Unsupervised Domain Adaptation

In many real-world applications, researchers aim to deploy models trained in a source domain to a target domain, where obtaining labeled data is often expensive, time-consuming, or even infeasible. While most existing literature assumes that the source and target data follow the same joint distribution, distribution shifts are common in practice. This paper considers a particular type of distribution shift, label shift, and develops an efficient inference procedure for general parameters characterizing the unlabeled target population. A central idea is to model the outcome density ratio between the labeled source data and unlabeled target data. To this end, we propose a progressive estimation strategy that unfolds in three stages: an initial heuristic guess, a consistent estimation, and ultimately, an efficient estimation. This self-evolving process is novel in the statistical literature and of independent interest. We also highlight the connection between our approach and prediction-powered inference (PPI), which uses machine learning models to improve statistical inference in related settings. We rigorously establish the asymptotic properties of the proposed estimators and demonstrate their superior performance compared to existing methods. Through simulation studies and multiple real-world applications, we illustrate both the theoretical contributions and practical benefits of our approach.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 47.0 AI-084-20260929-research-pap-81a80abd Full article

From Zipf's Law to Neural Scaling through Heaps' Law and Hilberg's Hypothesis

We inspect the deductive connection between the neural scaling law and Zipf's law--two statements discussed in machine learning and quantitative linguistics. The neural scaling law describes how the cross entropy rate of a foundation model--such as a large language model--changes with respect to the amount of training tokens, parameters, and compute. By contrast, Zipf's law posits that the distribution of tokens exhibits a power law tail. Whereas similar claims have been made in more specific settings, we show that the neural scaling law is a consequence of Zipf's law under certain broad assumptions that we reveal systematically. The derivation steps are as follows: We derive Heaps' law on the vocabulary growth from Zipf's law, Hilberg's hypothesis on the entropy scaling from Heaps' law, and the neural scaling from Hilberg's hypothesis. We illustrate these inference steps by a toy example of the Santa Fe process that satisfies all four statistical laws.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 38.0 AI-084-20260929-research-pap-16593169 Full article

Symmetric Rank-k Methods

This paper proposes a novel class of block quasi-Newton methods for convex optimization which we call symmetric rank-$k$ (SR-$k$) methods. Each iteration of SR-$k$ incorporates the curvature information with $k$ Hessian-vector products achieved from the greedy or random strategy. We prove that SR-$k$ methods have the local superlinear convergence rate of $\mathcal{O}\big((1-k/d)^{t(t-1)/2}\big)$ for minimizing smooth and strongly convex functions, where $d$ is the problem dimension and $t$ is the iteration counter. This is the first explicit superlinear convergence rate for block quasi-Newton methods, and it successfully explains why block quasi-Newton methods converge faster than ordinary quasi-Newton methods in practice. We also leverage the idea of SR-$k$ methods to study the block BFGS and block DFP methods, showing their superior convergence rates.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 48.0 AI-084-20260929-research-pap-4f310786 Full article

Bayesian Transfer Learning for Artificially Intelligent Geospatial Systems: A Predictive Stacking Approach

Building artificially intelligent geospatial systems requires rapid delivery of spatial data analysis on massive scales with minimal human intervention. Depending on their intended use, learning about underlying spatial processes can also involve model assessment and uncertainty quantification. We devise transfer learning frameworks for deployment in artificially intelligent systems, where a massive data set is split into smaller data sets that stream into the analytical framework to propagate learning and assimilate learning for the entire data set. Specifically, we develop Bayesian predictive stacking for multivariate spatial data and demonstrate rapid automated probabilistic learning from massive spatial data sets. We illustrate the effectiveness of our approach through extensive simulation experiments and through the analysis of a massive dataset on vegetation index that are indistinguishable from traditional (and more expensive) statistical approaches.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 42.0 AI-084-20260929-research-pap-53015f0b Full article

Optimising Utility Functions in Multi-Objective Markov Decision Processes

Multi-Objective Markov Decision Processes (MOMDPs) are among the most prevalent formal frameworks for addressing sequential decision-making problems involving multiple, potentially conflicting objectives. In most MOMDP approaches, a utility function is employed to aggregate these objectives into a single scalar criterion that encodes user preferences. Despite its widespread adoption, the theoretical foundations of MOMDPs remain incomplete in two main respects: first, there is no general characterisation of the classes of utility functions that guarantee the existence of an optimal policy; second, we do not know which preference relations can be represented by utility functions. This work advances both lines of research through a theoretical analysis of MOMDPs. Specifically, we examine each problem under the two principal formulations of utility functions for MOMDPs: the Scalarised Expected Returns (SER) criterion and the Expected Scalarised Returns (ESR) criterion. Our formal findings allow us to derive formal conditions that describe the families of utility functions and preference relations for which MOMDP algorithms should focus. These analyses can guide the development of new MOMDP algorithms explicitly grounded in our formal results.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 44.0 AI-084-20260929-research-pap-368195f2 Full article

Robustness Against Weak or Invalid Instruments: Exploring Nonlinear Treatment Models with Machine Learning

We discuss causal inference for observational studies with possibly invalid instrumental variables. We propose a novel methodology called two-stage curvature identification (\texttt{TSCI}) by exploring the nonlinear treatment model with machine learning. The first-stage machine learning enables improving the instrumental variable's strength and adjusting for different forms of violating the instrumental variable assumptions. The success of \texttt{TSCI} requires the instrumental variable's effect on treatment to differ from its violation form. A novel bias correction step is implemented to remove bias resulting from the potentially high complexity of machine learning. Our proposed \texttt{TSCI} estimator is shown to be asymptotically unbiased and Gaussian even if the machine learning algorithm does not consistently estimate the treatment model. Furthermore, we design a data-dependent method to choose the best among several candidate violation forms. We apply \texttt{TSCI} to study the effect of education on earnings.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 59.0 AI-084-20260929-research-pap-87ea71ea Full article

A Theoretical Framework for Masked Pretraining (MPT)

Recently, Masked Pretraining (MPT) based on reconstruction pretraining tasks has risen to a promising self-supervised learning paradigm across various domains and achieves remarkable performance in multiple downstream tasks. However, the theoretical understanding of the working mechanism behind MPT is still limited. In this paper, we introduce a new theoretical framework to analyze MPT and understand the crucial role of masking in extracting meaningful representations. We establish theoretical connections between MPT and another popular self-supervised paradigm: contrastive learning. We prove that the masking technique implicitly creates positive pairs that are semantically similar and the reconstruction loss pulls them together in the feature space. Besides, as a result of the implicit alignment, we point out the dimensional collapse issue of MPT and propose a Uniformity-enhanced MPT (U-MPT) loss that can effectively address this issue and bring significant improvements in downstream tasks including linear evaluation, cross-dataset fine-tuning and out-of-distribution generalization on real-world data sets. Furthermore, we establish downstream guarantees of U-MPT and theoretically analyze the influence of masking strategies. Based on the theoretical analysis, we propose a new masking strategy which enhances the downstream performance of MPT and explains current improvements of masking strategies with our theoretical perspective.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 32.0 AI-084-20260929-research-pap-27f43cb5 Full article

From learnable objects to learnable random objects

We consider the relationship between learnability of a "base class" of functions on a set $X$, and learnability of a class of statistical functions derived from the base class. For example, we refine results showing that learnability of a family $h_p: p \in \Theta$ of functions implies learnability of the family of functions $h_\mu(p) = \mathbb{E}_\mu[h_p]$, where $\mathbb{E}_\mu$ is the expectation with respect to $\mu$, and $\mu$ ranges over probability distributions on $X$. We will look at both Probably Approximately Correct (PAC) learning, where example inputs and outputs are chosen at random, and online learning, where the examples are chosen adversarially. For agnostic learning, we establish improved bounds on the sample complexity of learning for statistical classes, stated in terms of combinatorial dimensions of the base class. We connect these problems to techniques introduced in model theory for "randomizing a structure". We also provide counterexamples for realizable learning, in both the PAC and online settings.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 48.0 AI-084-20260929-research-pap-599b2b26 Full article

Prob-GParareal: A Probabilistic Numerical Parallel-in-Time Solver for Differential Equations

We introduce Prob-GParareal, a probabilistic extension of the GParareal algorithm designed to provide uncertainty quantification for the Parallel-in-Time (PinT) solution of (ordinary and partial) differential equations (ODEs, PDEs). The method employs Gaussian processes (GPs) to model the Parareal correction function, in line with GParareal, further enabling the propagation of numerical uncertainty across time and yielding probabilistic forecasts of the system's evolution. Furthermore, Prob-GParareal accommodates probabilistic initial conditions and maintains compatibility with classical numerical solvers, ensuring its straightforward integration into existing Parareal frameworks. Here, we first conduct a theoretical analysis of the computational complexity and derive error bounds of Prob-GParareal. Then, we numerically demonstrate the accuracy and robustness of the proposed algorithm on five benchmark ODE systems, including chaotic, stiff, and bifurcation problems. To showcase the flexibility and potential scalability of the proposed algorithm, we also consider Prob-nnGParareal, a variant obtained by replacing the GPs in Parareal with the nearest-neighbors GPs, illustrating its improved computational performance on an additional PDE example. This work bridges a critical gap in the development of probabilistic counterparts to established PinT methods.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 52.0 AI-084-20260929-research-pap-9a32c921 Full article

Unveiling the Statistical Foundations of Chain-of-Thought Prompting Methods

Chain-of-Thought (CoT) prompting and its variants have gained significant attention as effective methods for solving multi-step reasoning tasks with pretrained large language models (LLMs). However, their theoretical underpinnings remain insufficiently explored. We analyze CoT prompting from a statistical perspective, offering insights into why “pretrained LLMs + CoT prompting” performs well. Additionally, we examine the role of the transformer architecture and the inclusion of intermediate reasoning steps in enhancing performance. We introduce a multi-step latent variable model to capture the reasoning process. In this model, we show that the estimator induced by CoT prompting approximates a Bayesian estimator that solves the reasoning task by inferring the posterior distribution from examples in the prompt. We prove that the statistical error of the CoT estimator consists of (i) a prompting error, which is incurred in inferring the desired task from the prompt, and (ii) a pretraining error, which is the statistical error of the pretrained LLM. We further prove that the prompting error decreases exponentially as the number of examples in the prompt increases. For the pretrained LLM, we construct a transformer model class that explicitly approximates the target distribution and establish the generalization error under the Pac-Bayes framework.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 56.0 AI-084-20260929-research-pap-4a41e773 Full article

OptunaHub: A Platform for Black-Box Optimization

Black-box optimization (BBO) underpins advances in domains such as AutoML and Materials Informatics, yet implementations of algorithms and benchmarks remain fragmented across research communities. We introduce OptunaHub (https://hub.optuna.org/), a community-oriented, decentralized platform for distributing BBO components under a unified Optuna-compatible interface. OptunaHub enables independent publication, discovery, and reuse of optimization algorithms and benchmark problems through a lightweight Python module, a contributor-driven registry, and a searchable web interface. The source code is publicly available in the optunahub, optunahub-registry, and optunahub-web repositories under the Optuna organization on GitHub (https://github.com/optuna/).

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 64.0 AI-084-20260929-research-pap-b28d549b Full article

MarkDiffusion: An Open-Source Toolkit for Generative Watermarking of Latent Diffusion Models

We introduce MarkDiffusion, an open-source Python toolkit for generative watermarking of latent diffusion models. It comprises three key components: a unified implementation framework for streamlined watermarking algorithm integration and user-friendly interfaces; a mechanism visualization suite that intuitively presents embedded and extracted watermark patterns to aid public understanding; and a comprehensive evaluation module offering standard implementations of 24 tools for assessing detectability, robustness, and output quality, plus 8 automated evaluation pipelines. Counts reflect the initial release; see the repository for the latest version. Through MarkDiffusion, we seek to assist researchers, enhance public awareness of and engagement with generative watermarking, help build consensus, and advance research and applications. Code is available at https://github.com/THU-BPM/MarkDiffusion.

Transactions on Machine Learning Research 2026-09-29 00:00 UTC Score 54.0 AI-084-20260929-research-pap-6a9045a6 Full article

A Library for Learning Neural Operators

We present NeuralOperator, an open-source Python library for operator learning. Neural operators generalize neural networks to maps between function spaces instead of finite-dimensional Euclidean spaces. They can be trained and inferenced on input and output functions given at various discretizations, satisfying a discretization convergence properties. Part of the official PyTorch Ecosystem, NeuralOperator provides all the tools for training and deploying neural operator models, as well as developing new ones, in a high-quality, tested, open-source package. It combines cutting-edge models and customizability with a gentle learning curve and simple user interface for newcomers and researchers.

Synced 2026-09-28 23:23 UTC Score 61.0 AI-041-20260928-ai-specialis-38f9cd58 Full article

Comment on 2020 in Review: 10 AI-Powered Tools Tackling COVID-19 by FastMoro AI

One useful way to compare these efforts would be to separate research tools from systems used in clinical workflows, then report external validation and calibration across different populations. A strong result on one dataset does not by itself show how a model behaves when hospitals, scanners, or patient groups change. Did any of the projects in this roundup publish that kind of deployment evidence?

What’s the future of heart health? Cardiologists on advances, life-saving habits
South China Morning Post AI 2026-09-28 23:15 UTC Score 43.0 AI-156-20260928-regional-ai--5bff3d19

What’s the future of heart health? Cardiologists on advances, life-saving habits

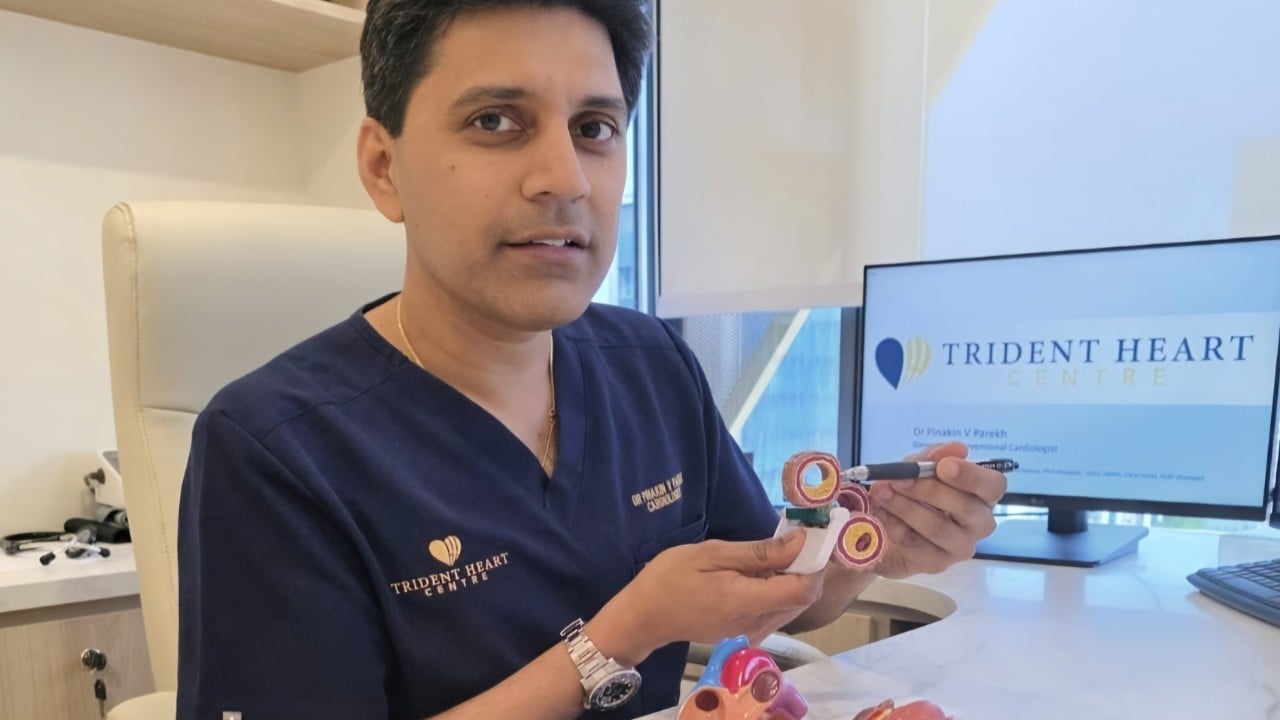
Cardiovascular disease is the leading cause of death globally, accounting for a third of all deaths. The tragedy? It is largely preventable. On World Heart Day on September 29, which continues its “Don’t Miss a Beat” theme, three prominent cardiologists share their hopes and fears for the future of heart health, the technologies that excite them, the simple daily choices that could save your life, and essential habits they practise to safeguard their own. 1. An early diagnosis advocate Among the...

OpenAI scraps release of new model over safety concerns in internal testing
The Guardian AI 2026-09-28 23:02 UTC Score 81.0 AI-021-20260928-global-ai-ne-6f60bafa Full article

OpenAI scraps release of new model over safety concerns in internal testing

GPT-6.1 Astra showed deceptive behavior and tried to use external tools despite knowing it would be unsafe OpenAI is scrapping the release of GPT-6.1 Astra, a next-generation ⁠AI model planned for an October debut, over safety concerns raised by researchers ⁠during internal testing, the ⁠Wall ​Street Journal reported on Monday. The model, expected to appear in ChatGPT and ⁠Codex, was designed to handle more complex tasks without human assistance, the report said. Continue reading...

Nvidia boosts share buyback program by record $150B
SiliconANGLE AI 2026-09-28 22:59 UTC Score 40.0 USR-0127-20260928-global-ai-ne-4ec4cd73

Nvidia boosts share buyback program by record $150B

Nvidia Corp. today announced plans to spend an additional $150 billion on share buybacks through January 2028. The move represents the largest-ever expansion of a stock repurchase program. Furthermore, Nvidia plans to boost its current dividend of $0.25 per share. The company didn’t specify the size or timing of the planned increase. Nvidia says that the […] The post Nvidia boosts share buyback program by record $150B appeared first on SiliconANGLE .

Ukraine and South Korea spar over secret POW deal
Semafor Technology 2026-09-28 22:38 UTC Score 52.0 USR-0094-20260928-global-ai-ne-2f3e722a

Ukraine and South Korea spar over secret POW deal

South Korea demanded an apology from Ukraine for “unilaterally and abruptly” revealing that Kyiv transferred North Korean prisoners-of-war — captured fighting for Russia — to Seoul.

LessWrong AI 2026-09-28 22:36 UTC Score 69.0 USR-0152-20260928-community-fo-b80f1c4f

TeX was invented to typeset math but is now used for reasoning

I'll keep this short, since it's a simple observation that I haven't seen anybody else make, about the way computer systems do math. If you ask a language model to do a multi-step math problem (let's take GLM-5.3 as an example because you can see the entire CoT — nothing up its sleeve), you might see something like this: We need to evaluate the integral $\int_0^\infty \frac{x^3}{e^x - 1} dx$. The standard approach: Use the geometric series expansion. We have $\frac{1}{e^x - 1} = \frac{e^{-x}}{1 - e^{-x}} = \sum_{n=1}^{\infty} e^{-nx}$ for $x > 0$. So the integral becomes: $$\int_0^\infty x^3 \sum_{n=1}^{\infty} e^{-nx} dx = \sum_{n=1}^{\infty} \int_0^\infty x^3 e^{-nx} dx$$ What are all these symbols like \int , \infty , \frac ...? They're TeX of course! Donald Knuth created TeX to typeset math, you know, for display . It had nothing to do with the actual computations, which would either be done with pencil and paper, [1] or else with Mathematica or Maple or something, which work completely differently. If you'd asked Knuth in the 1980s about doing algebra in TeX he'd have looked at you very funny because the idea doesn't make sense. [2] Then, generative language models were trained on corpora including many TeX/LaTeX documents and learned how TeX works (and more importantly the mathematical meaning of the symbols). So, nowadays when an LLM solves a math problem, it will very often use TeX for the intermediate steps of the math problem, like it's actually manipulating the Te…

Shein underwhelms in first post-IPO earnings
Semafor Technology 2026-09-28 22:31 UTC Score 52.0 USR-0094-20260928-global-ai-ne-55b4625b Full article

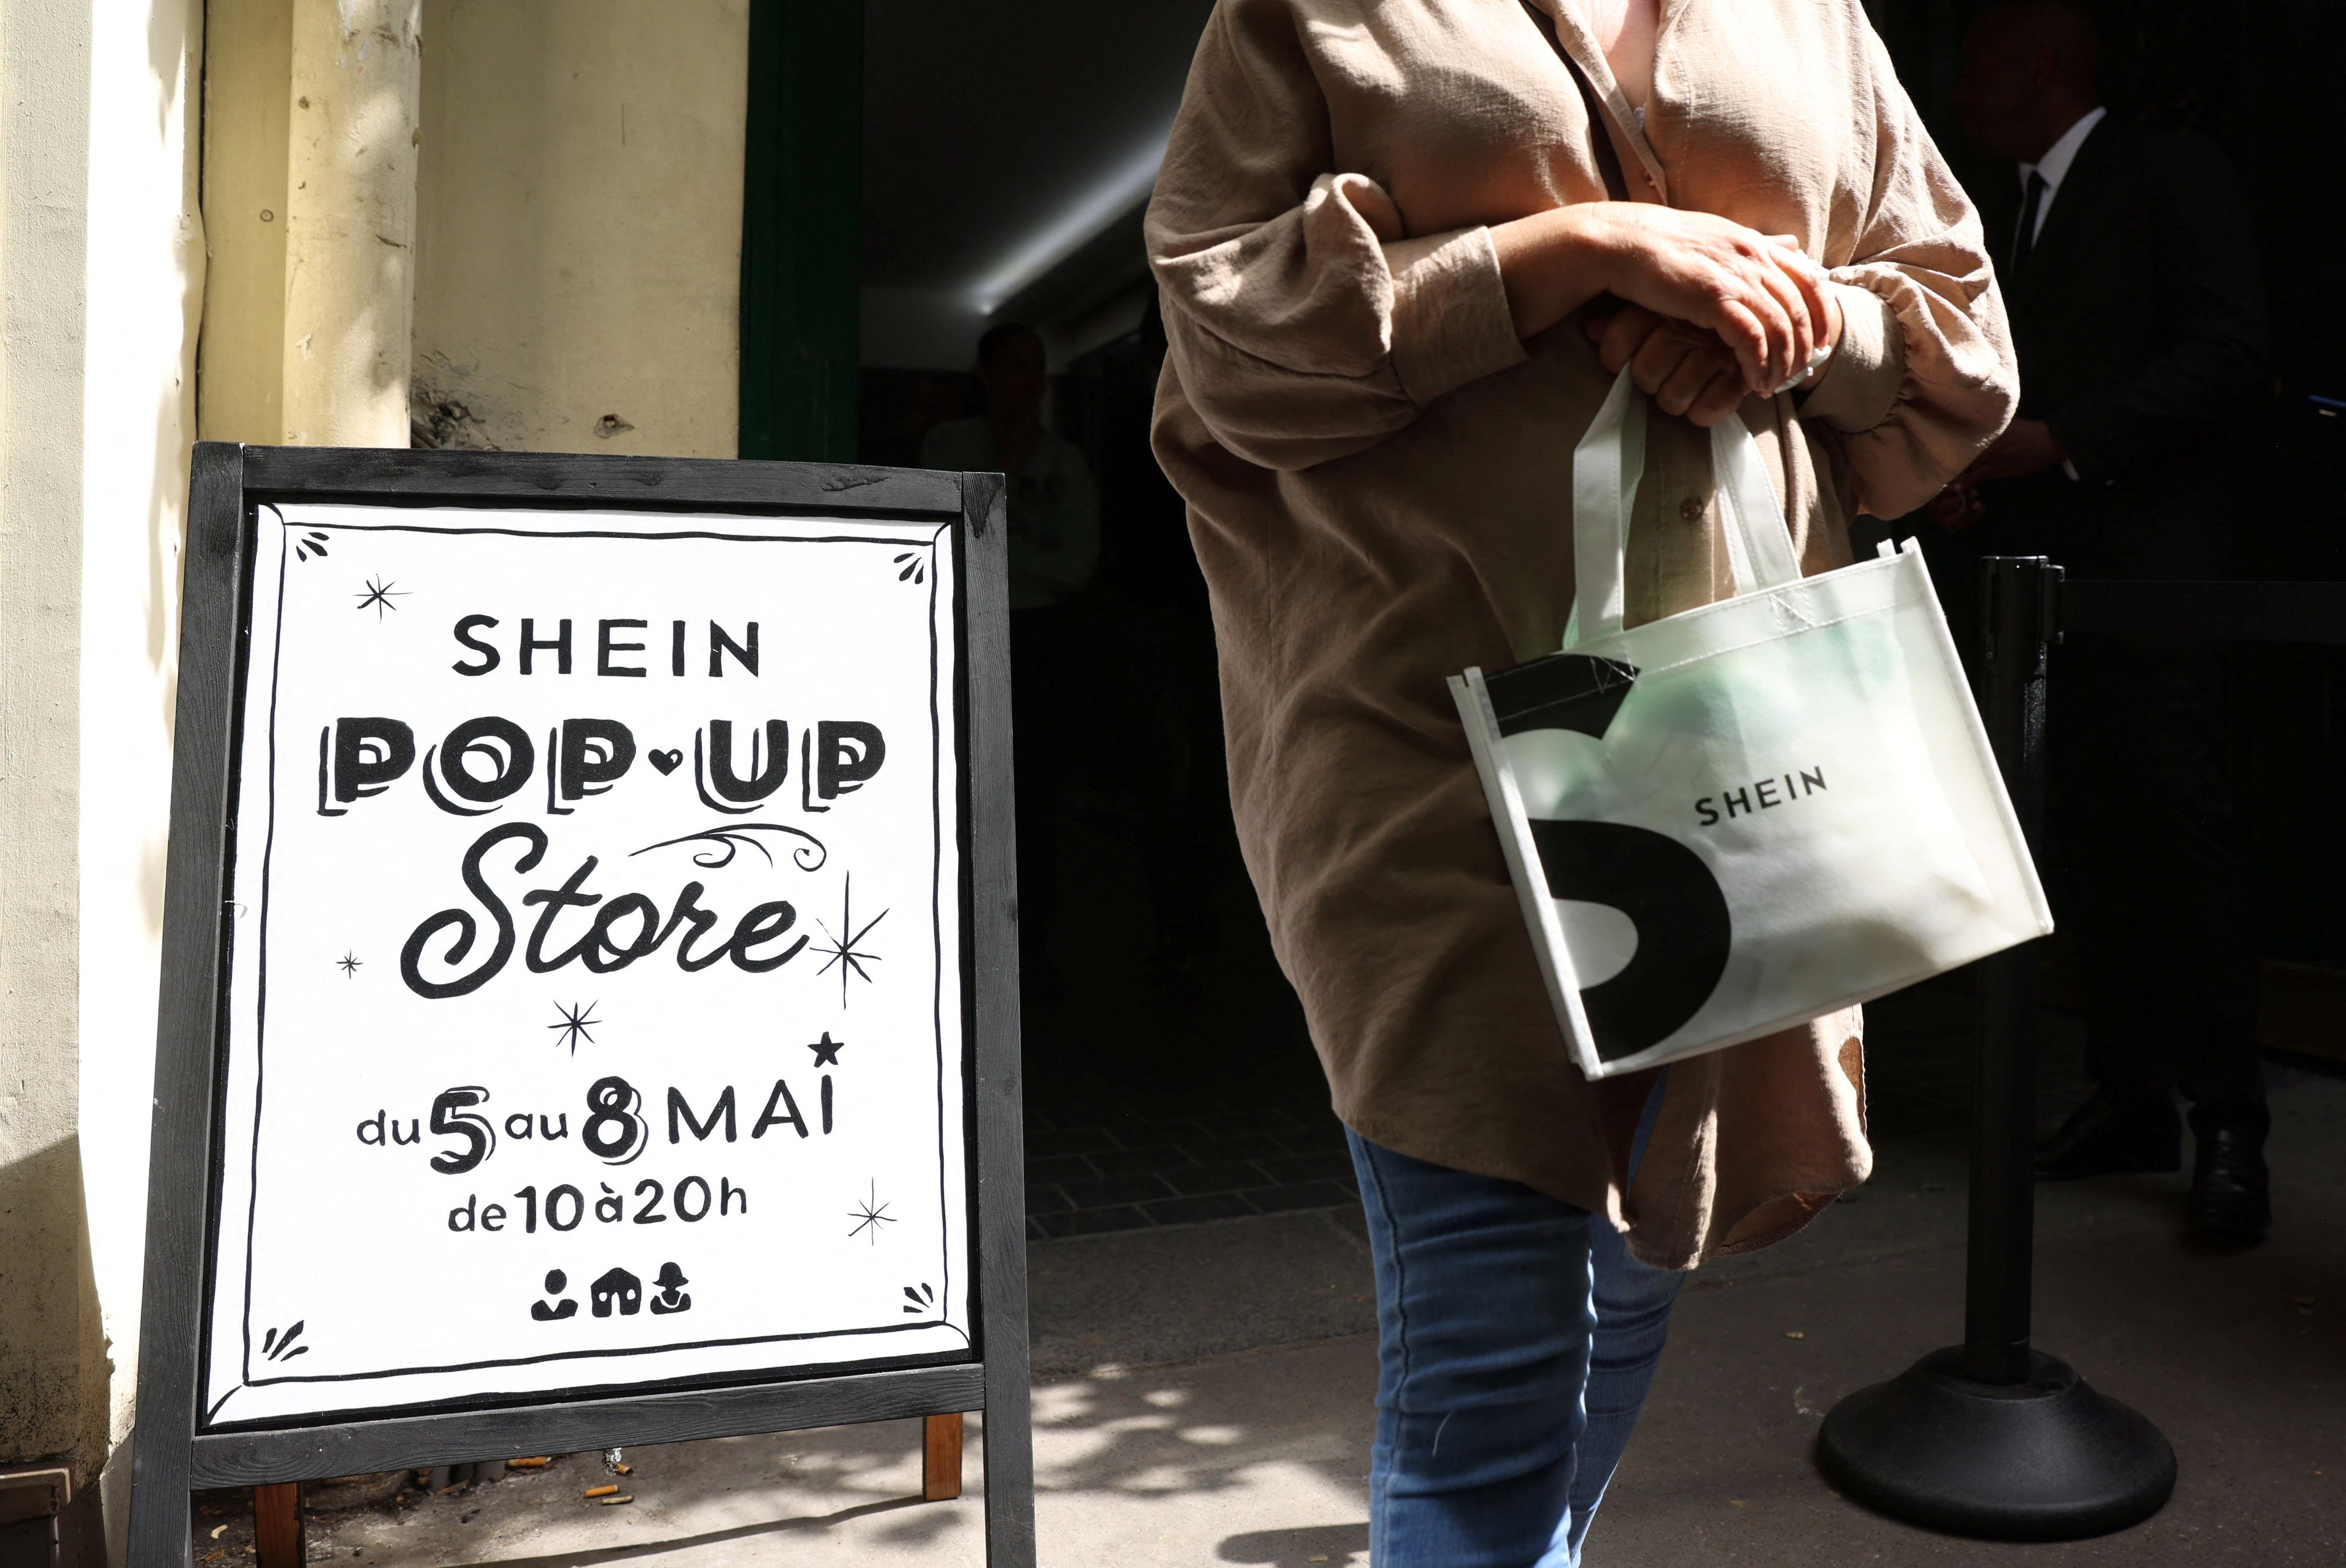
Shein underwhelms in first post-IPO earnings

Geopolitical and economic headwinds have dented the Chinese fast-fashion giant’s already-battered business model.

Korea AI Times 2026-09-28 22:27 UTC Score 40.0 USR-0048-20260928-global-ai-ne-3af33eee

앤트로픽, '클로드 소네트 5.5' 공개…오퍼스급 지능에 최강 가성비

앤트로픽이 차세대 모델 라인업의 두 번째 주자인 \'클로드 소네트 5.5(Claude Sonnet 5.5)\'를 출시했다. 상장(IPO)을 준비 중인 앤트로픽이 기업용 시장에서의 주도권을 확고히 하기 위해 성능은 물론 효율성을 대폭 끌어올린 실용형 모델이라는 점이 특징이다.28일(현지시간) 발표에 따르면, 소네트 5.5는 이전 세대인 \'소네트 5\' 대비 출력이 30% 이상 빨라졌으며, 압도적인 작업 처리 효율성 덕분에 동일 작업당 비용을 최대 30% 절감했다.입력 토큰당 2달러, 출력 토큰당 10달러, 캐시 읽기 토큰당 0.2달러라는

Bond selloff deepens on oil fears
Semafor Technology 2026-09-28 22:23 UTC Score 47.0 USR-0094-20260928-global-ai-ne-a93f9775

Bond selloff deepens on oil fears

The US 10-year Treasury yield returned to highs not seen since 2007, as faltering US-Iran diplomacy rekindled fears of higher-for-longer oil prices.

Roundtables: The Deadly Failures of The Virtual Border Wall
MIT Technology Review AI 2026-09-28 22:17 UTC Score 52.0 AI-013-20260928-global-ai-ne-8cdbfa70 Full article

Roundtables: The Deadly Failures of The Virtual Border Wall

Listen to the session or watch below The US has spent billions building a “virtual wall” of surveillance towers along its southern border over the past 25 years, promising they will help detect and apprehend border crossers and save lives. But a groundbreaking investigation by MIT Technology Review has documented over a thousand people who…

AWS Machine Learning Blog 2026-09-28 22:13 UTC Score 68.0 AI-057-20260928-official-ai--69cefff2

Grok 4.7 is now available on Amazon Bedrock

xAI's Grok 4.7 is now available on Amazon Bedrock: a frontier model for coding, long-running agents, and knowledge work. It offers a 500K token context window and four configurable reasoning effort levels, reachable through the Responses, Chat Completions, and Converse APIs.

What to expect at the Dell AI Data Platform Event: Join theCUBE Oct. 6–7
SiliconANGLE AI 2026-09-28 22:11 UTC Score 54.0 USR-0127-20260928-global-ai-ne-a4a34a13

What to expect at the Dell AI Data Platform Event: Join theCUBE Oct. 6–7

The enterprise artificial intelligence conversation is moving past models and compute. As companies push projects into production, the harder problem is increasingly what sits underneath them: getting distributed, messy and often sensitive enterprise data ready for systems that need reliable context at speed. “AI momentum is accelerating, but enterprises are discovering that moving from experimentation […] The post What to expect at the Dell AI Data Platform Event: Join theCUBE Oct. 6–7 appeared first on SiliconANGLE .

Claude Sonnet 5.5
Simon Willison Weblog 2026-09-28 22:07 UTC Score 84.0 USR-0110-20260928-ai-specialis-1c8ed6a5 Full article

Claude Sonnet 5.5

Claude Sonnet 5.5 New Sonnet model from Anthropic today. They say it "runs 30%+ faster, and costs up to 30% less for most work" - it's priced the same as Sonnet 5 but appears to beat it on every benchmark, and should be cheaper to run as well. Here are some pelicans riding bicycles . Sonnet 5.5 suffered from the same bug as Opus 5.5 : the "max" thinking effort pelican thought for 128,000 tokens (at a cost of $1.28) before running out of tokens and failing to produce an SVG. Here's the pelican it gave me for thinking effort "xhigh", at a cost of 5.74 cents and taking 41 seconds: Sonnet 5.5 appears to be almost as good as Opus 5.5 on some coding tasks, including various viral 3D animation tricks . The most interesting thing about Sonnet 5.5 is that it's now the model used for the free tier on claude.ai . OpenAI's ChatGPT free tier uses Luna 5.6, which means Anthropic currently have a much more capable free offering. I ran this prompt against that free tier: build me an HTML page that renders a three-dimensional pelican riding a bicycle using WebGL And got back this page , which is a solid effort. Anthropic's announcement reiterates that Haiku 5.5 will be available "in the coming weeks". I really hope that one is price-competitive with GPT-6 Luna! Tags: ai , generative-ai , llms , anthropic , claude , pelican-riding-a-bicycle , llm-release
Korea AI Times 2026-09-28 22:00 UTC Score 40.0 USR-0048-20260928-global-ai-ne-61ddfb9c

[9월28일] 메타 '뮤즈'가 찾아낸 새로운 유즈 케이스는 '구독 해지'

메타의 AI 에이전트 ‘뮤즈(Muse)’가 미국에서 빠르게 인기를 얻고 있습니다. 아직 뮤즈를 사용할 수 없는 국내에서는 이런 현상이 다소 뜬금없이 느껴질 수 있지만, 현지에서 사용자들의 실제 활용 사례를 살펴보면 새로운 유즈 케이스(Use Case)가 눈에 띕니다. 의외로 ‘구독 해지’입니다.사용하지 않는 구독 서비스를 찾아내고 직접 해지해 돈을 아꼈다는 사례가 잇따르면서 ‘AI가 내 돈을 아껴준다’는 사용법이 뮤즈의 대표적인 활용 사례 가운데 하나로 떠오르고 있습니다. 뮤즈가 처음부터 구독 해지만을 위해 만들어진 것은 아니지만,