LessWrong AI
2026-11-05 07:03 UTC
Score 68.0
USR-0152-20261105-community-fo-11f0ec1d
Full article
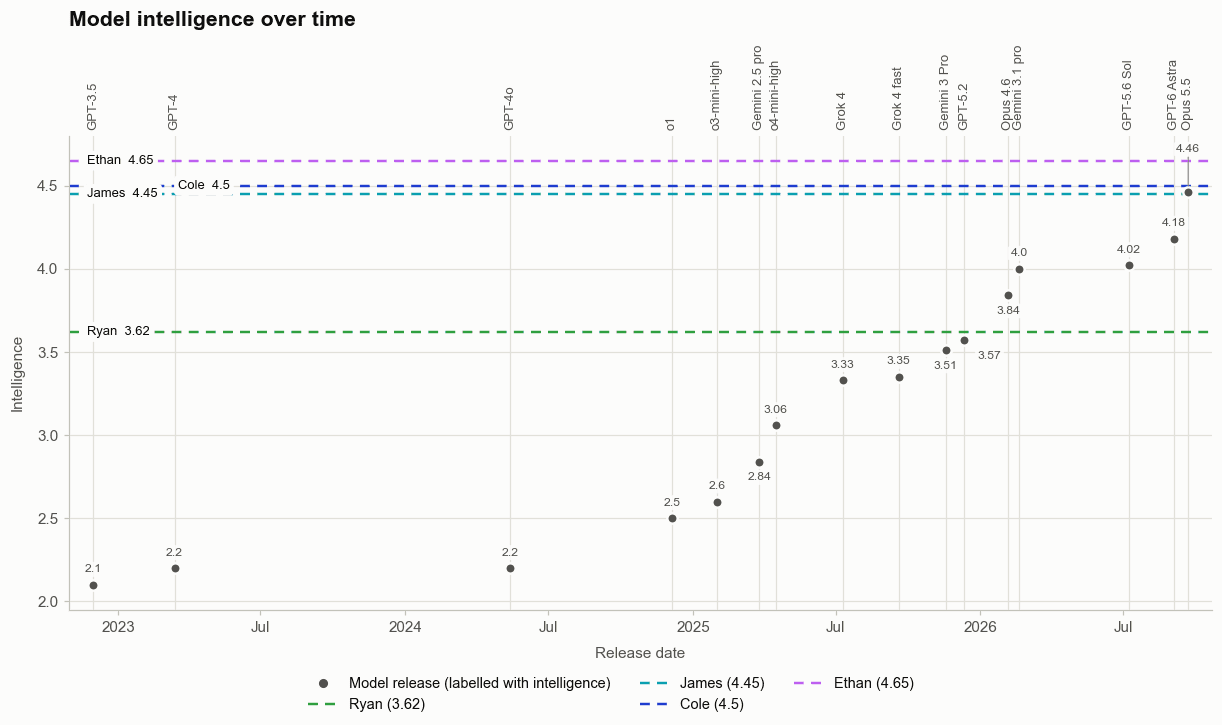
LLM Intelligence, measured by Starburst, has been basically linear over time since that start of the reasoning era. By Chapin Lenthall-Cleary and Cole Gaboriault In summer 2024, my friend Cole and I started a hobby research program into perceptions of (human) intelligence. We started by creating a bespoke 1-5 intelligence scale [1] and rating people we knew. Our plan was to then make a bunch of tests, give them to the people we rated, and see which tests, if any, correlated with our ratings. One of those tests was Starburst. We’ve talked about it before ; in short, it’s a puzzle game where one tries to figure out the laws of physics of a fictional universe. We never did get very many people to play it. But using the results of two early playthroughs (Cole’s and our friend Ryan’s), some further test playthroughs where we pretended to be people of certain intelligences, some a priori reasoning about which parts of the game would be difficult, and a healthy dose of raw intuition, we pieced together a correspondence between Starburst scores and our intelligence scale. Then Ryan suggested we give Starburst to LLMs. Here's a plot of SOTA [2] model intelligence over time, measured using those Starburst correspondences, along with all four (emphatically not population-representative) human scores for reference (please reach out if you want to play and get us more data): There's a lot notable here, including the general observations that progress has been rapid, but LLM performance s…