
Wandrd’s Magnetic Camera Straps Are My New Favorite Accessory
More evidence that magnets are magical.
AI/ML news, top picks, and generated innovation digests.
90413 matching items
More evidence that magnets are magical.
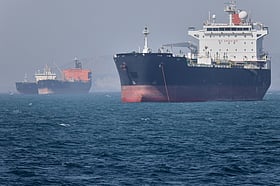
Iran says two tankers caught fire in Hormuz after hitting mines
Egypt fire World Cup coach Hassan over personal issues
Student-loan borrowers face stalled debt relief, inaccurate bills, and repayment glitches. The blue wave in the midterms could take on those issues.

Ukrainian President Volodymyr Zelenskyy called for further sanctions on Russia ahead of talks in Abu Dhabi.
In August, researchers at a California security firm used an OpenAI model to find a software bug in PHP, a programming language that undergird some seventy per cent of the world’s websites, including Wikipedia and WordPress.
Catch up with the most important stories from around Europe and beyond this November 8th, 2026 - latest news, breaking news, World, Business, Entertainment, Politics, Culture, Travel.

The next time you take paid time off, your boss and coworkers will remember if you follow this advice.
From mahjong to wine tasting, Wall Street's rising stars reveal how they're using hobbies to network, unwind, and make time for themselves.
Talon Krebs earns six figures as a TikTok Shop affiliate. He shares how strong video hooks can turn views into sales.
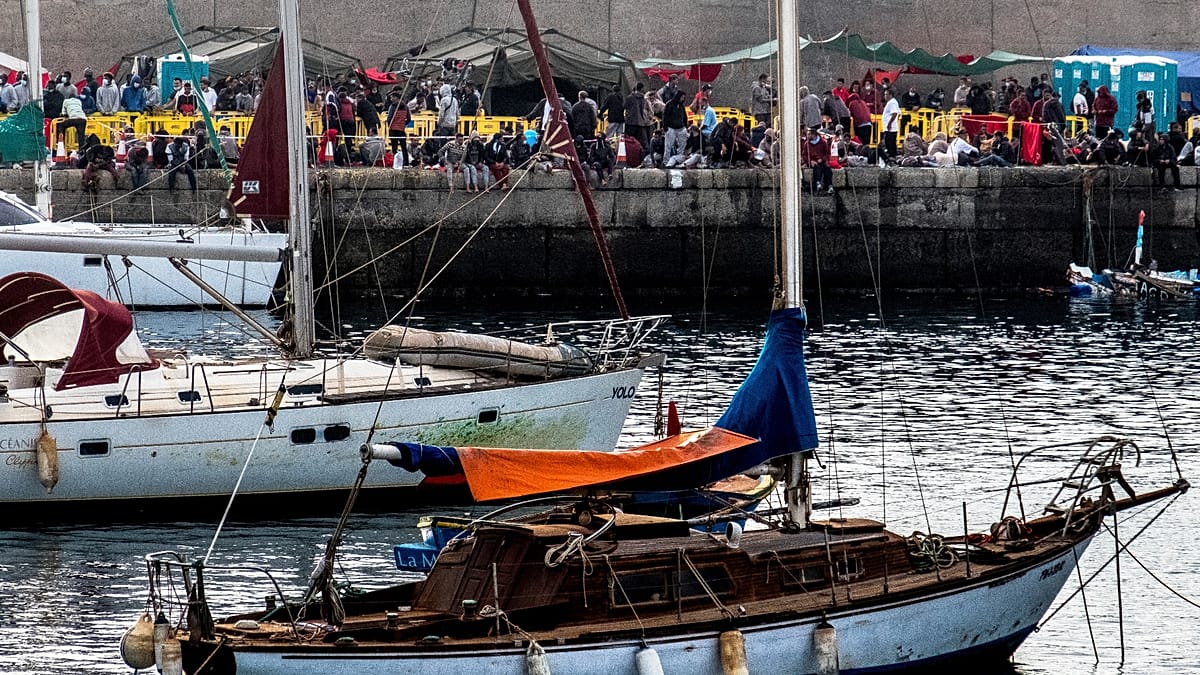
Between 1 and 6 November, 49 boats carrying a total of 4,587 migrants arrived in the Canary Islands, according to the regional government.
Companies like Uber and Instacart often deactivate gig workers' accounts with little notice. Some workers are turning to AI to fight back.

A group of young mathematicians found the solution to the long unanswered conjecture, first inspired by juggling, through randomness and friendship.
David Yanacek, a senior principal engineer at AWS, says these qualities can make you especially good at overseeing agents.
Professional nanny Samantha Jordan explains why she refuses private jet travel and sets travel safety boundaries with her wealthy clients.
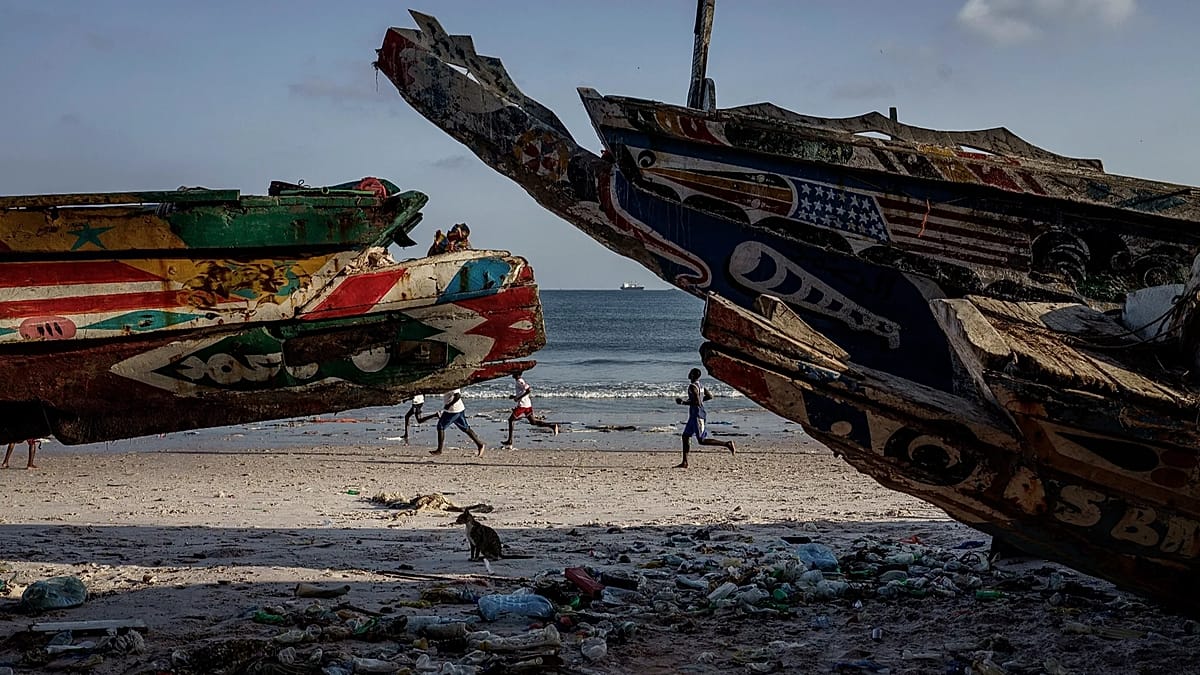
The United Nations' International Organization for Migration (IOM) says the dangerous Atlantic Route is a key pathway for West African migrants travelling to Europe.
Peggy Johnson rose through Qualcomm, became Microsoft's chief dealmaker, and led Magic Leap. Now she's trying to turn humanoid robots into a business.
Retired Navy SEAL Jocko Willink said the focus on optimization distracts from actually improving. He shared two changes to his routine that worked.

3D printing, microcontrollers and drones have enabled the resurgence of antipersonnel mines in the Russia-Ukraine war, making mines deadlier and more accessible

Apple announced an updated 14-inch MacBook Pro with the latest M6 chip. But with the M5 model on sale, I’m not sure the M6 is worth the upgrade.

We braved the cold to answer a modern dilemma: Can you keep your hands warm and use a smartphone at the same time?

Moving AI from text to 3D space, world models simulate real-world physics to teach robots and autonomous cars how to navigate reality.
Alibaba's new coding-agent benchmark, Co-Design Bench, tests AI agents on real user requests that already tripped them up in practice. Even GPT-6 Astra, the top performer, fully solves only 26.4 percent of tasks. On older benchmarks, the same models score above 99 percent. The article AI coding agents still need human cleanup on nearly three out of four tasks in a real-world test appeared first on The Decoder .
Americans think life is too expensive. Democrats finally figured out how to talk about it — and they sound a lot like NYC Mayor Zohran Mamdani.

Eisenkot’s 67-seat backing masks Israel coalition woes
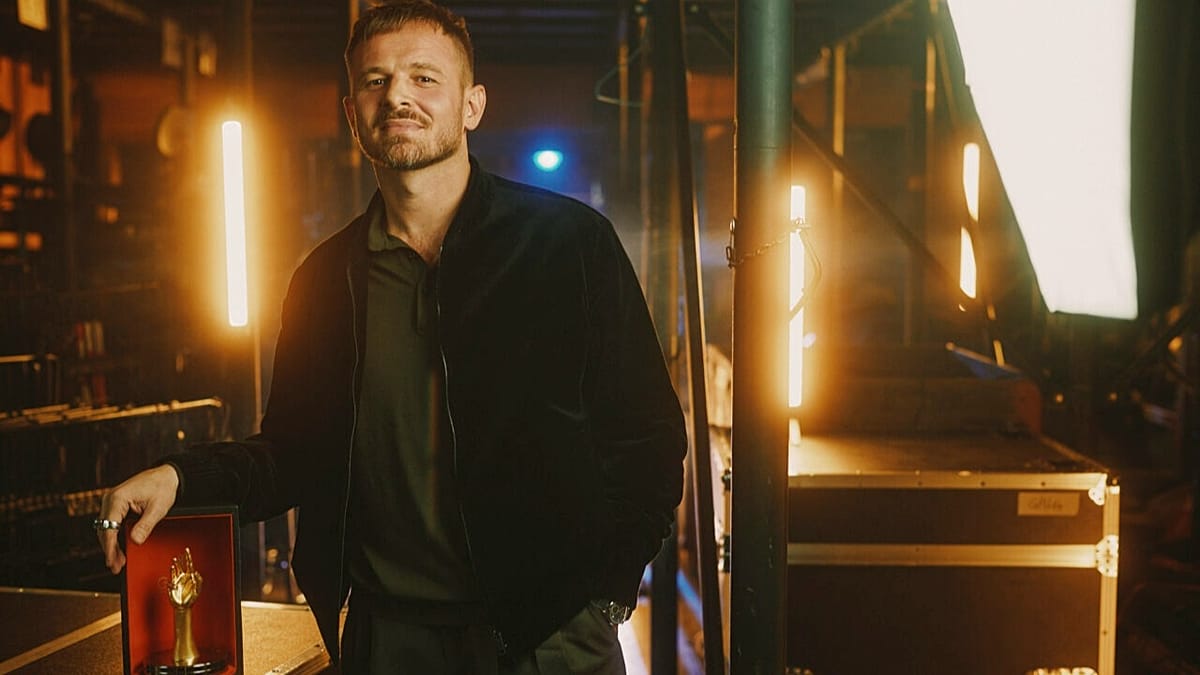
At this year's luxury watch awards, 84 timepieces and clocks were in competition across 14 categories, including sports, calendar and astronomy, jewellery and mechanical exception.

Eingeklemmt zwischen Kaliningrad und Belarus liegt die verwundbarste Stelle der NATO. Genau hier entsteht mit der Panzerbrigade 45 das wohl wichtigste Projekt der deutschen Zeitenwende. Bis 2027 sollen fast 5.000 deutsche Soldaten dauerhaft in Litauen stationiert werden. Doch die Bedrohung durch Russland ist längst nicht mehr nur theoretisch: Drohnen, Desinformation und brennende Infrastruktur zeigen, dass […]
과학 연구에서 AI 활용이 늘고 있지만, 새로운 아이디어나 가설을 만드는 작업보다 데이터 분석과 논문 작성에 집중되고 있다는 조사 결과가 나왔다. 연구자들은 가설 생성을 과학적 발견에서 가장 중요한 활동으로 꼽았지만, 실제 AI 사용 비중은 4% 수준에 그쳤다.앤트로픽은 5일(현지시간) 공식 블로그를 통해 \'과학적 발견을 위한 AI: 연구자들은 클로드를 어떻게 사용하는가\'라는 보고서를 공개했다.지난 8월2일부터 9월30일까지 \'클로드\'와 \'클로드 코드\'에서 이뤄진 과학 연구 관련 세션 20만7049건을 분석하고, 별도로 과학자 52
Erfahren Sie, wie Sie Ihre Entwicklungsaufgaben mit Claude Code autonom bearbeiten lassen und Ihre Workflows mit KI-Agenten spürbar beschleunigen können.
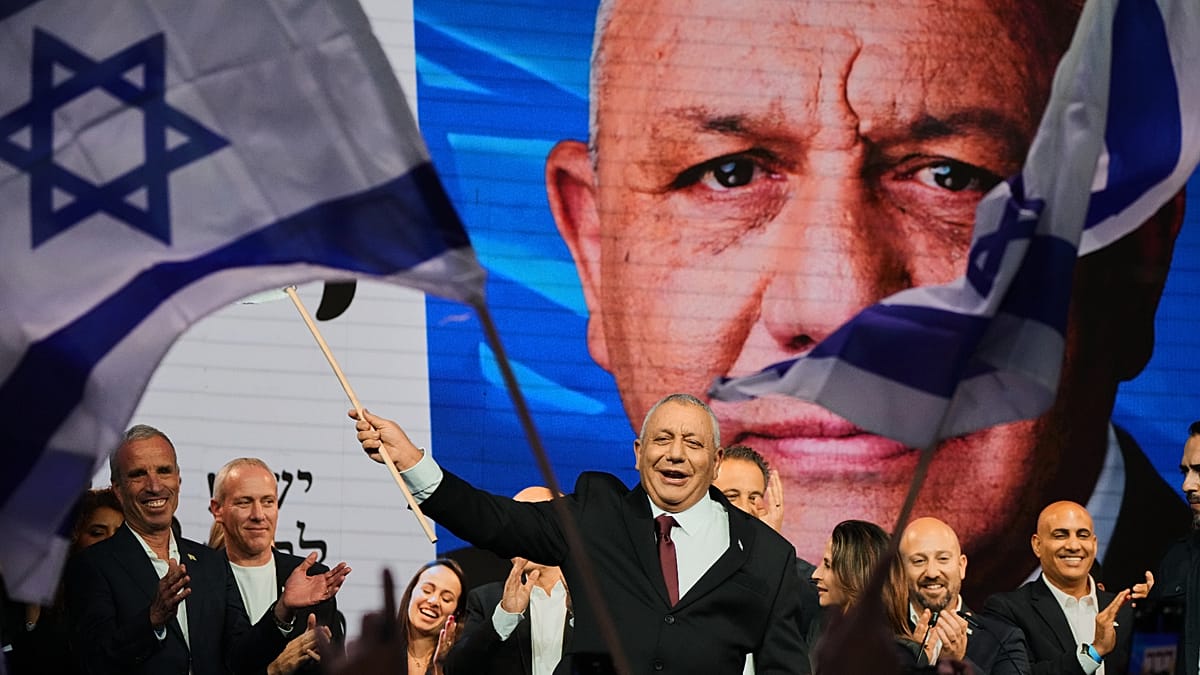
In Israel, a candidate tasked with forming a new government has 28 days to carry out the job. The president is able to extend this by a maximum of 14 days before giving the mandate to someone else.

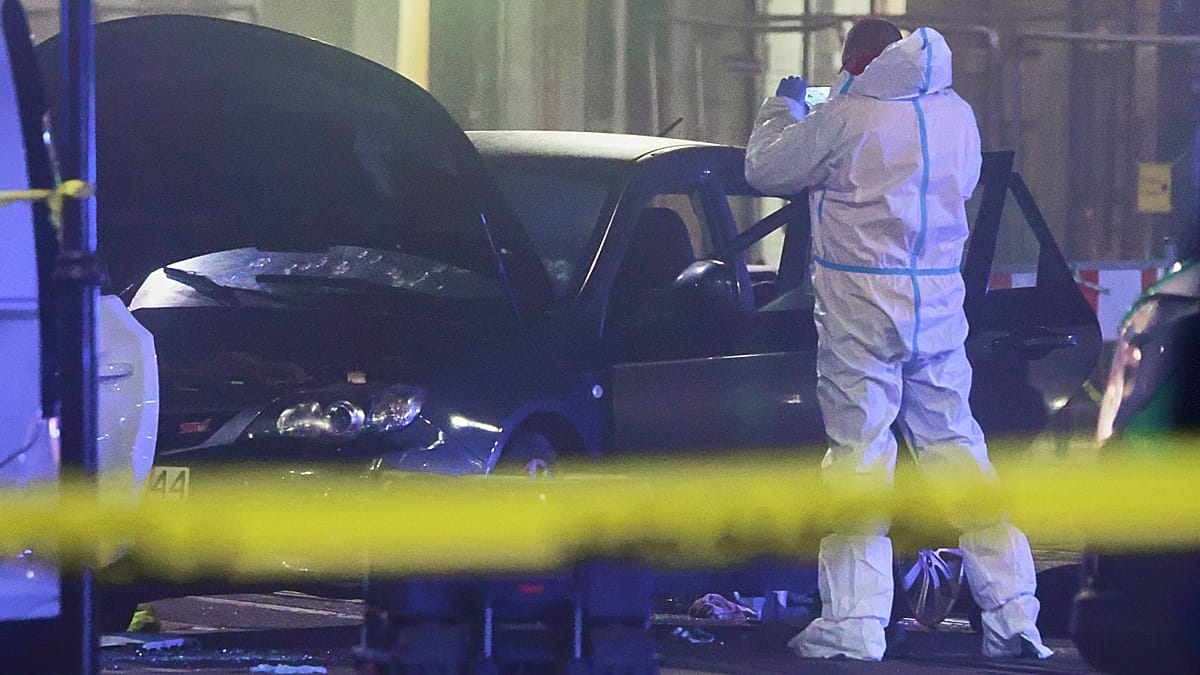
Police said the bodies of the suspect's 53-year-old father, 52-year-old mother and 21-year-old sister had also been found at his home.
The Norwegian capital is hosting the fifth edition of Fjord Oslo, an international festival showcasing outdoor light art. This year's edition brings together artists from several countries to explore the meaning of peace through installations across the city.
MPs, local authorities, lawyers, schools and more are receiving floods of grievances, requests and legal challenges, often complex to read and respond to ‘It started as a trickle in 2024 and now it’s an onslaught.” Hollie Wickens, a senior caseworker in a Labour MP’s office, is explaining the daily reality of dealing with surging volumes of artificial intelligence-generated correspondence. “Half the emails we receive are some form of AI,” she says, adding that this has made requests and complaints much more complex and time-consuming to read and deal with, despite her decade of experience in the role. “It is definitely more taxing.” Continue reading...
중국 앤트그룹이 이미지와 동영상을 이해하고 복잡한 작업을 수행하는 멀티모달 AI 모델 \'링 3.2 플래시(Ling-3.2-flash)\'를 출시했다. 앤트로픽의 \'클로드 오퍼스 5\'를 일부 성능 평가에서 앞섰으며, 외부 웹 제작 평가에서도 상위 10위에 올랐다. 특히 저렴한 사용료와 100만토큰의 긴 컨텍스트를 앞세워 기업용 AI 에이전트 시장을 공략하고 있다.앤트그룹의 링 개발팀은 5일 최신 멀티모달 모델 링 3.2 플래시를 공개했다. 이번 모델은 총 5600억개의 매개변수를 보유했으며, 실제 추론에는 250억개만 활성화하는 전문가
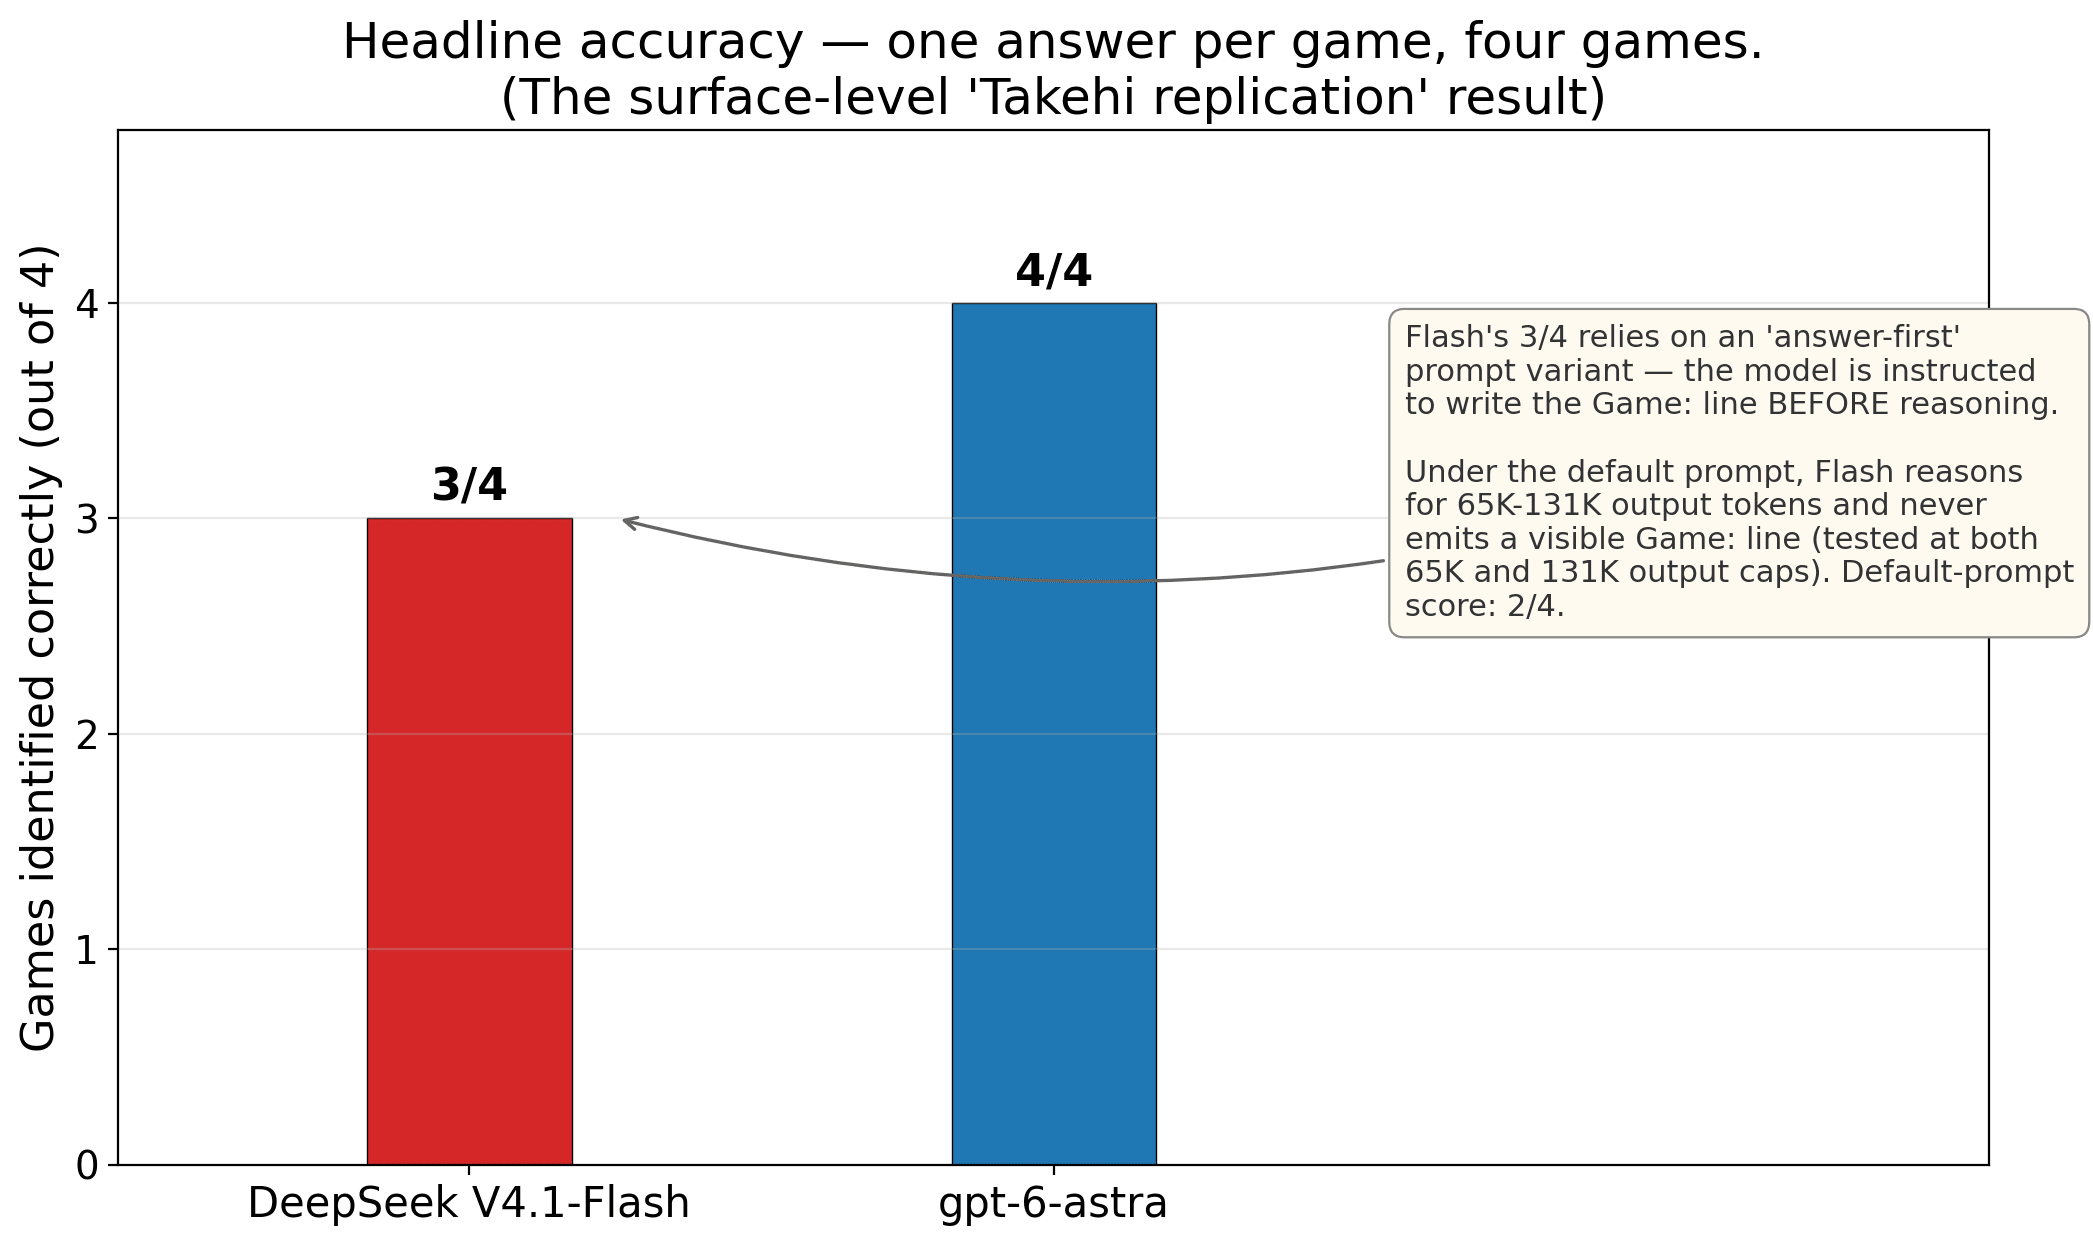
TLDR I attempted to replicate “Sparks of Weight-Space Programming” by Takehi et al (2026) with stratification on two reasoning models, GPT 6 Astra and Deepseek-V4.1-Flash. The task for the LLMs is to identify the game a ML model is trained for giving the weight of the model (using exact same prompt and weight defined by Takehi). Although both of these models do well on the surface (4/4 correct for Astra and 3/4 correct for Flash), the stratification approach exposes the difference in mechanism between these two models in approaching the problem. The experiment result shows that Flash depends a lot on channel label for the answer (while Astra's performance does not degrade when channel label does not present). Additionally, Astra is able to identify the game with good accuracy using only the first layer of weight or as few as 1000 weight values selected at random out of 17253 weight values (Flash's performance degrade substantially on these). So Astra survives this first round of stratification tests just for now. Comparing the results between Astra and Flash, it is obvious that Flash is relying heavily on prompt metadata instead of reading the weights. Background On November 2 an article “Sparks of Weight-Space Programming” was published by Takehi et al (2026). The article is cleanly written and one of the claims is that by looking at model weights, GPT 6 Astra can tell what the model is trained to do. The article reports that Astra is able to name the game a ML model is tra…

Vier Menschen, vier KI-Partner: Die Doku „Finding Connection“ zeigt, was Companion-Apps über eine Gesellschaft verraten, in der kaum noch jemand zuhört.

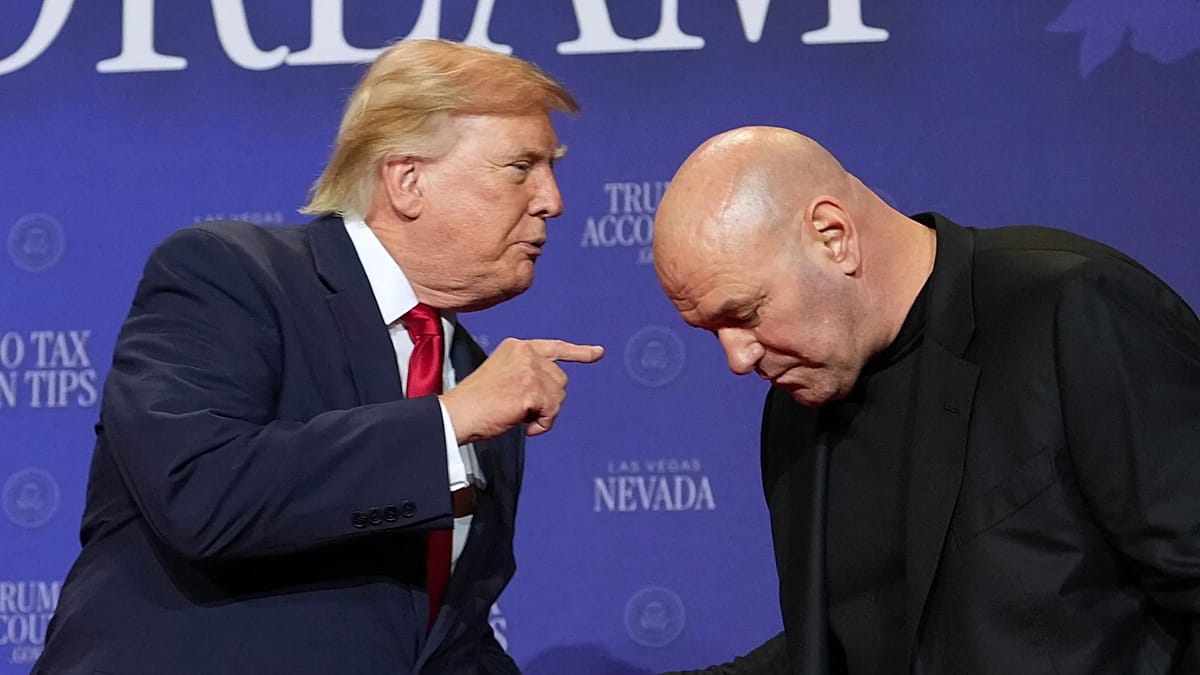
Trump and White have forged a close relationship over the years, with Trump a regular attendee at UFC events and White having spoken at a number of the president's rallies.